How Transformers Work - Attention Explained Step by Step | Chapter 06
Summary
The video explains the Transformer architecture, detailing how it processes text input through tokenization, embedding, and a stack of Transformer blocks to generate the next token. It breaks down the attention mechanism, multi-head attention, and feed-forward layers within a Transformer block, highlighting the differences between encoders and decoders.
Summary from the captured archive. Follow the original source for full context.
More from Ease With Data
 Tutorials
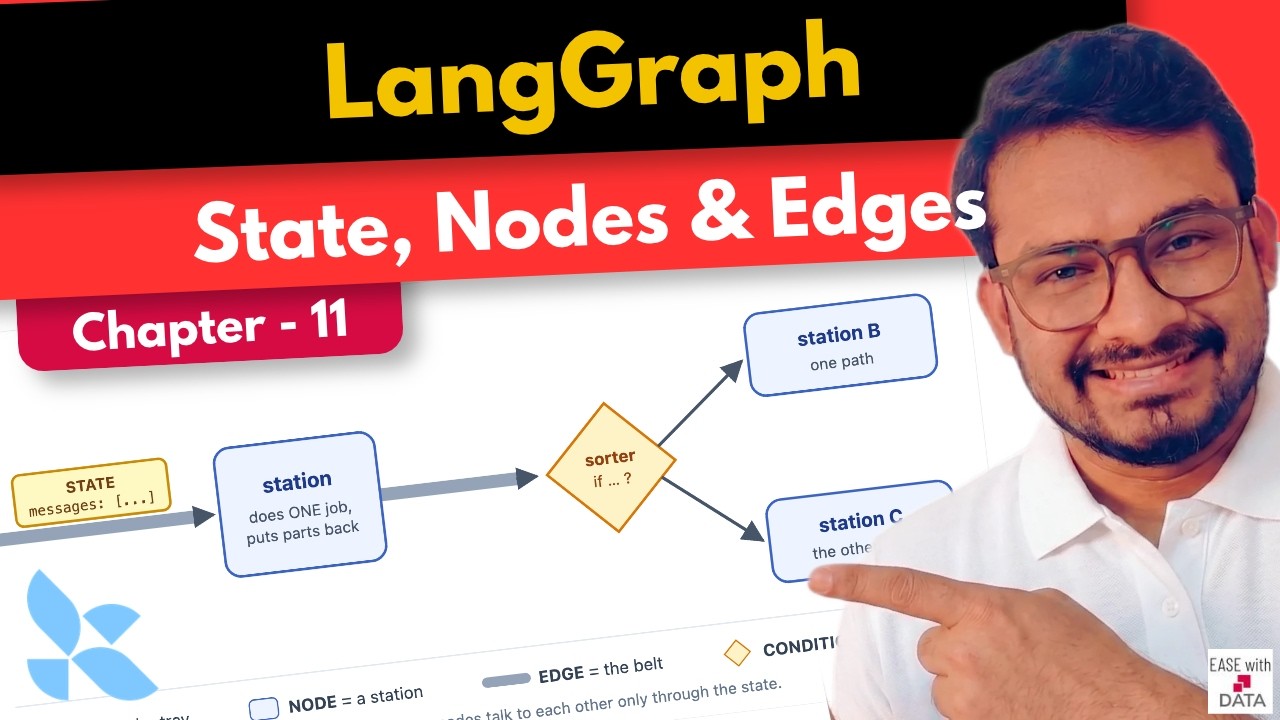
LangGraph Tutorial - State, Nodes and Edges | Chapter 11
LangGraph is introduced as a more controllable alternative to LangChain for building agentic workflows, offering fine-grained control over execution flows. The video demonstrates how to build a basic workflow using state, nodes, and edges in LangGraph.
 News
What are Agents & How they Work? #agent #llm #genai
AI agents combine a large language model for reasoning, external digital tools for executing actions, and memory for tracking context to complete complex tasks autonomously. This architecture allows the system to continuously loop through planning, executing, and adjusting steps until a defined goal, such as organizing a chaotic folder of files, is fully achieved.
 News
Forward Deployed Engineers (FDE) vs Data Engineers (DE) #fde #dataengineering
Forward deployed engineers embed with business executives to build custom AI models that solve specific problems like customer churn directly within legacy systems, contrasting with traditional data engineers who maintain data infrastructure and pipelines. They command premium salaries because they combine production-level coding skills with management consulting expertise to implement solutions without disruptive migrations.
 Tutorials
Databricks All Purpose vs Serverless Computes #databricks #databrickstutorial
Databricks all-purpose compute provides traditional persistent clusters with manual configuration and continuous uptime costs. Serverless compute offers fully managed infrastructure that boots in seconds, scales dynamically, and bills only for active execution time.
 Tutorials
LangChain Tutorial - Build an AI Agent with Tools | Chapter 10
This video teaches how to build AI agents using the LangChain framework in Python. It demonstrates initializing a model, registering Python functions as structured tools, and creating both single agents and supervisor-sub-agent architectures.
 News
Spark vs SDP, What the difference? #spark #pyspark #dlt
Traditional Apache Spark requires developers to manually write complex procedural code for processing steps, state management, and checkpoints. Spark declarative pipelines allow users to define the desired final data state in SQL or Python while the engine automatically handles execution order, dependencies, and incremental processing.