Financial Services
Recent items mentioning Financial Services across the Databricks ecosystem — releases, news, videos, and community Q&A. Updated hourly.
Financial-services teams are showing concrete payoffs from modern data stacks: Keep's one-person data team cut credit underwriting from a business day to under a minute on dbt, Artie, and Snowflake 3, while Obie Insurance dropped its month-end close from 25+ hours to 2 using dbt State and an Iceberg lake house rebuild 5. Verisk's move from mainframe to dbt added tests that halt pipelines before bad data reaches actuaries, now underpinning AI-assisted work 4, and Authentic Insurance is converting dbt DAG scheduling slack into Snowflake credit savings 2. On the AI side, Jev applies structured, non-generative systems to extract and tag insurance quotes and claims, cutting token usage and manual review 1.
Generated daily from the 8 most recent items mentioning Financial Services. Click any [N] to jump to the source.
 Tutorials
Practical Use Cases for Jev | System One Models - Part Three
Jev utilizes structured, non-generative AI systems for energy billing and customer service workflows with built-in safety controls. It also automatically tags and extracts sections from complex documents like insurance quotes and claims, significantly reducing token usage and manual review effort.
Why most of your dbt models aren't in a hurry, and what that's worth in Snowflake credits
Most models in a dbt DAG sit off the critical path, so they can run slower and cheaper without delaying the pipeline. Espresso AI and Authentic Insurance walk through how turning that scheduling slack into real Snowflake credit savings works in practice.
How a one-person data team at Keep built real-time banking infrastructure on dbt
Keep's one-person data team used dbt, Artie, and Snowflake to cut credit underwriting time from one business day to under a minute. The post walks through how that stack supports real-time banking infrastructure without a larger data organization.
From mainframe to AI-powered maturity: Verisk's data modernization journey
Verisk's underwriting data team moved from a mainframe to Snowflake notebooks, then native Snowflake objects, and finally dbt, which replaced hundreds of hand-coordinated tasks and tables with version-controlled models, self-documenting lineage, and tests that halt a pipeline before bad data reaches actuaries. That governed foundation now supports AI-assisted work, including a custom dbt Wizard skill that propagates doc-block descriptions across the DAG and a standards skill that checks pull requests, all with a human in the loop.
How Obie Insurance cut its month-end close from 25 hours to 2 with dbt State and a lake house rebuild
Obie Insurance rebuilt its data platform on dbt and Apache Iceberg in a lake house architecture, cutting a critical month-end close process from over 25 hours to 2 hours. The post walks through how dbt State and the lake house rebuild made that reduction possible.
Databricks Is Doubling Down On New York City As A Premier AI Talent Hub
Databricks is doubling its New York City office footprint to 120,000 square feet at 5 Bryant Park, adding a dedicated Engineering and Research floor alongside an Executive Briefing Center. The expanded location will house teams driving enterprise AI research, infrastructure such as Unity Gateway, and agentic applications like CustomerLake.
What do "real-world" data engineering data pipeline plans look like in traditional banking? #spring plans
submitted by /u/BSV_btw [link] [comments]
OLTP vs. OLAP: Choosing Between Transactional and Analytical Databases
Database architecture must directly follow workload requirements, balancing OLTP's point writes and immediate consistency against OLAP's broad historical scans. When bridging transactional and analytical systems, teams must also account for the synchronization overhead, pipeline effort, and analytical latency introduced by ETL and CDC.
CUSTOMER STORY | ANA Seguros turns insurance data into faster decisions with AI/BI and Genie
Financial data agents are going to play a vital role in modern banking systems.
submitted by /u/ConstantNo2668 [link] [comments]
Property & Casualty Insurance Lakehouse
"Regex for Rows": Simplifying Pattern Detection in SQL with MATCH_RECOGNIZE
MATCH_RECOGNIZE brings regex-style pattern matching to SQL, now in Public Preview, letting you detect sequences and patterns directly in event data. It's built for use cases like fraud detection in financial services, threat detection in cybersecurity, funnel analysis in e-commerce, and anomaly detection in manufacturing and IoT.
Community BrickTalk | Real-Time Data & AI: Tripwise Demo
Hey r/Databricks ! Join us for community BrickTalk on Thursday, September 24 , focusing on real-time data streaming, AI agents, and governance using Databricks. BrickTalks is a community event series where Databricks experts share real-world use cases, demos, and practical insights for building with Data and AI, giving customers a direct line to the people behind the products. In this session, we'll walk through a live demonstration of the Tripwise Demo , featuring: Sub-Second Transactions & Streaming: Device registration into Lakebase with sub-second reads/writes, plus telemetry streaming via Zerobus through a governed Medallion architecture. AI-Generated Offers & Pricing: Generating real-time agent offers using Foundation Model APIs and scoring behavioral data for usage-based renewal pricing. Natural Language Analytics: Enabling underwriters, product managers, and marketing teams to query governed insurance data in seconds using AI/BI Dashboards and Genie. Unified Governance: Managing safety, compliance, and control end-to-end with Unity Catalog. This is a great chance to see real-world architecture in action and ask questions directly to Databricks experts. When: Thursday, September 24 9:00 AM PT 12:00 PM ET 5:00 PM BST (London) 9:30 PM IST Register here and save your spot submitted by /u/Subject_Ant1789 [link] [comments]
Five AI Questions We're Hearing from Financial Services Leaders
Transitioning financial services AI from pilot projects to governed production deployments hinges on addressing five key questions shaping the industry. Learn how Databricks unifies data, AI, and governance across financial crime, banking, and wealth-management workflows, and connect with leaders at Sibos 2026 in Miami.
A practical approach to end-to-end Solvency II reporting in Databricks
Databricks now supports Solvency II end to end, connecting data ingestion, reserving, capital calculation, governance, and disclosure into a single workflow instead of fragmented systems and teams. A demo shows how this unified approach delivers one control view, governed automation, AI-assisted review, and faster scenario analysis for reporting readiness.
How Discovery Bank delivers hyper-personalized banking at scale: behavioral AI, governed data, and real-time decisioning
Discovery Bank achieved a 40% uplift in client engagement impact by building reusable, AI-driven data products and real-time next-best action models on Databricks. Their architecture accelerates data pipeline workflows by 20x and data product creation by 5x while ensuring AI agents operate within existing governance controls.
Insurance Intelligence Copilot – Powered by Databricks Genie
Vertical Advantage: Transforming Industries with Lakebase and Agentic AI
Databricks Lakebase partners are shipping production-ready, industry-specific solutions—from fraud and regulatory-change agents to real-time claims, prior authorization, dynamic pricing, and grid intelligence—built on a single governed foundation for operational data, analytics, and AI. Powered by Lakebase's serverless Postgres, sub-10ms operational serving, zero-copy branching, and agent-native memory, these solutions are deployable today and designed to turn platform capability into measurable business value.
Data Mesh vs. Data Fabric: Key Differences and How the Lakehouse Resolves the Debate
Lakehouse architecture ends the mesh-versus-fabric tradeoff by pairing domain-owned data products with centralized governance enforcement, so teams ship analytics and ML products fast without fragmenting compliance. The result, per examples from financial services, healthcare, and retail, is better data quality and lower integration overhead alongside the accountability gains mesh ownership brings.
Relational vs Non-Relational Database: Choosing the Right Data Store
Relational databases enforce schemas and ACID transactions with vertical scaling and strong consistency, making them the right fit for mission-critical systems like banking, healthcare, and e-commerce; non-relational databases trade that for flexible schemas and horizontal scaling with eventual consistency, suited to high-volume workloads like social media, real-time analytics, and IoT. The post breaks down these tradeoffs to help practitioners match the data store to the workload rather than defaulting to one model.
AI Applications in Finance: A Practical Use Case Guide
Scaling AI across core financial operations like credit scoring and fraud detection requires disciplined governance, including explainable models, documented data lineage, and human-in-the-loop checkpoints. A phased framework centered on two prioritized pilots, a 90- to 120-day evaluation window, and rigorous ROI measurement provides teams with a low-risk path to enterprise-wide deployment.
Launch HN: Parsewise (YC P25) – Reason Across Documents with an API
Hi all, it’s Greg and Max, founders of Parsewise here (https://www.parsewise.ai/api). Parsewise transforms a bucket of unstructured data into schema compliant data, retaining lineage for values resolved across documents. Imagine giving Claude a bunch of files and asking for a CSV or JSON output. If you have tried this, you know both the system limitations (number of files, type of inputs, cost, latency) but also the human-facing challenge of having no way to validate the results quickly. We solve both. We help tech teams simplify their unstructured data ETL, and loop in business experts for the definitions and for instant validation. Here is a video with a few use cases: https://www.youtube.com/watch?v=dbRllnnh47w Parsewise in the words of someone coming to us: ”I need to extract information from insurance policy PDFs, phone calls that have been transcribed, emails, etc. I am NOT looking for something that would just extract data point by data point, page by page into a structured well-defined schema but more something more agentic that can understand that information might be across documents and that it should reason over what to extract.” We started the company based on a decade of experience (and pain) in complex data transformation and data analysis / synthesis. Greg was building both classical ETL and implemented AI workflows at Palantir. At Bain, Max did highly complex data analysis in the financial sector, similar to many of our customers. Parsewise works by taking in a bucket of data (think hundreds or thousands of pdfs, excels etc.), and outputting schema compliant data where every single value is traceable down to word level citations across multiple documents in the bucket. We provide API customers with ways to show the lineage in their own applications, or they can use our platform for internal operations. At the core of the data processing we have self-improving agent definitions. They define the acceptable sources, the logic for resolving or combining values, and the rule for highlighting uncertainty to the end user. The underlying tech is model and cloud agnostic and can be deployed in private networks. We have seen the best results with Gemini models for visual reasoning, achieving SOTA (beating Claude Fable) on the strongest grounded reasoning benchmark we have found (Databricks OfficeQA). Notably, we focused more on the “human harness” rather than the model harness, leaning into the actual friction we saw in uptake, which is around verifiability. That means optimizing the time and clicks required to trust the outcomes. We use vLLMs for parsing, and then we use small models for efficient large scale exhaustive search. Unlike RAG, we do not sample; instead, we exhaustively find all relevant values for a given query. We use larger models for decision making around resolutions and flagging inconsistencies to users. This exhaustiveness and explicit value sourcing is unique to our platform, and it goes beyond the first step of data parsing that many existing providers cover. We would love to welcome builders and tinkerers to try Parsewise on your complex document challenges. We have a ton of ideas on how we can expand the product and make it better, but would appreciate feedback and ideas from the community! --- top comments --- [whinvik] Document parsing is top of my mind lately because in some of the areas we work on the bottleneck is starting to become being able to query documents the same way one queries an api. I keep thinking the most obvious analogue is we need some way to represent documents the same way we can represent structured data in parquet. Parquet allows easy range bases queries and there is so much tooling built around Arrow. But for documents I keep hitting a wall to figure out what the right abstractions are. Parquet allows filterable metadata. But what such metadata is there for documents. Then there is the arbitrrariness of chunking, vectorization. If we could just do this in a […truncated]
 Events
How Mastercard standardizes on Lakebase to power agentic operations
Mastercard uses Lakebase to standardize its agentic operations, creating a shared foundation for services like the "virtual C-suite" for small businesses and secure multi-tenant solutions for thousands of issuing banks. This standardization enables rapid development of AI agents with embedded governance and trust, allowing them to learn from each other and scale effectively.
Announcing the 2026 Databricks Customer Awards Industry winners
The 2026 Databricks Customer Awards Industry winners have been announced, recognizing ten organizations across diverse sectors like financial services, healthcare, and manufacturing. These winners showcase compelling data and AI stories, demonstrating how they've leveraged Databricks to solve complex challenges and achieve measurable results.
Data + AI Summit 2026: Insider’s Guide for Financial Services Leaders
Data + AI Summit 2026 offers a financial services executive guide to key banking, insurance, payments, and capital markets sessions. Learn how leading organizations like Morgan Stanley and JPMorganChase are approaching AI transformation, responsible AI, and operational modernization, with practical strategies for maximizing summit value.
How Databricks Genie democratizes data access in financial services
How Databricks Genie democratizes data access in financial services
Databricks Genie now democratizes data access for financial services business leaders by enabling natural language querying of governed data. This eliminates the "Last Mile of Data Democratization" by removing the need for SQL skills or BI tool training.
Transforming industries with conversational AI: Partner solutions built on Databricks Genie
Databricks Genie now powers innovative, industry-specific conversational AI solutions from leading consulting and SI partners. These ready-to-deploy offerings accelerate enterprise AI transformation across financial services, healthcare, retail, and other key sectors.
Agent Bricks in Action: Automating Insurance Underwriting with a Supervisor Agent-Led Architecture
Have a phone screening tomorrow with the recruiter for the RSA position. Anything I should know?
I applied to the RSA position within Financial Services and Public Sector (currently holding a secret clearance) and not sure which department the screening is for. As it’s just a screening is there anything I need to do to prep? I’m currently a senior consultant with the Big4 in the public sector and I’ve used Databricks in the past and enjoyed the tool and would love to get immersed in the tool. Databricks is on my list of dreams companies to work for. If I get past the screening I’ll use the community edition over the weekend to get refreshed with the platform.
 News
AI for Data Intelligence Demo: Real-time fraud Detection with Databricks
Databricks demonstrates a real-time fraud detection solution for identifying mule accounts in banking, leveraging a unified data architecture, advanced AI/ML, and graph analytics to uncover complex fraud networks. The solution provides investigators with a single pane of glass application and AI-powered querying (Genie) to analyze risk scores, transaction patterns, and shared device access for efficient fraud investigation and reporting.
 News
2026 & Beyond: Agentic Future in Finance
Databricks emphasizes that an "agentic future" in finance requires organizations to leverage their unique, proprietary data to provide context to AI models, which is the true competitive advantage. The video demonstrates how Databricks' platform centralizes and governs enterprise data, enabling AI agents to make informed, secure, and differentiated business decisions.
Peril Predicts: Precision Payouts for a Volatile World
Databricks now helps insurers operationalize parametric insurance workflows, enabling faster catastrophe payouts using objective event triggers. The Geospatial Lakehouse facilitates ingesting catastrophe data and analyzing exposure at scale, essential for reducing basis risk and defining accurate payout triggers with geospatial analytics and catastrophe modeling.
Model Risk Governance Is Not the Same as Risk Intelligence
Databricks AI/BI Genie for Enterprise Risk Intelligence now enables conversational interrogation of governed risk data, providing instant, accurate answers for real-time risk management. This closes the intelligence gap for CROs who previously navigated complex model outputs and data systems to get specific answers on credit concentration or stress test sensitivity.
 News
How Techcombank Scales AI Banking to 16M Customers with Databricks
Techcombank uses Databricks to power its AI banking platform, serving 16.2 million customers and processing 8 billion daily transactions with a 12,000-plus feature store. This enables the bank to make data-driven decisions, automate lead allocation with over 8,000 features, and achieve a 3x conversion uplift, improving both productivity and customer experience.
Beyond the spreadsheet: how Databricks is delivering the modern CFO in Financial Services
Databricks now offers a unified architecture for Financial Services CFOs, integrating real-time data, AI modeling, and governance to eliminate data fragmentation and slow reporting. This enables a shift from reactive reporting to strategic finance, with benefits like drastically reduced regulatory reporting times and AI-powered natural language querying of complex financial data.
 News
Sponsored: EY | Business Value Unleashed: Real-World Accelerating AI & Data-Centric Transformation
Ernst and Young demonstrates two real world databricks use cases for accelerating AI and data transformation, including a retail inventory optimization and demand forecasting model that saved a client over one hundred million dollars in working capital. The presentation also highlights an emerging generative AI solution that processes satellite imagery to make geospatial data searchable through natural language for business users.
 News
Data Democratization with Lakehouse: An Open Banking Application Case
Bradesco implements an open banking and data democratization architecture using the Databricks lake house platform. The solution uses delta sharing, medallion layers, and Unity Catalog to ingest, transform, and securely share financial data across business units and partners.
 News
Sponsored: dbt Labs | Modernizing the Data Stack: Lessons Learned From Evolution at Zurich Insurance
Zurich Insurance migrated its traditional data stack and on-premise Hadoop clusters to a modern cloud-based lake house architecture powered by Databricks, Delta Lake, and Unity Catalog. The organization uses a hybrid approach combining a low-code ingestion product for data extraction and load with dbt and Python for streamlined transformations and data modeling.
 News
Journey Towards Uniting Metastores
Nationwide Insurance details its enterprise-wide journey of adopting and implementing Databricks Unity catalog to unify its data lakehouse architecture and governance. The presentation outlines key challenges faced, a four-phase rollout strategy, permission hierarchies, and the successful adoption of Delta sharing.
 News
Clean Room Primer: Using Databricks Clean Rooms to Use More & Better Data in your BI, ML, & Beyond
Databricks clean rooms enable organizations to securely collaborate and commingle data, models, and code across different cloud platforms without sharing raw underlying assets. The platform demonstrates how businesses in retail, healthcare, financial services, and media can execute SQL and Python workloads to unlock previously restricted BI and machine learning use cases while maintaining privacy and governance.
 News
Sponsored by: Wipro | Personalized Price Transparency Using Generative AI
Wipro demonstrates a generative AI solution built on Databricks that helps healthcare patients easily search and compare complex medical treatment costs from public machine-readable insurance files. The system uses a conversational assistant powered by large language models and the Vega governance framework to answer multi-part questions about out-of-pocket expenses and in-network hospital options.
 News
Scaling Privacy: Practical Architectures and Experiences
The video demonstrates how to implement governed agile data science workflows using Privacera with Databricks to manage fine-grained access control, logging, and data governance for machine learning models. It shows practical examples of configuring resource policies to secure data and track access across different datasets and MLflow paths.
 News
Productionizing Ethical Credit Scoring Systems with Delta Lake, Feature Store and MLFlow
Productionizing ethical credit-scoring models presents operationalization challenges that can be addressed by applying specialized fairness metrics and model registries. Delta Lake and MLflow can be used to build a production-ready credit-scoring system that is reproducible, quantifiable, and auditable.
 News
Computational Data Governance at Scale
Fozzy Group, a holding of about 40 businesses, implements Data Mesh using federated computational data governance to tackle unclear data ownership. It covers building global data lineage across 200k tables, 40k table replications and 70k SQL stored procedures, plus lessons from automated tracking of ownership and data quality.
 News
Graph-based stream processing
Graph analytics applied to streaming data supports real-time decisions where the underlying domain is easily modeled as a graph. Fraud detection, recommendation engines and process optimization in industries from marketing and financial services to transportation serve as example use cases.
 Events
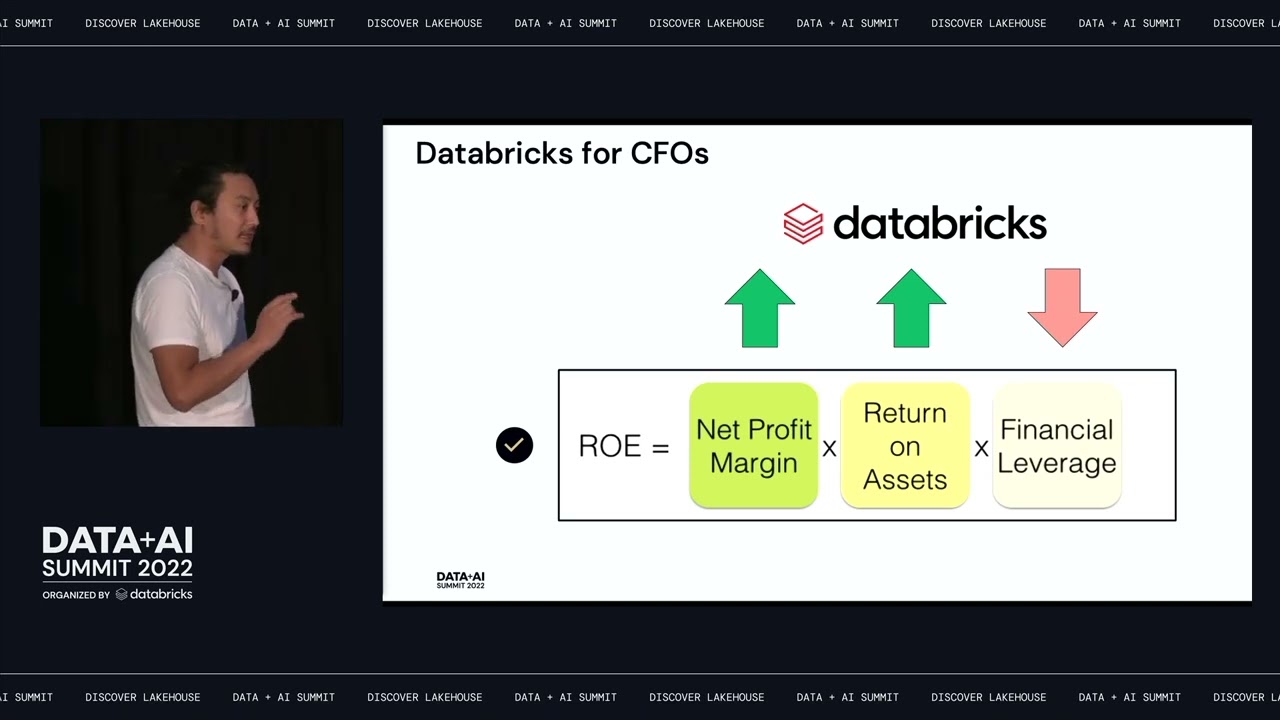
Financial Services Experience at Data + AI Summit 2022
The Financial Services program at Data + AI Summit 2022 focuses on how financial leaders use data and analytics to transform, minimize risk and create value. It features an industry forum with ADP, Northwestern Mutual, Point72 Asset Management, S&P Global and EY, a partner lounge, and over 15 technical talks and demos.
 News
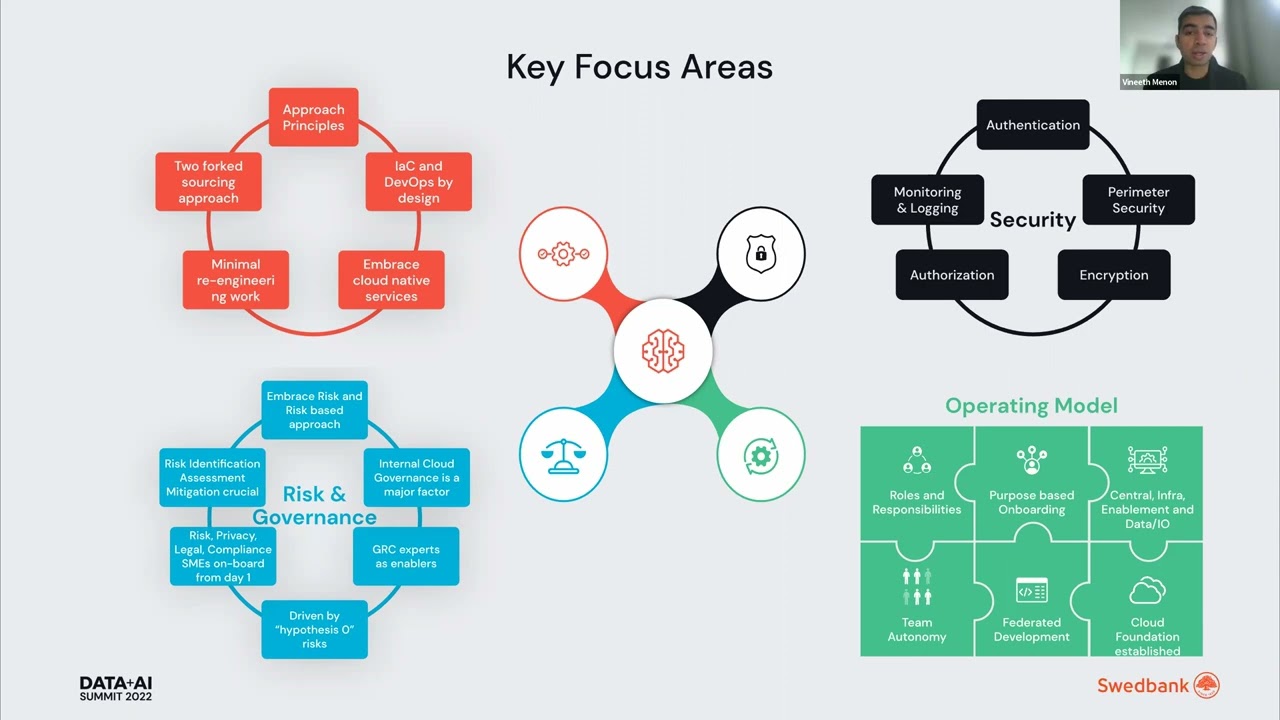
Swedbank: Enterprise Analytics in Cloud
Swedbank, Sweden's largest bank, moves its on-premise Hadoop data lake to the cloud on Azure Databricks, with Immuta as its unified access control plane. A data discovery space lets data scientists develop and operationalize ML models under granular access controls, and key technical challenges, learnings and benefits of the journey are shared.
 News
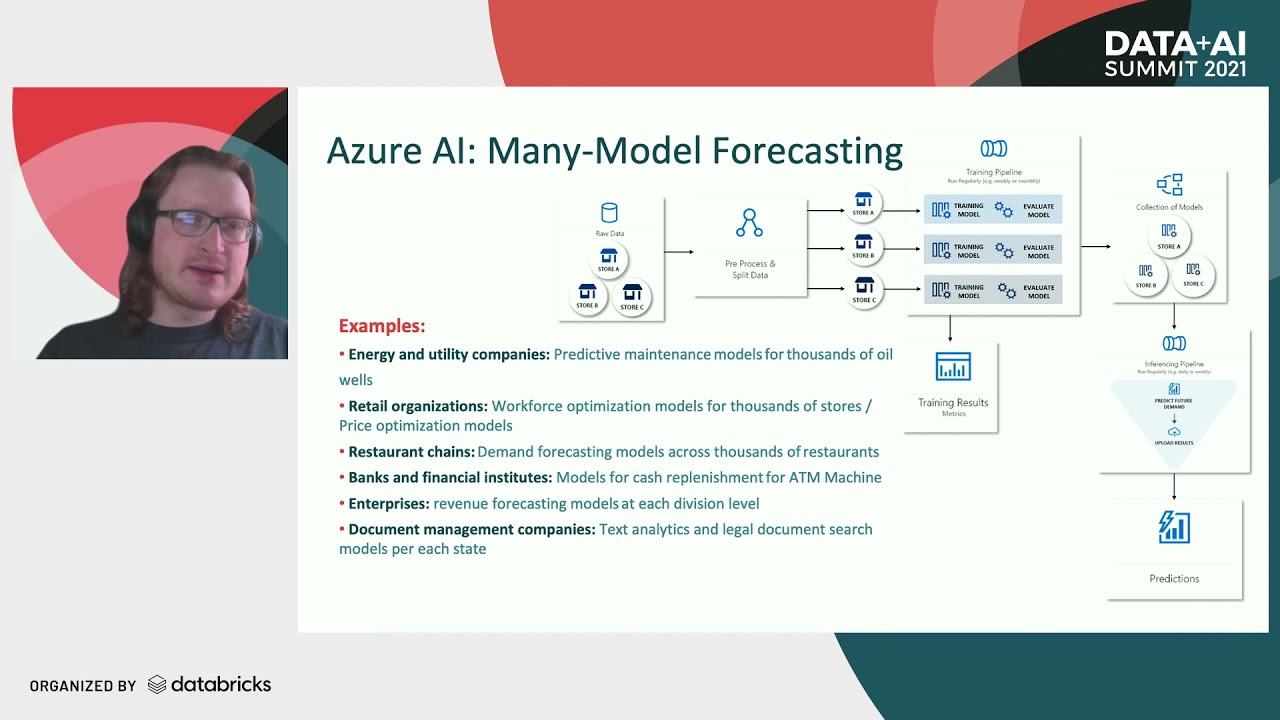
Auto-Train a Time-Series Forecast Model With AML + ADB
Azure Machine Learning running on Azure Databricks compute enables large-scale many-models forecasting for industries such as supply chain, healthcare, insurance and finance. The demo builds a time-series forecasting model in Azure Databricks with Azure AutoML, using MLFlow for lifecycle management and Hyperopt for distributed model execution.
 News
Credit Card Fraud Detection Using ML In Databricks
Credit card fraud detection is framed as predicting whether a card was used by its cardholder, using machine learning models in Databricks. Models are trained on credit card transaction data along with card and demographic information about account owners to detect fraudulent transactions more dynamically.
 Events
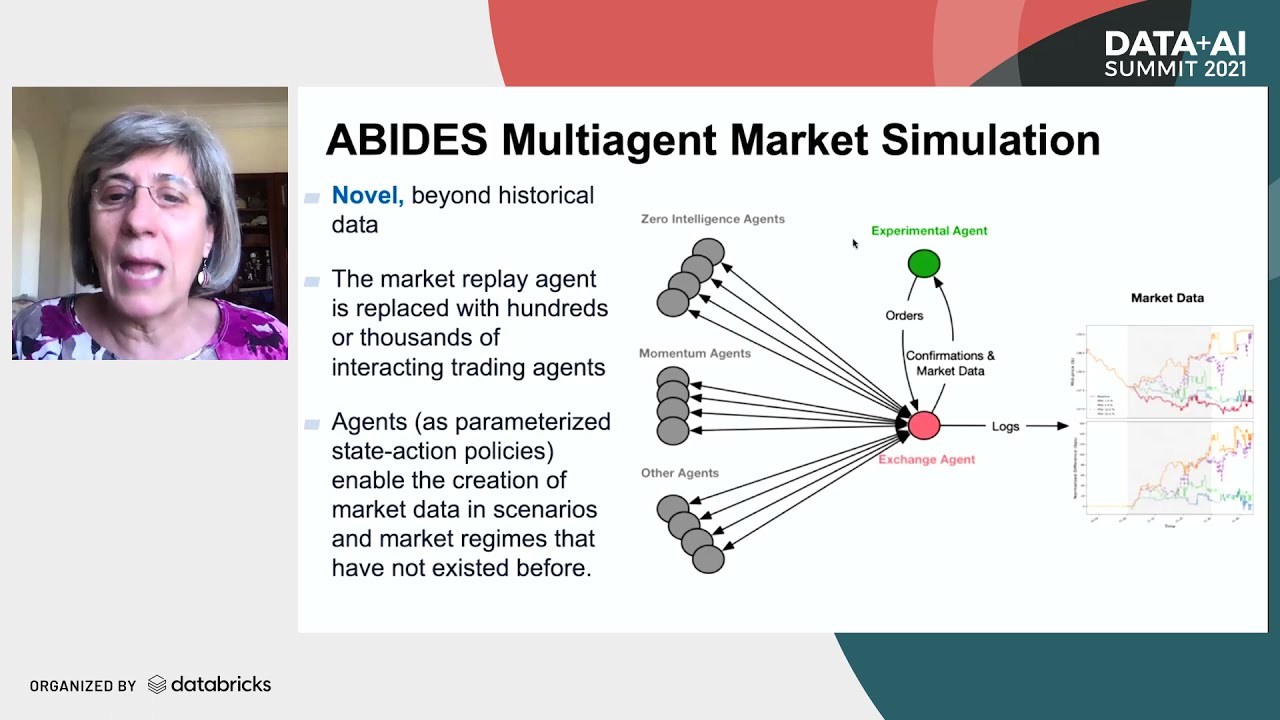
AI for Intelligent Financial Services | Manuela M Veloso | Keynote Data + AI Summit NA 2021
Dr. Manuela Veloso, former head of the Machine Learning Department at Carnegie Mellon University, discusses AI for intelligent financial services. Her keynote spans NLP, financial market simulation and financial fraud, drawing on her academic research and her experience co-founding the RoboCup robotics competition.
 News
Healthcare Claim Reimbursement using Apache Spark
Optum is replacing an Oracle-based claim processing system with Apache Spark, Scala and Java to evaluate millions of hospital claims per day in under 8 hours. Moving claim ingestion from PL/SQL to Spark improves performance by 50% and cuts cost, while Spark opens up streaming, simpler testing, cheaper cloud operations and machine learning.
 Tutorials
Using Bayesian Generative Models with Apache Spark to Solve Entity Resolution Problems at Scale
Entity resolution finds duplicate or near-identical profiles that represent the same real-world entity, a task where brute-force comparison on datasets over roughly 10 million records becomes infeasible. A Bayesian statistical sampling approach on Spark matches records at scale using KD-tree partitioning to distribute data across nodes, plus attribute similarity functions.
 News
Top Down Specialization Using Apache Spark
Top-Down Specialization, a data anonymization algorithm that balances data utility and privacy, is implemented in parallel on Apache Spark and evaluated on datasets of up to 20 million rows across cluster environments. Speedups by data size, partition sizing, driver versus executor work and scale-up experiments are analyzed.
 News
Cloud and Analytics – From Platforms to an Ecosystem
Zurich North America runs a self-service data science ecosystem built around Databricks, integrating the Azure data lake with analytical tools across the project lifecycle. It combines Spark, R and Python ML tools and the Alation Data Catalog for exploration and model building, and uses cloud services, containers and DevOps to operationalize models.