Structured Streaming
Recent items mentioning Structured Streaming across the Databricks ecosystem — releases, news, videos, and community Q&A. Updated hourly.
Spark Structured Streaming Real-Time Mode is now the backbone of Databricks' operational use cases, feeding sensor and market data into Lakebase (serverless Postgres) for a manufacturing digital twin 1 and for live energy trading and risk analytics, all governed through Unity Catalog 49. Pipelines can now write to one managed Unity Catalog table from multiple sources with one flow per source, and existing streaming jobs migrate via checkpoint import without reprocessing source data 3. Python Asynchronous TransformWithState is now GA 5.
Generated daily from the 10 most recent items mentioning Structured Streaming. Click any [N] to jump to the source.
 News
Creating a Digital Twin with Spark Real-Time Mode and Lakebase
This video demonstrates how to create a real-time digital twin for a manufacturing cell using Databricks tools such as Spark Real-Time Mode, Lakebase, Databricks Apps, and Unity Catalog. It explains how processing sensor readings instantly allows operators to detect and act on equipment faults, such as a hot spindle, before they negatively impact production quality and efficiency.
Need help with alternatives for dropMalformed and Schema Registry URL not supported for Kafka source on a Shared cluster
Hello, We are migrating from Hive metastore to UC and in a phase where we are testing before pushing the upgraded code to production. The issue we are facing is we have Kafka Structured Streaming jobs which are using Dedicated clusters earlier but going forward we will only be using Shared clusters and Serverless eventually. But the Streaming jobs are failing with errors dropMalformed are not supported for Data source Kafka on a Shared cluster kafka.schena.registry.url are not supported for Data source Kafka on a Shared cluster Did anyone face a similar issue and found an alternative to make it work on Shared clusters ? Kindly help us with resolving this. Thankyou submitted by /u/Its__Ram [link] [comments]
 Tutorials
Databricks Pipelines: Write to One Unity Catalog Table from Multiple Sources with FLOWs
Databricks pipelines now allow writing to a managed Unity Catalog table from multiple sources by using one flow per source. Users can migrate existing structured streaming jobs without reprocessing the source data by utilizing checkpoint import features.
Real-time energy trading and analytics on Databricks
Energy trading teams can run live trading and analytics on one Databricks platform instead of separate systems that leave risk data stale and governance duplicated. Spark Structured Streaming Real-Time Mode streams market data into Lakebase (serverless Postgres), which feeds the trading app, ML models, dashboards and Genie One, while Unity Catalog handles permissions, lineage and audit once for all of it.
Python Asynchronous TransformWithState for Streaming is now GA
Hi folks, we are excited to announce that Python Asynchronous TransformWithState (Async TWS) is now GA for Structured Streaming. What is it? Async TWS speeds up stateful streaming queries in Python by executing the stateful processor concurrently across keys and batching state store operations, which can improve throughput by up to 3x. The async API mirrors the existing synchronous TransformWithState : You implement AsyncStatefulProcessor instead of StatefulProcessor and apply asyncio syntax changes (e.g, async def and await ). Third-party async libraries are welcome but not required to start seeing performance gains. The AsyncStatefulProcessor is a drop-in replacement for the StatefulProcessor so you can switch implementations while reusing your checkpoint. See here for examples. What is supported Python row-based transformWithState Both Micro-Batch and Real-Time Mode DBR 19+ or serverless compute with environment version 6+ Structured Streaming; SDP on the Preview channel, with SDP Classic enabled once it reaches DBR 19 Because handleInputRows and handleExpiredTimer now run concurrently across keys, make sure any shared member state or external calls are safe for concurrent execution. Learn more at https://docs.databricks.com/aws/en/stateful-applications/async Questions and feedback welcome in the comments. submitted by /u/New_Woodpecker_1631 [link] [comments]
Databricks in a SaaS product, and the realtime mode
Hey everyone, i have two questions about databricks and I’d like to hear about your experiences: 1. I have seen a lot of companies who use databricks for their own internal needs and that makes sense. But have you ever seen a SaaS product that uses databricks? For example a products that process customer data to provide some value? Do you know if there is any company that uses databricks structured streaming realtime mode in production? Do you know if they are happy with it? I am asking this because it is a new offering and there is no support for features such as auto scaling (unless if you are using lakeflow pipelines). And i assume it is super expensive as you need a core for every task slot. submitted by /u/shanfamous [link] [comments]
Structured Streaming job on a job cluster ends with "driver unresponsive" after 8-12 h, with a healthy heap and plenty of memory
Setup Azure Databricks, job cluster, Python script task (not a notebook). The JVM runs JDK 21 with ParallelGC and a 101 GB heap, on a driver with 128 GB. 2 workers 28gb 4 cores each. About 7-8 Structured Streaming queries share one driver. They use foreachBatch, and each batch holds roughly 1 record (0.1-0.2 records/s). A batch takes about 6-7 s, with spikes of 12-16 s, and almost all of that time is addBatch. Inside foreachBatch on the driver there is an in-process cache with a TTL. One thread refreshes it under a lock while the others keep serving the old snapshot. Problem After roughly 8-12 hours the run ends. The driver log contains a "DRIVER UNRESPONSIVE STATS" block, and the event log only shows the cluster terminating, with no OOM, resize or eviction. 1 job 8 tasks, all report that driver became unhealthy.. What the metrics show before the crash Driver container memory grows slowly from about 45 to 58 GB, with a 128 GB limit. JVM heap shows a normal sawtooth with no trend. In the dumps, old gen is at 10-19% and metaspace at about 450 MB. Worker-side GC events rise from about 5 to about 70 per interval, and GC pause time from about 0.2 s to 1.5 s per interval. The GC count is high just before the crash, even though memory is nowhere near its limit. What the driver dumps show In one dump, three threads are BLOCKED in ClassLoader.loadClass. They wait on monitors of Databricks' LibraryClassLoader and DriverCorralClassLoader, and one comes in via Janino (findIClass → Class.forName). The thread holding the lock is not in the output, and I can't tell how long they had been waiting. The dump from another crash had no blocked threads at all. Other observations The log shows 16 separate Python processes connecting through Py4J at startup, and another 16 about 30 s later. I don't know why. The same logic ran for more than 72 h on serverless without problems. As far as I know, serverless can't use a continuous trigger, so each micro-batch is a fresh start there. That is not a like-for-like comparison. Questions Is class-loader lock contention on the driver with many concurrent streams a known problem? Could it make the driver miss its health check? What else causes "driver up but not responsive" when heap and metaspace look fine? Is there guidance on how many streaming queries one driver can handle? Which diagnostics would you capture? I am now taking jcmd Thread.print dumps while the JVM is stuck, to see who holds the lock. submitted by /u/Just-Vegetable3622 [link] [comments]
Spark writeStream inefficiencies for N sinks
In Spark Structured Streaming when the stream writes to a output table (sink) you will typically use writeStream (other option is foreachBatch) writeStream has many benefits (fault tolerant...checkpoint per sink etc) but one issue is that it will process the source N times where N is the amount of sinks/ output tables you have. So lets say for a bronze -> silver app, where it reads bronze, transforms the data (eg. explode) and then writes to 4 silver tables. In theory this will be inefficient as the source read, deserialize, explode will happen 4 times (once per sink) This happens as it is visible in the logs, 4x logs of source read etc This is the theory... has anyone experienced this in practice? is there actually a 4x slowdown or inefficency? Would introducing an intermediate table help as this would remain 1-1 with only one sink thus no issue.... but introduce extra write cost + read + extra storage layer What is best practice here? (foreachBatch is not an option due to any possible data loss) submitted by /u/BigDaddyData187 [link] [comments]
 Tutorials
Run Live Energy Trading, Risk, and Analytics in Databricks
Databricks enables real-time energy trading and risk management by combining Spark Real-Time Mode and Lakebase for unified operational and analytical data processing. The platform provides a single source of truth with Unity Catalog governance, streamlining trading desks, price forecasting, and reporting within one environment.
What Databricks feature do you use every day but couldn’t explain under the hood?
Mine used to be Structured Streaming checkpoints. I’d used them for months before I really understood what gets stored in there, and why deleting or reusing one quietly breaks a stream. I’m a trainer and I spend most of my week explaining this stuff, so post yours. I’ll try to answer every one: how it actually works underneath, no hand-waving. Bonus points if you say what specifically feels fuzzy: what it does, how it does it, or when to pick it over something else. submitted by /u/UnluckySugar610 [link] [comments]
Streaming On-Demand State Repartitioning is now GA
We are excited to announce that Streaming On-Demand State Repartitioning is now Generally Available for Structured Streaming and Spark Declarative Pipelines. This enables you to seamlessly change the number of partitions for your stateful streaming queries without losing the existing checkpoint. 📚Learn More Doc : https://docs.databricks.com/aws/en/structured-streaming/state-repartitioning Blog : https://www.databricks.com/blog/announcing-demand-state-repartitioning-apache-sparktm-structured-streaming-databricks Give it a try! submitted by /u/Ok-Brick-001 [link] [comments]
Announcing On-Demand State Repartitioning for Apache Spark™ Structured Streaming on Databricks
Databricks now supports on-demand state repartitioning for stateful Structured Streaming queries: set spark.sql.streaming.stateStore.partitions and restart on DBR 18+ with the RocksDB state store provider to redistribute state to a new partition count without rebuilding the checkpoint. This lets you resize long-running streams to match workload demands and monitor each resize through query progress metrics.
Read this if you use Streaming Tables in Lakeflow Spark Declarative Pipelines
🚀 We’re excited to announce that Lakeflow Spark Declarative Pipelines (SDP) now supports creating “vanilla” (i.e., non STREAMING) MANAGED TABLES and writing to them via one or more append flows , using the new CREATE TABLE ... FLOW ( SQL ) and create_table() (Python) APIs . What is this Beta? This Beta allows creating a managed table that is populated by append flows: CREATE TABLE ... FLOW (SQL) / create_table() + @append_flow (Python) create a managed table written by one or more flows. Fan multiple sources into one table — declare several flows targeting the same managed table. Full table surface works: partitioning, liquid clustering, expectations, row filters, table properties, and private (pipeline-local) tables. import_checkpoint on append_flow , which migrates an existing Structured Streaming workload into a pipeline without reprocessing the source — the flow imports the query's existing checkpoint and resumes from the last committed offset with state intact. Example (Python): from pyspark import pipelines as dp dp.create_table("combined") dp.append_flow(target="combined") def from_a(): return spark.readStream.table("source_a") u/dp.append_flow(target="combined") def from_b(): return spark.readStream.table("source_b") Example (SQL): CREATE TABLE events PARTITIONED BY (bucket) FLOW INSERT BY NAME SELECT id, bucket FROM STREAM read_files('abfss://my_path', format => 'json'); Where do we need help? We are in Beta, so there might be some rough edges. Please take this for a spin and share your feedback here . What’s next? Managed Tables support for other flow types (AutoCDC, Replace Using, and Replace Where) is coming soon! Learn more CREATE TABLE ... FLOW (SQL reference) — https://docs.databricks.com/aws/en/ldp/developer/ldp-sql-ref-create-table-flow create_table (Python reference) — https://docs.databricks.com/aws/en/ldp/developer/ldp-python-ref-create-table import_checkpoint on append_flow — https://docs.databricks.com/aws/en/ldp/developer/ldp-python-ref-append-flow Questions, feedback, or help: comment below or share feedback in the form: https://forms.gle/7bGP5FYN7P1Z4WP27 submitted by /u/SlightImagination250 [link] [comments]
Do small companies actually use Databricks?
Sometimes I feel like Databricks is way too expensive. It feels like using a huge truck to move a single grain of sand. My company needs real-time data, but our data volume simply does not justify the use of Spark Structured Streaming. Despite this, they are insisting we move to Databricks. I'm worried our data infrastructure costs will jump from $1,000/month to $5,000/month or more due to the running costs of Databricks SQL Warehouses. Currently, I use Azure Container Apps with KEDA and Python, which helps me manage scaling and keep costs low. We ingest into Event Hubs, use ADX (Azure Data Explorer) as our OLAP warehouse, and archive cold data in a data lake. With this setup, I manage to process all our data with very low latency. When I tested this on Databricks Structured Streaming, I actually got higher latency and much higher costs. Would love to know what you guys think. submitted by /u/Puzzled-Mail-9092 [link] [comments]
Automatic change data feed is now generally available!
With automatic CDF, Databricks computes row-level changes at read time using row tracking, rather than materializing those changes during every write. Use change data feed on Databricks | Databricks on AWS Why does that mattre? - Better write performance for MERGE INTO and UPDATE workloads - No need to enable CDF individually on every eligible table - Lower storage overhead compared with legacy CDF - The same familiar APIs still work: table_changes() and readChangeFeed - Works with batch processing, Structured Streaming, and Databricks-to-Databricks Delta Sharing For Delta Lake, the main requirements include: • Databricks Runtime 19 LTS+ • A managed table or external table in Delta Lake format with row tracking enabled And if you’re already using legacy CDF, migration is really simple.Once the table meets the requirements, disable legacy CDF: https://preview.redd.it/0dddizd442oh1.png?width=710&format=png&auto=webp&s=fddc536d6aeca423b2e418f4856ae06843393749 submitted by /u/szymon_dybczak [link] [comments]
What is a Checkpoint in Structured Streaming?
What are you guys using for data ingestion in Databricks?
I've mostly been using Auto Loader for file-based ingestion in Databricks, especially when there are continuously arriving files. It's been working pretty well so far, but I'm curious what others are using in their projects. For example, are you mainly using: 1.Auto Loader 2.Copy INTO 3.Structured Streaming 4.Batch jobs 5.Some external ingestion tool One thing I'm trying to understand better us where the trade-offs are. For a large number of files, does Auto Loader still make the most sense, or are these cases where something like COPY INTO is simplet and more cost-effective? Also, how are you handling things like schema evolution, duplicate files, failed records, and reprocessing? I'm mainly interested in what people are actually using in production. If you've tried multiple approaches, which one ended up being the best balanceof performance, reliability and cost for you? submitted by /u/Delulu62134 [link] [comments]
Building for the AI Era: Lakebase, Streaming, and Lakehouse Innovations at VLDB 2026
Databricks is bringing Lakebase, Structured Streaming, and Lakehouse optimizations to VLDB 2026, spotlighting Lakebase as a third-generation cloud database that decouples transactional compute from storage to support agentic workflows. The company's Engineering and Recruiting teams will also be on-site at the conference.
why micro-batching matters so much in Databricks Auto Loader and Structured Streaming
Scaling Security Alert Triage With Specialized Agents on Databricks
Databricks AI now enables automated, real-time triage of high-volume, low-severity security alerts using 17 specialized agents on Spark Structured Streaming. This approach achieved a 10x higher true-positive rate and saved over 6,500 analyst hours in the first month by ensuring every low-severity alert is investigated.
Delta Lake 4.3.0
Delta 4.3.0 deepens Unity Catalog integration by making it the source of truth for managed table operations via the UC Delta REST API, introduces replaceOn/replaceUsing DataFrame APIs for selective row-level data replacement, and improves UniForm with atomic Iceberg conversion and incremental metadata updates. Delta Sharing gains streaming support, Change Data Feed capabilities, and Trigger.AvailableNow, plus performance improvements like better V2 checkpoint parallelization and variant column statistics for data skipping.
Building a Spark Streaming Real-Time Mode (RTM) Pipeline — Millisecond Streaming with Kafka
I recently built a fully working real-time transaction enrichment pipeline using PySpark RTM paired with Kafka, achieving end-to-end latency in the milliseconds. The article covers: \- Real-Time Mode (RTM) fundamentals \- Kafka integration with Spark Structured Streaming \- Millisecond-latency pipeline architecture \- Real-time transaction enrichment patterns Blog: https://blog.devgenius.io/building-a-spark-streaming-real-time-mode-rtm-pipeline-millisecond-streaming-with-kafka-dda74e9ef284
 Tutorials
Apache Spark Streaming Real-Time Mode - Latency Demo
The video demonstrates how to deploy and run Apache Spark Streaming in Real-Time Mode (RTM) using a declarative automation bundle. It shows that RTM significantly reduces P50 and P95 latencies compared to microbatch mode, achieving 26ms and 50ms respectively in a simplified setup without an external messaging bus.
 Tutorials
Air Traffic Control with Apache Spark Structured Streaming Real-Time Mode
The video demonstrates building a real-time air traffic control application using Apache Spark Structured Streaming Real-Time Mode, Lakehouse, and Databricks Apps. This system processes live flight telemetry, detects congestion, and generates alerts with sub-second end-to-end latency, all within a single Databricks platform.
 Tutorials
Unlock Your Use Cases: A Deep Dive on Structured Streaming’s New TransformWithState API
TransformWithState is Spark 4.0's new API for custom stateful streaming operations, supporting flexible state variables (value, list, map) and timers that replace the older flatMapGroupWithState methods. The presentation demonstrates implementing sensor data forward-fill to enable accurate windowed aggregations, plus features including checkpoint-based state initialization, TTL eviction, Avro schema evolution support, and real-time sub-200ms latency mode.
 News
Building Real-Time Sport Model Insights with Spark Structured Streaming
Spark Structured Streaming powers a real-time dashboard at DraftKings that streams simulation counter data from their sports betting model, letting traders instantly see how player rating changes affect odds predictions across all 300+ markets. This improved pricing speed by 30% and reduced errors by eliminating manual review of affected markets.
 News
A Comprehensive Guide to Streaming on the Data Intelligence Platform
Databricks provides two incremental processing engines: Structured Streaming for low-latency streaming operations and Enzyme for batch queries, which automatically optimizes SQL without manual complexity. New features include real-time mode for subsecond latency, Transform with State API for simplified state handling, and expanded materialized view support for complex SQL patterns.
 News
Crypto at Scale: Building a High-Performance Platform for Real-Time Blockchain Data
Elliptic and Databricks built a real-time platform processing blockchain data from 50+ cryptocurrencies (300+ terabytes) to power cryptocurrency compliance and risk detection. They migrated from a fragmented architecture to a unified Databricks stack using Delta Lake, Liquid Clustering, and dynamic file pruning to achieve scalable near-real-time analytics.
 News
Supercharging Sales Intelligence: Processing Billions of Events via Structured Streaming
Digisert built a Databricks pipeline processing 28 billion daily certificate events using medallion architecture with Spark Structured Streaming, demonstrating solutions for reliable multi-API ingestion with exponential backoff rate limiting, large-scale deduplication using partitioned merge operations, and batch size tuning to prevent resource exhaustion. The system enables real-time sales intelligence and compliance monitoring while minimizing costs through optimized data access patterns and zero reprocessing of ingested records.
 Tutorials
Real-Time Mode Technical Deep Dive: How We Built Sub-300 Millisecond Streaming Into Apache Spark™
Databricks introduces Real-Time Mode for Apache Spark, achieving sub-100 millisecond latency by replacing microbatch sequential processing with long-duration batches where stages run concurrently and data streams continuously without intermediate buffering. Users enable it by changing a single trigger parameter, delivering approximately 100x lower latency than existing Spark streaming modes, as demonstrated with an environmental monitoring pipeline reading from and writing to Kafka.
 News
Scaling Identity Graph Ingestion to 1M Events/Sec with Spark Streaming & Delta Lake
Adobe scaled identity graph ingestion to 1 million events per second using Spark Structured Streaming and Delta Lake, a 10x improvement over their previous architecture. Key techniques included microbatching with 80% deduplication of redundant writes, repartitioning to eliminate data skew, asynchronous execution for 2x faster latency, and in-memory metadata caching using Netflix Hollow.
 Community
PDF Document Ingestion Accelerator for GenAI Applications
Databricks released a solution accelerator that enables scalable batch ingestion and parsing of high-volume unstructured documents into structured formats for GenAI applications. The accelerator uses a pluggable parser framework supporting OCR, object detection, and AI parsing models, with intelligent bucketing that separates large files to optimize performance and prevent processing bottlenecks.
 News
Delivering Sub-Second Latency for Operational Workloads on Databricks
Databricks launched Real-Time Mode for Spark Structured Streaming to deliver millisecond-level latency for operational workloads using fixed-duration batches and concurrent stage execution. Customers achieved P99 latencies of 50-152 milliseconds for fraud detection, feature store updates, and device tracking—orders of magnitude lower than existing Spark streaming modes.
 Releases
Introducing Simplified State Tracking in Apache Spark™ Structured Streaming
Apache Spark Structured Streaming introduces simplified state tracking using the state reader API change feed to inspect historical state changes across batches. This feature helps developers debug and troubleshoot stateful streaming pipelines by identifying performance bottlenecks and inefficient state updates.
 Tutorials
Race to Real-Time: Low-Latency Streaming ETL With Next-Gen OLTP-DB
The video demonstrates building a low-latency streaming ETL solution using Databricks and Lakebase, achieving sub-two-second end-to-end latency for operational workloads. It teaches key performance optimization techniques, including controlling microbatch sizes, leveraging broadcast joins, enabling dynamic file pruning, and utilizing liquid clustering to minimize data movement and object storage costs.
 Tutorials
Pass PROFESSIONAL Databricks Certified Data Engineer Exam
The video outlines preparation strategies and essential study materials for passing the Databricks Certified Data Engineer Professional exam. It details specific technical topics covered on the test, including Delta Lake architecture, structured streaming best practices, change data feed, slowly changing dimensions, and access controls.
 News
The Future is Open: Data Streaming in an Omni-Cloud Reality
The video teaches how to build a multi-cloud data streaming architecture using open formats, Apache Spark, and Delta Live Tables to avoid expensive proprietary data extractions. It demonstrates two infrastructure-as-code methods for managing data pipelines across clouds using the dbx project and the Databricks Terraform provider.
 Releases
Nebula: The Journey of Scaling Instacart’s Data Pipelines with Apache Spark™ and Lakehouse
Instacart migrated its large-scale advertising and data pipelines from a traditional data warehouse to a Databricks lake house powered by Apache Spark and Delta Lake. The presenters demonstrate how this transition unified batch and streaming data processing, reduced storage and compute costs for over 40 petabytes of data, and improved developer productivity through Scala-based modular pipelines and local unit testing.
 News
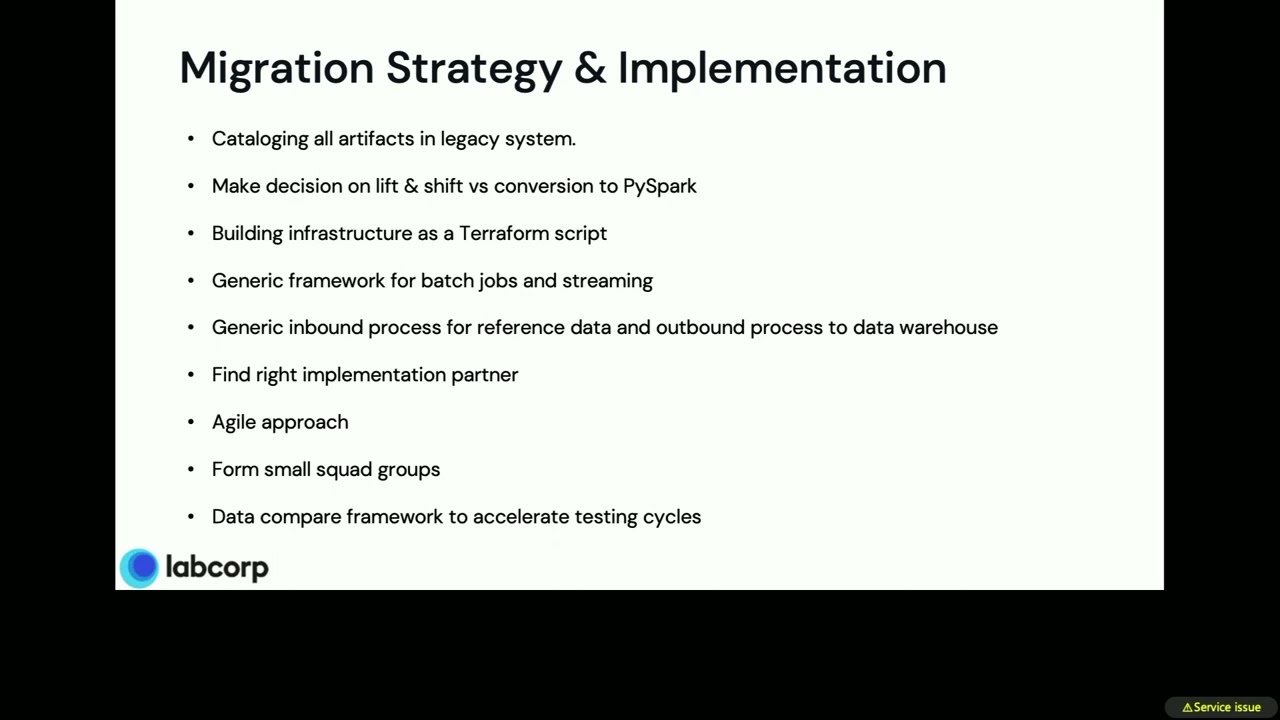
Labcorp Data Platform Journey: From Selection to Go-Live in Six Months
LabCorp migrated nearly one petabyte of enterprise data from Hadoop to Databricks within six months. The implementation utilized automated data comparison tools, Spark structured streaming, and Terraform-managed Unity Catalog governance.
 News
Making Travel More Accessible for Customers Bringing Mobility Devices
American Airlines built a real-time data streaming pipeline using Databricks and Spark Structured Streaming to process reservation messages and track mobility devices for passengers. This data is delivered via mobile apps and reports to airport managers, resulting in a significant reduction in damaged and delayed wheelchairs.
 News
Optimizing Batch and Streaming Aggregations
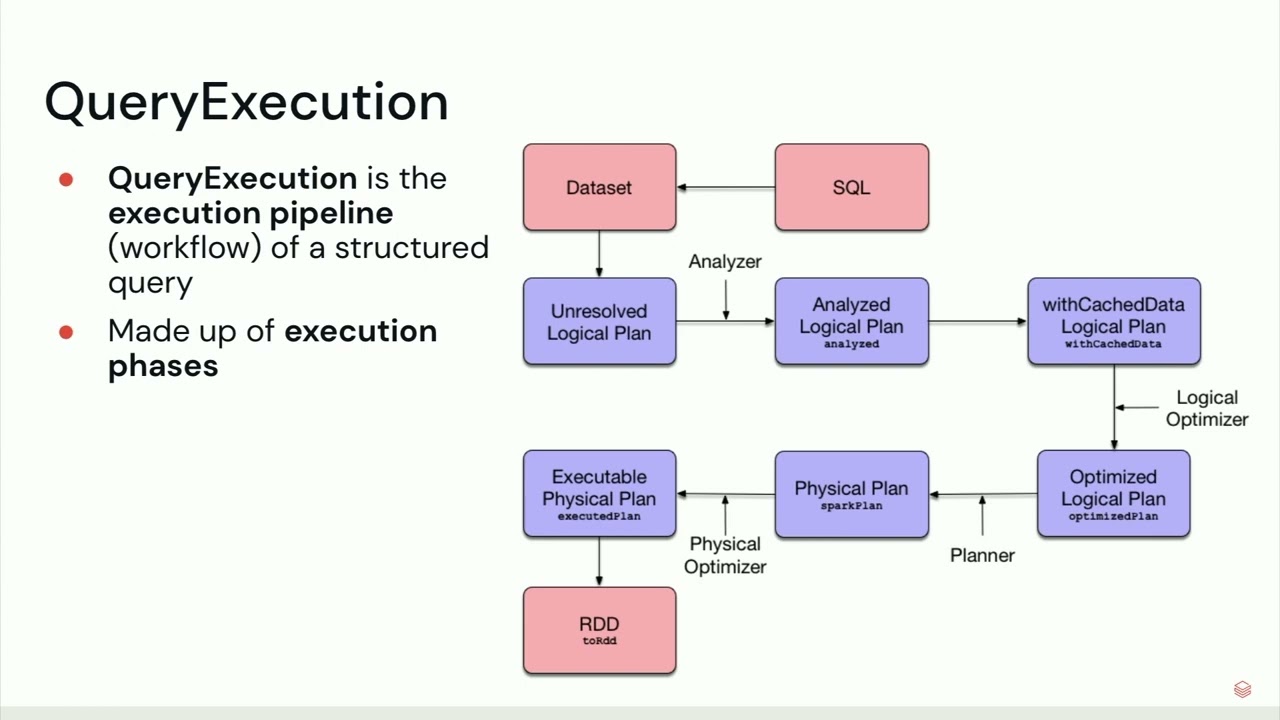
Apache Spark evaluates batch and structured streaming aggregations using three physical operators, where hash aggregate exec performs the fastest, object hash aggregate exec handles custom objects, and sort aggregate exec runs the slowest. Developers can optimize performance by expressing queries in SQL instead of custom code, using primitive data types for grouping keys, avoiding user-defined aggregate functions, and monitoring the number of sort fallback tasks metric.
 News
How Coinbase Built and Optimized SOON, a Streaming Ingestion Framework
Coinbase built SOON, a configuration-driven streaming ingestion framework using Spark Structured Streaming to unify table replication and Kafka ingestion into Delta Lake. The framework optimizes merge performance through techniques like min-max range filtering, k-means clustering, and change data feed synchronization for downstream systems like Snowflake.
 News
Event Driven Real-Time Supply Chain Ecosystem Powered by Lakehouse
The video details how the Australian Rail Track Corporation built an event-driven real-time supply chain ecosystem using the Databricks lake house platform. It demonstrates the technical architecture and use cases, such as automated weighbridge capture and predictive rail maintenance, to optimize network operations and safety.
 News
Disaster Recovery Strategies for Structured Streams
This video demonstrates how to implement disaster recovery for structured streaming pipelines on Databricks by balancing recovery time, recovery point objectives, and costs. It details using deep clones and offset tracking to execute failovers for both stateless and stateful streaming architectures.
 Tutorials
Streaming Data Analytics with Power BI and Databricks
The video demonstrates how to implement real-time streaming data analytics by combining Microsoft Power BI with Databricks lakehouse architectures. It details three specific scenarios using Delta live tables, structured streaming, direct query, composite models, and push APIs to build live reporting dashboards.
 Events
Embracing the Future of Data Engineering: The Serverless, Real-Time Lakehouse in Action
Databricks demonstrates a serverless real-time lakehouse architecture by streaming mobile phone sensor data into a cloud pipeline. The presentation features live ingestion through Kinesis, Delta Live Tables, Apache Spark structured streaming, and cross-cloud data sharing using Delta Sharing.
 News
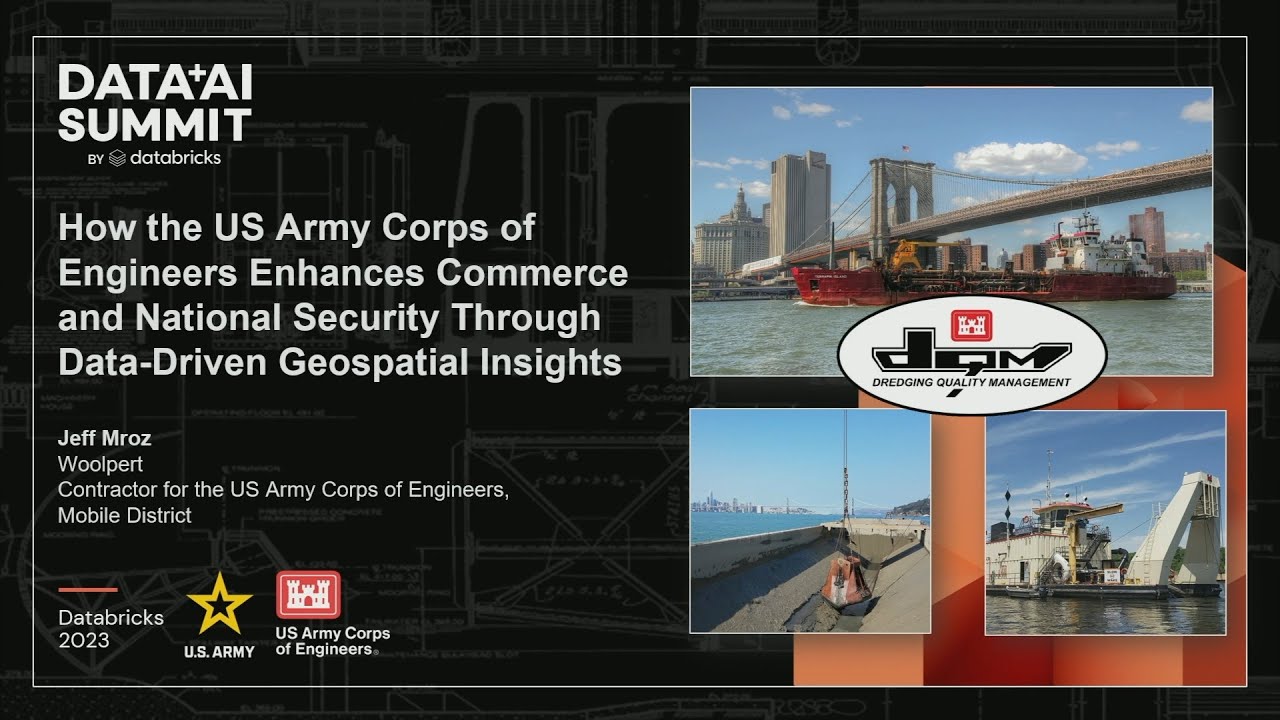
US Army Corp of Engineers Enhanced Commerce & National Sec Through Data-Driven Geospatial Insight
The video details how the U.S. Army Corps of Engineers modernizes its National Dredging Quality Management program by migrating from a legacy on-premises Oracle stack to a Databricks lake house architecture. It demonstrates how this cloud migration processes billions of streaming vessel telemetry points in under a minute to enhance real-time geospatial analytics, automation, and decision-making for national waterways.
 News
High Volume Intelligent Streaming with Sub-Minute SLA for Near Real-Time Data Replication
This video demonstrates a metadata-driven ETL framework built on Databricks that automates data ingestion, curation, and quality checks across both batch and streaming sources. It also explains an intelligent streaming optimization using dynamic thread pools to process Kafka change data capture events more cost-efficiently.
 News
How We Made a Unified Talent Solution Using Databricks Machine Learning, Fine-Tuned LLM & Dolly 2.0
Accenture built an AI-powered talent solution on Databricks using Delta Lake, MLflow, and over twenty-five machine learning models to assess workforce skills and labor market data. The platform incorporates a fine-tuned Dolly 2.0 language model integrated with LangChain to securely parse resumes and match candidates to roles.
 Community
Sponsored by: Avanade | Enabling Real-Time Analytics with Structured Streaming and Delta Live Tables
The video demonstrates how Delta Live Tables simplifies data pipeline creation by automating infrastructure management, data quality checks, and performance optimization through familiar Python and SQL APIs. It also highlights the integration of Delta Live Tables with Unity Catalog to provide unified data governance, physical and logical data isolation, and comprehensive end-to-end lineage tracking.
 News
Structured Streaming: Demystifying Arbitrary Stateful Operations
This video demonstrates how to implement arbitrary stateful operations in Spark Structured Streaming using flatMapGroupsWithState in Scala and applyInPandasWithState in Python. It breaks down the implementation into four core components: data structures, initialization logic, steady-state logic, and timeout logic.
 News
Top Mistakes to Avoid in Streaming Applications
This video teaches common mistakes and best practices in Spark streaming applications, covering data ingestion, stateful processing, and output writing. It demonstrates how to optimize performance and prevent failures using min partitions, rate limitations, RocksDB, and correct checkpoint management.
 News
Improving Apache Spark Application Processing Time by Configurations, Code Optimizations, etc.
Apache Spark application processing time can be improved by configuring custom data sources, optimizing code, and conducting garbage collection analysis. Partitioning strategies, such as assigning multiple files by the number of tasks or size of partitions, can also reduce read time.
 News
Realize the Promise of Streaming with the Databricks Lakehouse Platform
The video details how to use Structured Streaming and the Databricks Lakehouse platform to ingest and process streaming data. It also covers common streaming misconceptions, streaming patterns, and Upland's use of machine learning to handle streaming data.
 News
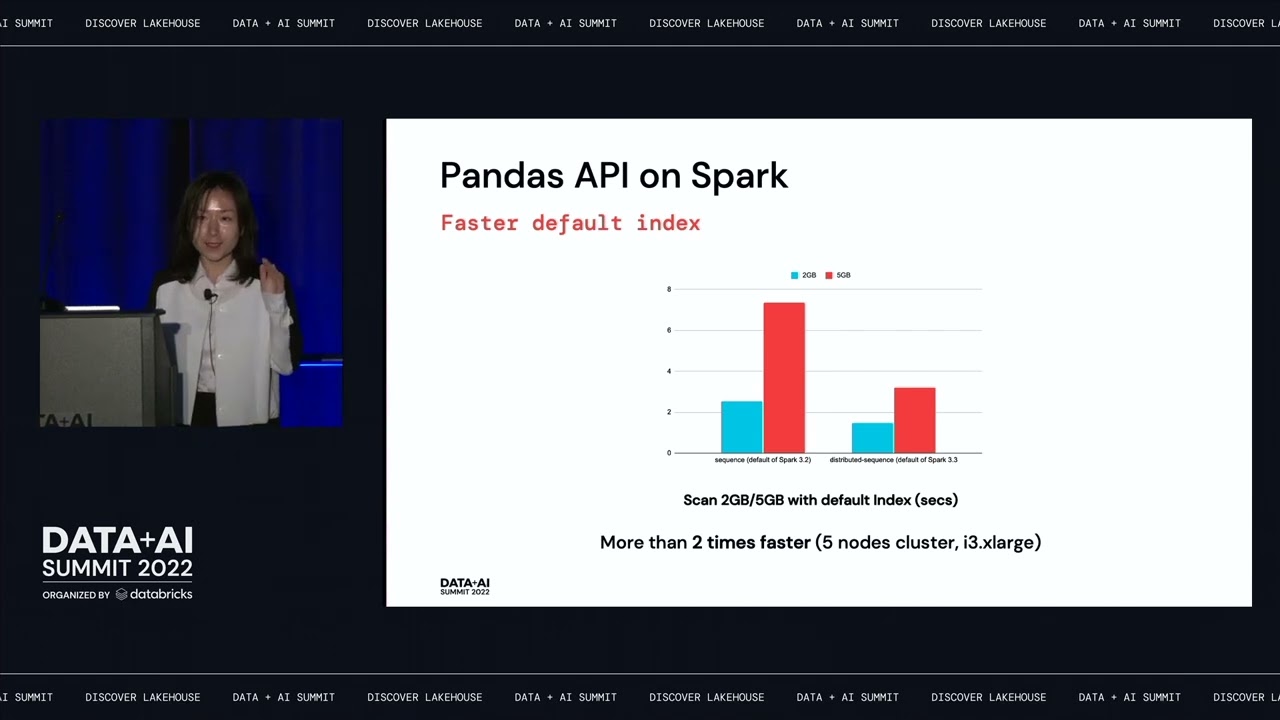
PySpark in Apache Spark 3.3 and Beyond
PySpark 3.3 introduces better pandas API support, datetime timedelta support, PyArrow batch interfaces, Python standard string formatters in SQL, inline type hints, and Python and pandas UDF profiling. Future versions of PySpark will add Spark Connect, native NumPy support, source-native indexes, optimized createDataFrame, and feature parity for structured streaming.
 News
Streaming Data into Delta Lake with Rust and Kafka
The video explains how Scribd reduced data ingestion costs by 95 percent by streaming data into Delta Lake using Rust and Kafka. It demonstrates the implementation details, performance metrics, and cost comparisons of using a Rust-based approach for appending data.
 News
Streaming ML Enrichment Framework Using Advanced Delta Table Features
The video demonstrates a streaming machine learning enrichment framework that processes millions of social media records daily using advanced Delta table features like change data feed and auto-optimize. It details how combining a rule resolver, dispatcher, and standardized Delta tables enables scalable, transparent, and efficient model application across multiple data and engineering teams.
 News
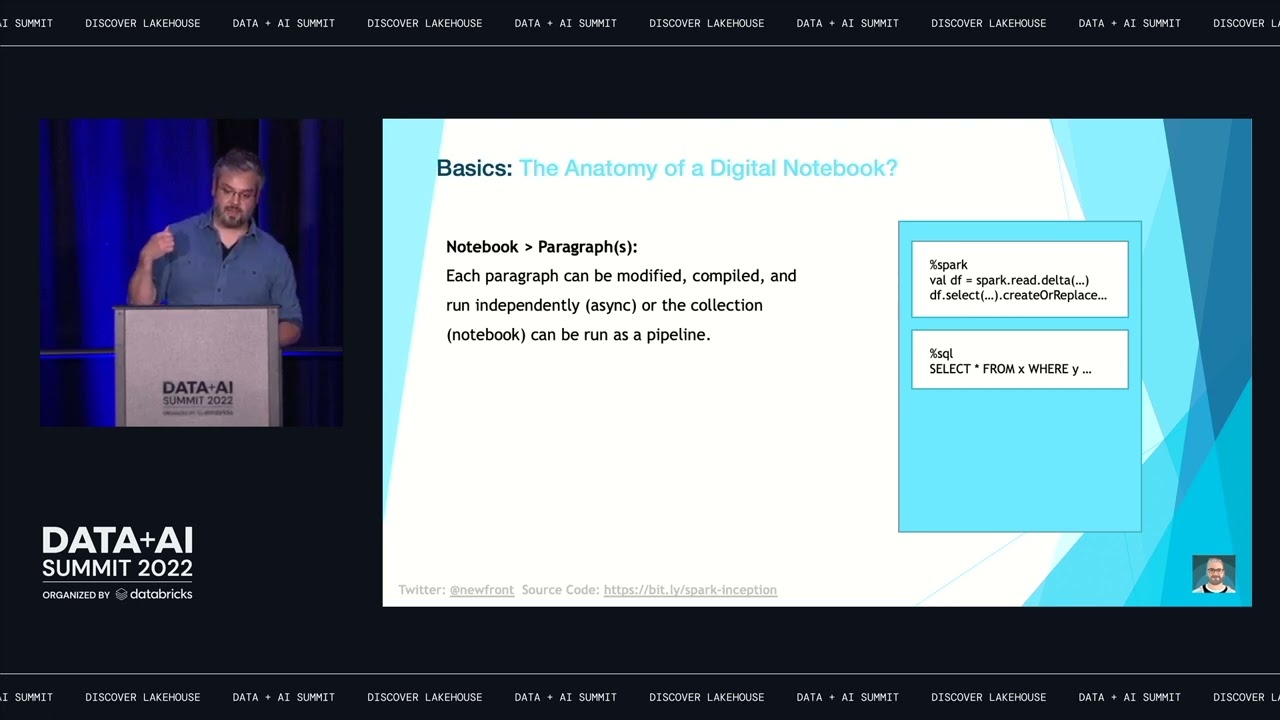
Spark Inception: Exploiting the Apache Spark REPL to Build Streaming Notebooks
The video demonstrates how to use the Spark REPL to construct a streaming notebook environment that executes remote procedure calls. It explains the architecture of the streaming notebook application, processing flow, and command processing for Spark Scala and Spark SQL.
 Events
Apache Spark Community Update | Reynold Xin Streaming Lakehouse | Karthik Ramasamy
Apache Spark and Structured Streaming have introduced new developer tools and features like Spark Connect and Project Lightspeed to improve latency, debugging, and ecosystem integrations. Demonstrations show how these technologies enable running data applications on edge devices and mobile platforms like iPads.
 News
Optimizing Incremental Ingestion in the Context of a Lakehouse
Incremental ingestion into a Lakehouse is built with Databricks Autoloader and Change Data Feed plus Spark Structured Streaming and Trigger Once, turning batch processes into a streaming setup without an always-on cluster. The setup avoids reloading large data volumes, and Autoloader schema inference, recovery mechanisms and file discovery modes get extra focus.