Kafka
Recent items mentioning Kafka across the Databricks ecosystem — releases, news, videos, and community Q&A. Updated hourly.
Plug & Play: Zerobus Ingest Now Supports Apache Kafka® Compatible APIs (Beta)
 News
Learn about Zerobus in 15 min!
Databricks Lakeflow Connect Zerobus Ingest is a high-performance, multi-cloud ingestion service that allows users to stream event data directly into their lakehouse without the cost and complexity of a traditional message bus. The video explains the architecture of Zerobus Ingest, announces upcoming API integrations for Kafka and MQTT, and demonstrates how to configure and run a Python client to write data directly into a Delta table.
 News
How an Open, Scalable and Secure Data Platform is Powering Quick Commerce Swiggy's AI
Swiggy uses a Databricks-based lakehouse platform with Delta Lake to manage billions of daily events across 700+ cities, supporting real-time delivery predictions and resource optimization at 10-minute delivery speeds. The platform enables AI democratization through data agents and chatbots that provide automated customer support and business intelligence without requiring SQL expertise.
 News
No More Fragile Pipelines: Kafka and Iceberg the Declarative Way
Kafka topics and Iceberg tables have incompatible data models that cause problems with schema evolution, consistency, and file fragmentation when building data pipelines. Confluent's Table Flow solution declaratively handles schema evolution, manages consistency through two-phase commits with segments, and performs automatic compaction to optimize query performance.
 News
Streaming Meets Governance: Building AI-Ready Tables With Confluent Tableflow and Unity Catalog
Confluent Tableflow automatically exposes Kafka streaming topics as Delta tables and syncs them to Databricks Unity Catalog, eliminating manual data pipeline work. A live demo shows how this enables immediate real-time analytics on stock market data streams without traditional ETL preprocessing steps.
 News
Sponsored by: Confluent | Turn SAP Data into AI-Powered Insights with Databricks
Confluent streams SAP operational data, enriches it with real-time context, and feeds it to Databricks for machine learning and analytics. The platform enables bidirectional data flow between operational and analytical systems, allowing AI agents to access both historical data and fresh signals while returning insights back to production applications.
 News
Creating a Custom PySpark Stream Reader with PySpark 4.0
The video demonstrates how to create a custom PySpark 4.0 streaming data source by implementing Python classes that inherit from the new data source interfaces. It walks through building a custom stream reader to ingest data from an unsupported messaging system like Apache Active MQ directly into Delta tables.
 News
Practical Pipelines: A Houseplant Alerting System with ksqlDB
This video demonstrates how to build a real-time houseplant monitoring system using Apache Kafka and a Raspberry Pi. It teaches how to use ksqlDB for stateful stream processing, configure Kafka topics, and integrate hardware sensors with external messaging alerts.
 News
Unlocking Near Real Time Data Replication with CDC, Apache Spark™ Streaming, and Delta Lake
DoorDash implemented an open-source near real-time data ingestion framework called Pepto using Apache Kafka, Apache Spark Streaming, and Delta Lake. The system captures change data feeds from various transactional databases and performs micro-batched upserts to achieve a P99 data latency of 7 to 30 minutes.
 News
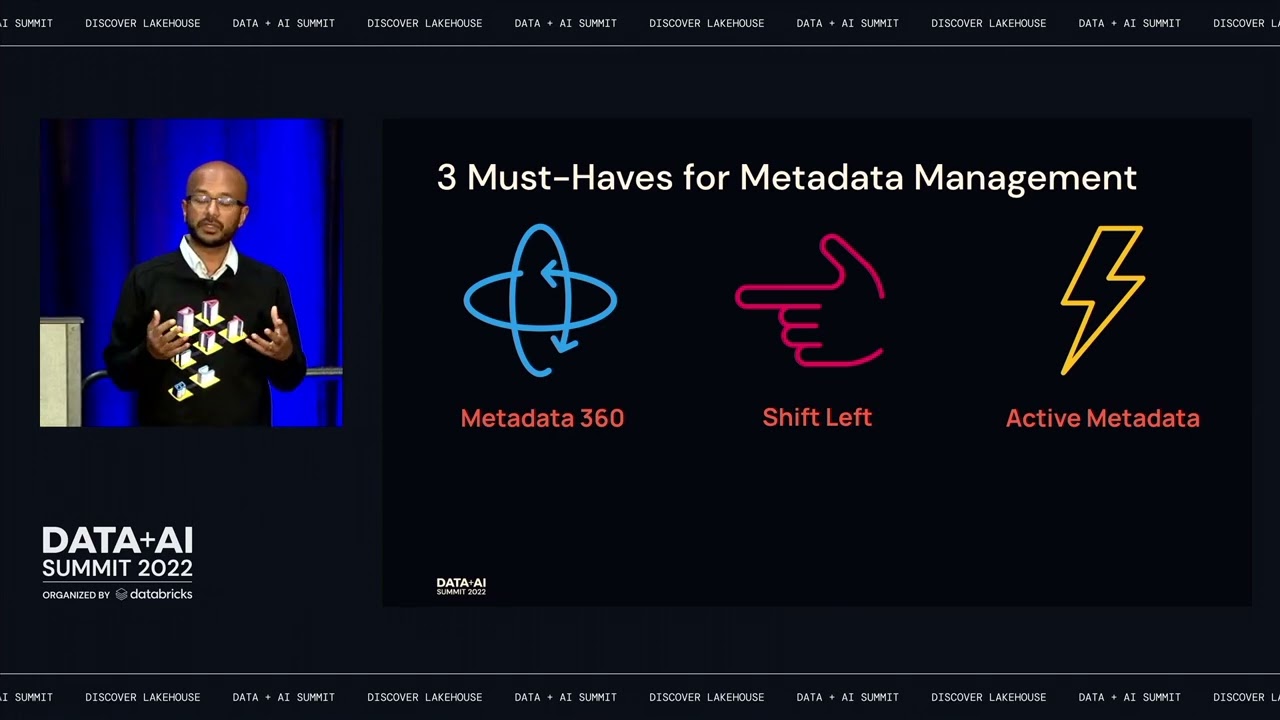
Connecting the Dots with DataHub: Lakehouse and Beyond
DataHub is an open source metadata platform that provides a unified graph of a company's data ecosystem, including datasets, dashboards, and pipelines. The video demonstrates how DataHub achieves comprehensive metadata management through full-stack integrations, shifting metadata practices to source developer workflows, and enabling active operational controls like circuit breakers.
 News
Near Real-Time Analytics with Event Streaming, Live Tables, and Delta Sharing
The presentation explores event-driven architecture, event streaming, change data capture, schema registries, and Delta Live Tables to achieve near-real-time analytics. It also highlights Delta Sharing as a secure method for sharing live data without duplication.
 News
Optimizing Speed and Scale of User-Facing Analytics Using Apache Kafka and Pinot
Apache Pinot and Kafka can be combined to build real-time user-facing analytics systems with low latency and high concurrency. The presentation details Pinot's architecture and optimization techniques like indexing, star-tree indexes, upserts, and multi-stage query execution.
 News
Backfill Streaming Data Pipelines in Kappa Architecture
Streaming data pipelines in Kappa architecture can be backfilled efficiently by leveraging a data lake for storage, using event-time semantics, and coordinating watermarks across multiple sources. This approach scales horizontally and costs significantly less than retaining messages in queue storage.
 News
Serverless Kafka and Apache Spark in a Multi-Cloud Data Lakehouse Architecture
The video discusses serverless Kafka and Spark in a multi-cloud data lakehouse architecture. It covers data analytics at rest, data streaming in motion, and a lakehouse architecture example with intelligent connected cars.
 News
Streaming Data into Delta Lake with Rust and Kafka
The video explains how Scribd reduced data ingestion costs by 95 percent by streaming data into Delta Lake using Rust and Kafka. It demonstrates the implementation details, performance metrics, and cost comparisons of using a Rust-based approach for appending data.
 Tutorials
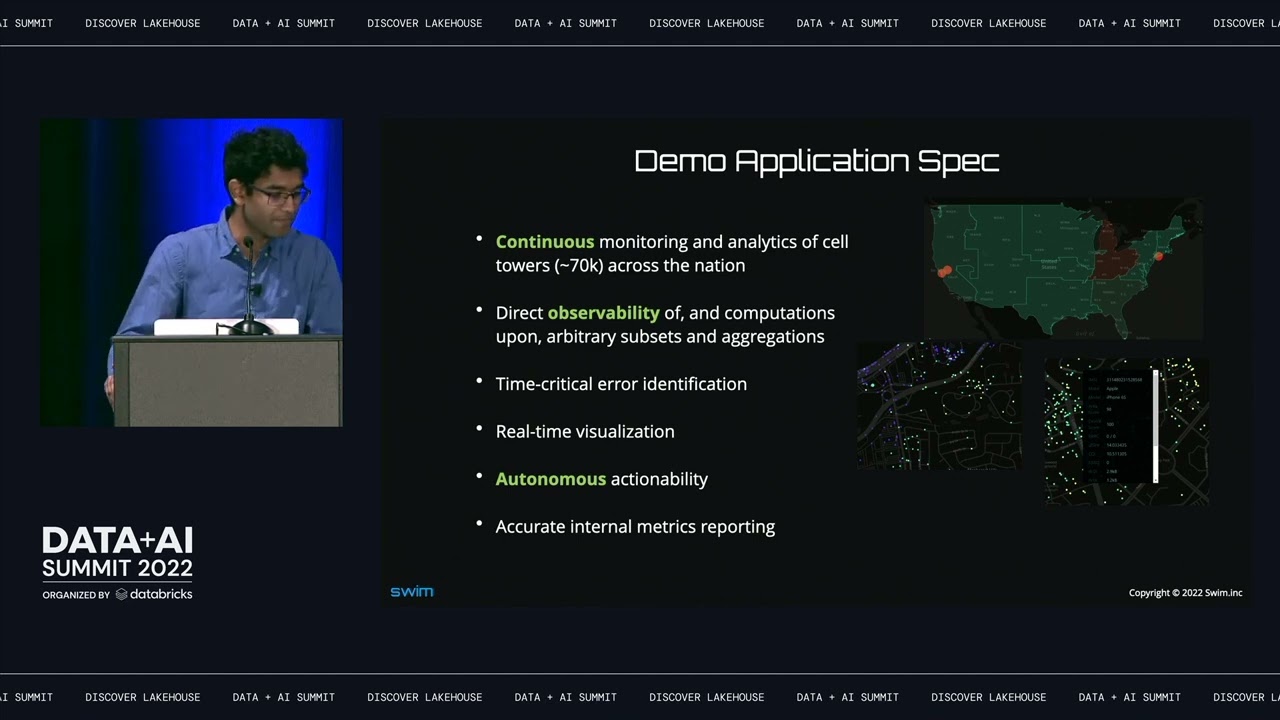
Automating Business Decisions Using Event Streams
Rohit Bose shows how an end-to-end streaming architecture delivers continuous, autonomous and observable real-time solutions, building an industry-specific application that continuously reports insights over dynamically scoped streams. The demo uses the Swim platform to expose thousands of streaming APIs seeded by an Apache Kafka firehose, feeding real-time map visualizations and decision-making clients.
 News
How Adobe uses Structured Streaming at Scale
Adobe shares Structured Streaming lessons from its Unified Profile System, which ingests TBs of data a day and is PBs large. Topics include monitoring Kafka consumer lag, backpressure, minPartitions and maxOffsetsPerTrigger tuning, micro-batching practices, windowing, the RocksDB state store, broadcast joins, custom aggregators and off-heap counters in Redis.
 News
Evolution is Continuous, and so are Big Data and Streaming Pipelines
Scania processes GPS data from around 400,000 connected trucks and buses with a continuously delivered Spark Streaming pipeline, stateful and stateless, that pushes data products to Apache Kafka. Lessons from each pipeline generation, the Jenkins, Artifactory and Ansible build chain, and delivering quality-assured data products at scale are covered.
 News
How Adobe Does 2 Million Records Per Second Using Apache Spark!
Adobe shares Apache Spark lessons from its Unified Profile System, the heart of Experience Platform, which ingests terabytes a day and holds petabytes. Topics include caching physical plans for repeated queries, understanding joins and shuffle, monitoring Kafka consumer lag and backpressure in Structured Streaming, handling skew, sampling, and pairing pipelining with Redis.
 News
Automating Federal Aviation Administration's System Wide Info Management Data Ingestion and Analysis
USDOT-BTS automates infrastructure, configuration, ingestion and analysis of FAA SWIM data sets (STDDS, TFMS and TBFM) delivered through the SWIM Cloud Distribution Service over Solace JMS. The solution uses Azure Databricks, Apache Kafka and Spark-XML with infrastructure as code, deriving insights such as flight counts, delayed flights and affected passengers.