Delta Sharing
Recent items mentioning Delta Sharing across the Databricks ecosystem — releases, news, videos, and community Q&A. Updated hourly.
Procore replaced a once-a-day API refresh with hourly OpenSharing delivery on Databricks, serving hundreds of curated tables across hundreds of thousands of per-customer data shares 1. CARIAD 7 and the SAP–Databricks partnership 9 show the same pattern, with SAP data products shared directly into Databricks via Delta Sharing. Tooling is keeping pace: the Python and Java SDKs both added replication configuration for Delta Sharing in their October 15 releases 56.
Generated daily from the 10 most recent items mentioning Delta Sharing. Click any [N] to jump to the source.
How Procore is powering construction analytics with OpenSharing
Procore moved its construction analytics product from an API-driven, once-a-day refresh to OpenSharing on Databricks, so customers can now pull data into their downstream systems and business processes hourly. OpenSharing distributes hundreds of curated tables with partitioned per-customer access across hundreds of thousands of data shares, doubling data availability for end customers and internal product teams.
 Tutorials
Tutorial: Genie for Data Engineers, Data Scientists, and Everybody Else
This tutorial demonstrates how to use Databricks Genie to build a live web app and data pipeline from a 700-million-row IoT dataset. The process covers getting the data from the Databricks Marketplace, running exploratory data analysis, building pipelines and jobs with Genie Code, querying data on mobile, and receiving shared data locally.
How do you manage, in a Databricks Asset Bundles-based CI/CD, the permissions and access resources that a bundle cannot declare?
We have a DABs-based CI/CD in a monorepo and want to split it: deploy the DABs from the data-code repo and keep the Terraform infrastructure in a separate repo. The original idea was that Terraform would change at a different pace and its deployments would be manual, with no automated dependency on DABs deploys. However, at work they’re now saying this infrastructure part should be tied to the DABs deployment and not be manual, and I’m unsure where it should live and how to automate it. We mainly run into four cases: Cross-boundary grants: our pipeline needs to read a table owned by another team, so we need to grant SELECT on that table/schema to our service principal. Postgres grants: a job needs to connect to a Lakebase database and requires a GRANT on a Postgres schema, table, or role. Share contents: we need to add or remove tables and views from a Delta Sharing share consumed by an external consumer. Notification destinations: a job or pipeline needs to send alerts to a notification destination (email, Slack, webhook) that the bundle cannot declare. Today, all of these live in Terraform outside the bundle, so every time the data code needs one of these changes, we have to coordinate a separate MR and deployment in addition to the bundle deploy. Where do you put these in your pipeline: inside the bundle, in a separate Terraform stack applied after the bundle deploy, in the platform repo, or another way? What issues have you run into with each approach? Tx so much submitted by /u/Appropriate_Tip_9580 [link] [comments]
Cross-subscription/workspace data access pattern for PII data in Azure Databricks?
We are setting up Azure Databricks for a client with two fully isolated workspaces ( Dev and Prod ). They have completely separate: Workspace IDs Azure Resource Groups Azure Subscriptions The Problem: PII data from a source system is currently landing in an Azure storage location that only the Prod workspace has access to. Because of this, we can read the data in Prod , but not in Dev . We now need to grant a specific group of analysts read-only access to this source PII data directly from the Dev workspace. Questions: What is the standard/cleanest pattern to achieve this? 1) Cross-subscription Azure Managed Identity / Storage Credential grants? 2) Unity Catalog cross-workspace binding / Delta Sharing? Any advice, reference architecture, or lessons learned would be greatly appreciated! submitted by /u/Miserable-Neat4246 [link] [comments]
This release adds support for real-time SQL warehouses, issue management methods for experiments, and replication configuration for Delta Sharing. It also introduces a breaking change by removing the effectiveServerlessComputeId field from job run tasks.
The SDK adds issue tracking methods for ML experiments, a realtime warehouse type for SQL endpoints, and replication configuration support for Delta Sharing. As a breaking change, the effective_serverless_compute_id field was removed from job run tasks.
CUSTOMER STORY | CARIAD unifies global automotive data with OpenSharing and Unity Catalog
Is Delta Sharing the end of external ETL? My notes on Open vs D2D.
Just spent some time digging into the Unity Catalog and Delta Sharing documentation. Here’s the TL;DR on the two patterns for anyone looking to implement this: Open Sharing (The "Universal" Path): Audience: Recipients without Databricks (using Power BI, Pandas, Tableau). Mechanism: Presigned URLs + Bearer Tokens. Constraint: Tabular data only (tables/views). Security: Can be restricted via IP filtering. D2D (The "Native" Path): Audience: Both parties are on Unity Catalog-enabled Databricks. Assets: Tables, Views, Volumes, Notebooks, and Models. Pros: No token management; Zero egress costs if in the same region. Performance: DBR 16.2+ uses scoped credentials, making it basically as fast as a local table read. Observations: The "Zero-Copy" aspect is the real winner here. The audit trail in system tables alone covers about 95% of standard compliance needs (GDPR/SOC). The Coastal Community Bank case study (2 months to 2 days for onboarding) seems to be the gold standard for ROI here. Discussion: Is anyone actually using the Open Sharing side with external vendors in production? How are you handling the token rotation/security for non-Databricks clients? Or are you finding that most of your partners are already on the Databricks ecosystem? submitted by /u/SalamanderOpen859 [link] [comments]
 News
Databricks and SAP: Building the Next Generation of Enterprise Data and Analytics
The Databricks and SAP partnership enables enterprises to securely share SAP data products directly into Databricks using delta sharing and native tools like Business Data Cloud. The video demonstrates a supply chain use case where Databricks agents use this integrated SAP data to automate predictive maintenance workflows and procurement actions.
Delta Lake 4.4.1
Delta Lake 4.4.1 adds safeguards for catalog-managed tables by blocking unsupported cleanups and skipping automatic maintenance so writes can succeed reliably. It also fixes snapshot construction errors caused by unratified staged commits, allowing safe re-enablement of S3A fast listing.
Time to Swap the Cookies for Jetfuel - New Dataset & New Databricks Genie Tutorial
Most of you know samples.bakehouse . Great for a first query. Perfect for a quick demo. But after years of cookie sales, it's a little overbaked. Time to swap the cookies for jet fuel. ✈️ Together with the OpenSky Network , I brought a full day of global air traffic to Databricks Marketplace: 696 million real ADS-B position reports, messy just like real life. Myself, I used Genie for the whole journey: EDA, data exploration, a Apache Spark Declarative Pipeline, and a Lakeflow Job. Then I went a step further and read the same Marketplace data with open-source tools only, using OpenSharing and pandas. The result is this hands-on tutorial: Marketplace + Unity Catalog: get the data as a governed table Genie Agents: find anomalies in plain English Genie Agents: explore and visualize with maps and charts Genie Code: a Spark Declarative Pipeline, bronze to gold, with data quality rules Genie Code: a Lakeflow Job with schedule, retries, and email alerts Databricks Apps: your coding agent, governed by Unity Catalog OpenSharing: the open-source client in VS Code with pandas Everything runs on Databricks Free Edition (free, no credit card). 📖 Tutorial: Databricks Genie for Data Engineers and Data Scientists 💻 GitHub: databricks/tmm/DSDE-Genie-Tutorial 🛫 Dataset: OpenSky Network full-day dataset on Marketplace What's the first thing you'd query in a day of global air traffic? P.S. For the record, we still love bakehouse! 🍪❤️ [Disclaimer: I'm one of the two people who baked it.] submitted by /u/CompetitiveBet8978 [link] [comments]
Multi-region model serving on Databricks with OpenSharing
Scaling Delta Sharing across Non-Databricks Recipients: Handling Credential Rotation and Lifecycle
Using Delta Sharing to hold ISV entitlement data outside the customer's metastore — reasonable fit?
Automatic change data feed is now generally available!
With automatic CDF, Databricks computes row-level changes at read time using row tracking, rather than materializing those changes during every write. Use change data feed on Databricks | Databricks on AWS Why does that mattre? - Better write performance for MERGE INTO and UPDATE workloads - No need to enable CDF individually on every eligible table - Lower storage overhead compared with legacy CDF - The same familiar APIs still work: table_changes() and readChangeFeed - Works with batch processing, Structured Streaming, and Databricks-to-Databricks Delta Sharing For Delta Lake, the main requirements include: • Databricks Runtime 19 LTS+ • A managed table or external table in Delta Lake format with row tracking enabled And if you’re already using legacy CDF, migration is really simple.Once the table meets the requirements, disable legacy CDF: https://preview.redd.it/0dddizd442oh1.png?width=710&format=png&auto=webp&s=fddc536d6aeca423b2e418f4856ae06843393749 submitted by /u/szymon_dybczak [link] [comments]
How to do cross-cloud sharing with OpenSharing with added security (demo)
Hey folks! In this demo, Akram from Databricks' product team shares how you can leverage SecureConnect to better your security posture when doing cross-cloud sharing on OpenSharing! If you have no idea what OpenSharing is, how it applies to you, or how we got from Delta Sharing to OpenSharing, also encourage you to watch this video: https://youtu.be/0mfuNybtmdE Hope you find this helpful! submitted by /u/JosueBogran [link] [comments]
Databricks and OpenSharing questions
This my first time looking into use OpenSharing to share data externally and would to get some idea on if I am on the right path. My current idea is as follow: ETL my datasets using CDF from source to a catalog_curated, multiple tables In a catalog_shared, create views for each that apply filters (rows or joins) and these are what will be published and shared with external. I understand when sharing a view via OpenSharing, pushdown will not work and the whole views will get materialized temporarily when query, which I know may be an issue when external uses one of our watermark column. However, our dataset is not that big and access to the data is not going to be frequent, sharing a persisted version of the views will solve that, but is the added complexity worth it? I also could add the filters as part of the ETL config, but I am thinking it might be too complex for my current need. And when we need to expand the filters, all we have to do is change the views. I think the goal for me right now is simplicity and maintainability over complex ETL work, unless there is a reason to do so. As stated, this is my first time working with OpenSharing/DeltaSharing. Any comments, suggestions, or best practices are greatly appreciated. Thanks submitted by /u/Hungry-Tax6101 [link] [comments]
Who pays cross-cloud egress for Delta Sharing from GCP to Azure?
Databricks OpenSharing: How Global Distribution Reduces Egress Costs & Improves Performance (Demo with Databricks Product Lead)
If you are a data provider on Databricks, OpenSharing (formerly Delta Sharing) is a fantastic tool for distributing data to your customers. During my time at a former job, there was nothing better than to work with customers that were able to consume data from Delta Sharing. On at least two occasions though, we received unpleasant surprises: egress fees from our cloud providers. Those egress fees were most often times avoidable. For example, we would make sure that our customers and our company agreed on the cloud/region combination we would serve from/to, allowing us to build one-off pipelines, etc. But, that required manual work, created staleness issues, etc. While in our situation, we could sometimes overcome the same cloud vendor but different region situation, distributing to a region we just didn't have anything setup for OR a completely different cloud was a no-go. All that to say, Global Distribution aims to solve this and more. No need to have an account with another cloud vendor to serve cross-cloud. No need to have have data distributed to multiple regions within your AWS/Azure/GCP. No need to build/maintain pipelines. Just use Global Distribution. Check out the video and see Akram Chetibi who leads OpenSharing explain/demo it, and love to hear your thoughts. submitted by /u/JosueBogran [link] [comments]
Got error using Opensharing Get Table API to foreign iceberg table
Databricks OpenSharing Explained: Delta Sharing for the AI Era (w/ Databricks Product Leader)
Hey everyone! In this video, a Databricks product leader joins me to explain what OpenSharing, and what happened to Delta Sharing! Delta Sharing is one of the features I used often at a previous role to provide data to multiple customers, so it will be interesting to see how the journey with the expanded focus (data + AI sharing) goes. submitted by /u/JosueBogran [link] [comments]
Delta Lake 4.4.0
Delta Lake 4.4.0 supports Apache Spark 4.2 and adds identity columns and generated-column support in SQL DDL. The release expands UC Delta API integration to Delta Kernel and the experimental Flink connector for catalog-managed tables, introduces Flink upsert mode with merge-on-read updates, and improves VOID-column and partition handling.
Delta Lake 3.3.3
Delta 3.3.3 fixes transaction log retention bugs that broke time travel and CDF reads, and a Delta Sharing deletion vector cache bug causing long-running queries to fail. It adds opt-in RANDOMIZE_FILE_PREFIXES to spread S3 object keys for high-throughput workloads and upgrades Delta Sharing client for improved OAuth and retry handling.
Bringing real-time fraud prevention to government benefits
Databricks is helping federal agencies move fraud detection for benefit programs from after-the-fact reviews to real time, building on techniques honed with banks, credit card companies, and insurers. With over 80% of federal executive departments already on the platform, tools like OpenSharing and Clean Rooms let agencies share fraud signals across silos without exposing raw data, surfacing schemes no single agency could catch alone.
Workspace ID validation for unified-provider resources shifted from plan time to apply time, reducing unnecessary API calls and eliminating false positives for restricted credentials and dynamic workspace IDs. The release adds a databricks_recipients data source for Delta Sharing, trace_location support for MLflow experiment traces in Unity Catalog, and fixes for VIEW column comment updates and access control rule set drift detection.
Delta Lake 4.3.1
Delta Lake 4.3.1 fixes OAuth authentication failures in the Delta REST Catalog caused by incorrect key lowercasing and enables S3A fast listing when using OSS UnityCatalog's CredScopedFileSystem wrapper. It also prevents the reserved is_managed_location property from persisting into managed table metadata.
 Events
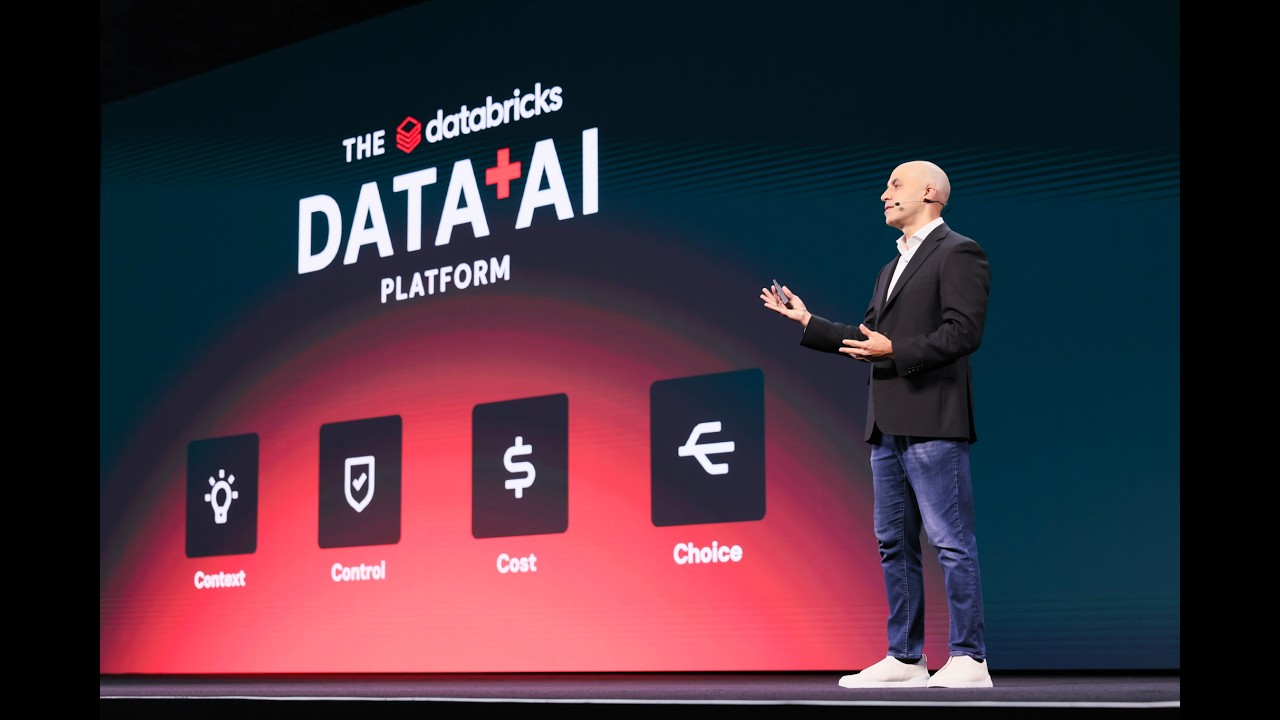
What it takes to scale agents in the enterprise: context, control and choice
Databricks CEO Ali Ghodsi outlines enterprise AI scaling strategies centered on organizational context, open choice, security control, and cost management. The session demonstrates developer tools like Agent Bricks, the Omnigent open source project, and Genie code alongside enterprise partnerships.
 Events
Ali Ghodsi, Co-founder and CEO, Databricks kicks off Data + AI Summit 2026
Ali Ghodsi kicked off the Data + AI Summit 2026 by announcing new Databricks features and architectural layers focused on open data formats, unified governance, cost controls, and enterprise context. He also detailed platform updates including Genie ontology and agents, LakeBase Postgres, Unity AI Gateway, and the acquisition of security platform Panther Labs.
Announcement | OpenSharing, Marketplace Apps, and SecureConnect for the AI Era
Delta Lake 4.3.0
Delta 4.3.0 deepens Unity Catalog integration by making it the source of truth for managed table operations via the UC Delta REST API, introduces replaceOn/replaceUsing DataFrame APIs for selective row-level data replacement, and improves UniForm with atomic Iceberg conversion and incremental metadata updates. Delta Sharing gains streaming support, Change Data Feed capabilities, and Trigger.AvailableNow, plus performance improvements like better V2 checkpoint parallelization and variant column statistics for data skipping.
 Events
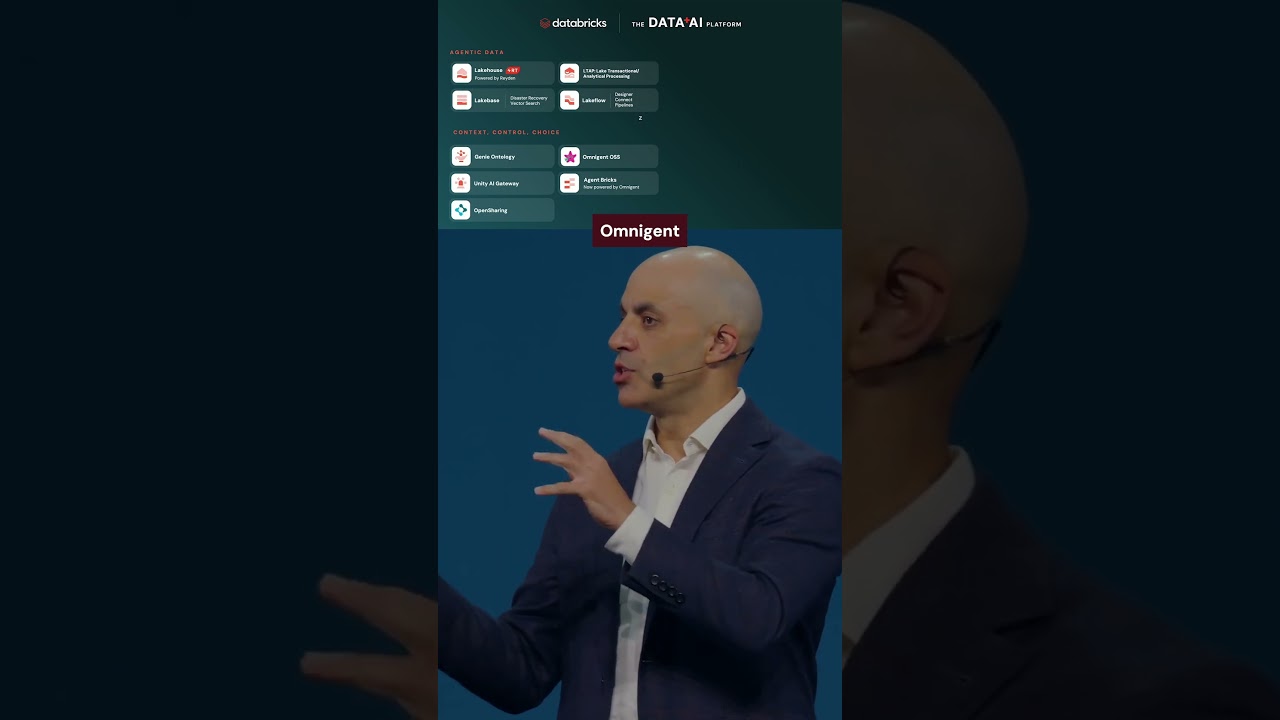
Recap of product announcements from Data + AI Summit 2026 | Day 1
Databricks announced several new products and features at the Data + AI Summit 2026, Day 1, including the Genetic Data Foundation, Lakehouse RT, Lake Base with disaster recovery, Lake Flow, Genie Ontology, Unity AI Gateway, Omnigent, and various Genie agents (Genie 1, Genie Code, Genie Agents). They also introduced new applications like Lake Watch for SIM and Customer Lake for CP.
Becoming the most comprehensive data & AI ecosystem on earth
Databricks is expanding its Data and AI partner ecosystem with new Marketplace, Apps, OpenSharing, and Genie Agent capabilities for building, distributing, sharing, and monetizing solutions. These updates accelerate deal velocity, provide access to 20,000+ Databricks customers, and unlock new AI-era business models like pay-per-question.
Introducing OpenSharing: the Next Evolution of Delta Sharing for the Agentic Era
Databricks has introduced OpenSharing, a Linux Foundation-hosted evolution of Delta Sharing that expands zero-copy sharing beyond tabular data to models, agents, and semantic context across Delta Lake, Apache Iceberg, and Parquet. The enterprise implementation on Databricks enables governed sharing of Genie Agents via Unity Catalog, automated private networking with SecureConnect, and low-latency multi-cloud access via Global Distribution.
Introducing OpenSharing SecureConnect
OpenSharing SecureConnect introduces a Databricks-managed proxy for storage access, eliminating the need for data providers to configure network for each recipient. Providers can optionally leverage NCC for private link connectivity between the proxy and their storage.
Sciene AI Companion: building an autonomous Customer Success platform on Databricks
Sciene built an autonomous Customer Success platform on Databricks, enabling AI-powered CSMs to standardize and scale work with context-aware emails, meeting decks, and account diagnostics. This end-to-end Databricks solution, leveraging Delta Sharing, Lakebase, and SQL Warehouses, significantly improved productivity and saved up to 6x time on key workflows.
Databricks Hands Delta Sharing to the Linux Foundation and Levels It Up
Geospatial Unbounded: Spatial SQL GA with AI/BI Maps, Delta Sharing, and Iceberg v3
Spatial SQL is now Generally Available on Databricks, bringing native geospatial data types, 90+ ST_* functions, and AI/BI Dashboards that render maps natively. This release also includes major performance improvements, open lakehouse support via Delta Sharing and Iceberg v3, and Apache Spark 4.2 compatibility for geo columns.
Announcing the Databricks storage ecosystem: Governing the enterprise data estate, wherever it lives
The Databricks Storage Ecosystem now natively connects hybrid and on-premises storage platforms to Databricks via OpenSharing, enabling centralized data governance and GenAI scaling across your entire hybrid infrastructure. Run Databricks Serverless Compute, Genie, and LLMs directly on your on-premises datasets with a zero-copy architecture, instantly turning isolated data into active, AI-ready assets.
Got error when access delta sharing table with iceberg endpoint
Unlocking SAP Business Context in Databricks with Semantic Metadata Delta Sharing
SAP Business Data Cloud now automatically syncs semantic metadata, including descriptions and key relationships, into Unity Catalog, making SAP data instantly AI-ready and more discoverable. SAP PersonalData governance tags are also automatically available in Unity Catalog, enabling fine-grained access controls with ABAC.
Stripe data now available on Databricks via Databricks Marketplace
Stripe data is now available on Databricks Marketplace, enabling you to activate a Stripe data pipeline with Delta Sharing in minutes and instantly power AI applications. Share Stripe payment and business data directly into Unity Catalog to create a single source of truth and query live payment data for models, agents, and Genie workspaces.
Delta Lake 4.2.0
Delta 4.2.0 enables atomic REPLACE TABLE, RTAS, and DPO for catalog-managed tables, enhances streaming capabilities, and adds a Kernel-based Flink connector. The release makes Variant generally available, adds geospatial and collation support, and includes comprehensive security hardening.
Delta Lake 4.1.0
Delta Lake 4.1.0 supports Apache Spark 4.1.0 and introduces conflict-free enablement of Deletion Vectors and Column Mapping on existing tables without blocking concurrent writes. The release requires Java 17 and Spark 4.0.1 or higher (dropping Spark 3.5), adds full catalog-managed table support in Delta Kernel for Unity Catalog integration, and fixes MERGE/INSERT struct expansion bugs.
SQL warehouses now support "5X-Large" cluster sizes and a higher maximum of 40 clusters. This release also fixes permanent drift for external model credentials in databricks_model_serving and improves dashboard file content change detection.
 Tutorials
De-Risking Investment Decisions: QCG's Smarter Deal Evaluation Process Leveraging Databricks
Quantum Capital Group utilizes the Databricks intelligence platform and Delta Sharing to clean, validate, and enrich energy sector data for improved private equity investment decisions. Partnering with Tiger Analytics, the firm migrated its data infrastructure to Unity Catalog to scale deal flow, automate economic modeling workflows, and provide secure data access across portfolio companies.
 News
Maximize Retail Data Insights in Genie with DeltaSharing via Crisp’s Collaborative Commerce Platform
The video demonstrates how to ingest and normalize retail data using Crisp and share it into Databricks via Delta Sharing. It then shows how to use Databricks AI blueprints and Genie to analyze this data through natural language queries and custom applications.
 News
From Code to Insights: Leveraging Advanced Infrastructure and AI Capabilities
Insulet migrated its data infrastructure from Azure to Databricks, implementing a data mesh architecture with medallion layers, Unity Catalog governance, and Delta Sharing for partner data access. The company achieved real-time analytics, GXP-compliant deployments, and FinOps cost optimization, demonstrating how to balance innovation with operational efficiency.
Delta Lake 4.0.0
Delta Lake 4.0.0 introduces Delta Connect for Spark Connect connectivity, catalog-managed tables in preview for catalog-controlled commits, full Variant data type support for semi-structured storage, and graduates Type Widening to enable column type changes without rewriting data. The release requires Apache Spark 4.0 and discontinues active development of Delta Standalone and related connectors (Flink, Hive) in 4.x, shifting them to maintenance-only mode.
Delta Lake 3.3.1
Delta Lake 3.3.1 includes a fix allowing user-specified schemas on read when consistent with table schema and documentation updates for Row Tracking Backfill. Delta Kernel 3.3.1 fixes handling of non-uniform value types in map fields within delta commit files.
Delta Lake 3.3.0
Delta Lake 3.3.0 adds Identity Columns for automatic unique keys, VACUUM LITE for faster transaction log-based cleanup, and enables Row Tracking backfill on existing tables for row-level lineage tracking. UniForm Iceberg can now be enabled on existing Delta tables without data rewriting, and Type Widening is now supported in Delta Kernel for reading type-evolved tables.
Delta Lake 3.2.1
Delta Lake 3.2.1 adds RESTORE support for clustered tables and enables Uniform Iceberg on existing tables via ALTER TABLE, eliminating costly data rewrites. Key fixes include string comparison with Unicode surrogate pairs, decimal and timestamp encoding in Parquet, and S3DynamoDB VACUUM throttling issues.
 Releases
Announcing Databricks Clean Rooms with Live Demo. Presented by Matei Zaharia and Darshana Sivakumar
Databricks Clean Rooms enables two parties to securely collaborate on private data, unstructured assets, and machine learning models without exposing sensitive information. The platform utilizes Delta sharing and Lakehouse Federation to allow cross cloud and cross platform joint analysis using Python, R, or SQL.
 Events
Data Sharing and Cross-Organization Collaboration. Presented by Matei Zaharia at Data + AI Summit
Cross-organization data sharing and collaboration is increasingly critical for streamlining business processes across industries. Databricks addresses this need through Delta sharing, an open protocol that allows secure data exchange across different platforms and clouds without requiring recipients to use the same data warehouse.
Delta Lake 3.2.0
This release introduces Liquid clustering for incremental optimization and preview support for Type Widening to alter column types without data rewrites. It also adds preview support for Apache Hudi in Delta UniForm tables and improves VACUUM operations with inventory tables and writer protocol checks.
 News
Jet Streaming Data & Predictive Analytics: How Collins Aerospace to Keep Aircraft Flying
Collins Aerospace uses the Databricks lake house platform and Apache spark to power Essentia, a predictive health monitoring product designed to prevent unscheduled aircraft maintenance and reduce flight delays. The platform processes massive multi-source aviation datasets using Delta tables and Delta sharing to streamline data engineering, analytics deployment, and multi-cloud interoperability.
 News
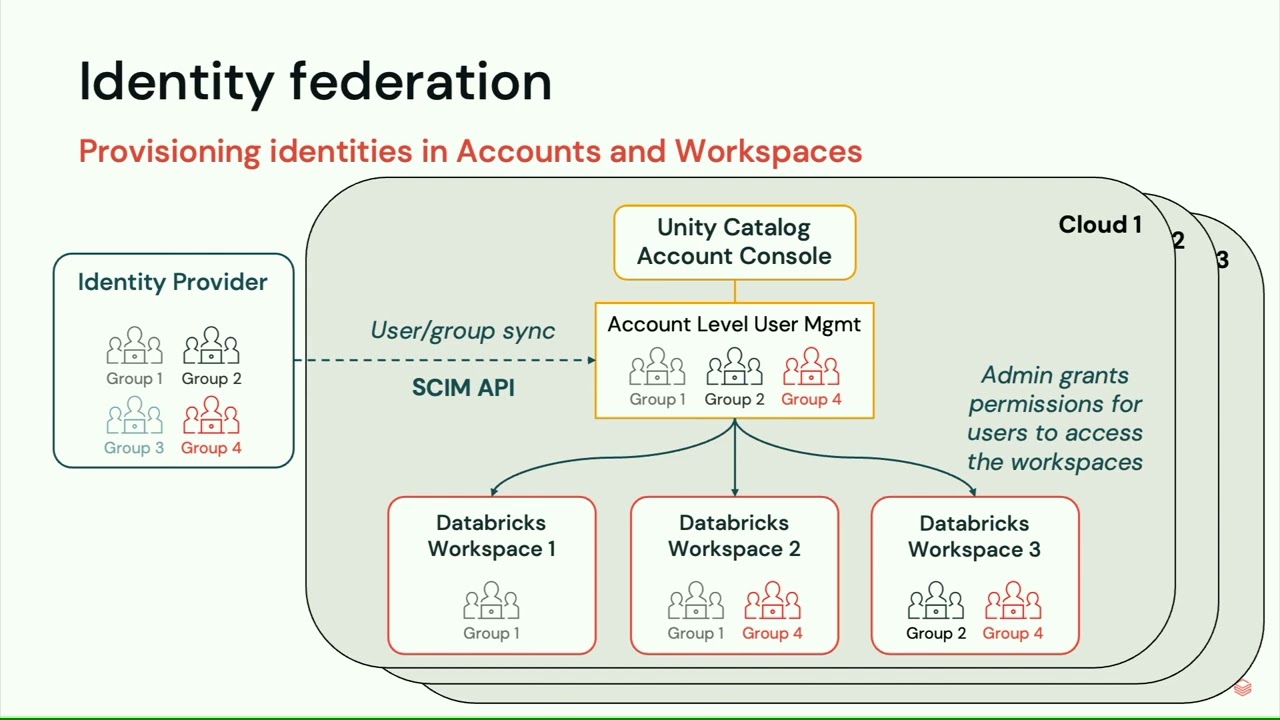
Multicloud Data Governance on the Databricks Lakehouse
Databricks presents multi-cloud data governance on the lakehouse using Unity Catalog to manage users, security, and data lineage across AWS, Azure, and Google Cloud. The session demonstrates how to implement this architecture using Delta sharing and Terraform to securely share data and synchronize entitlements across different cloud regions and business units.
 News
Data Architecture: IQVIA's Migration to Databricks Lakehouse for High-Performance Analytics
Iqvia migrated its global health data workloads to the Databricks Lakehouse, achieving an eighty percent reduction in runtimes and cutting processing costs by sixty percent. The company also used Delta sharing on Databricks to deliver pre-integrated data directly to clients via the Databricks Marketplace, reducing customer infrastructure costs and data delivery times.
 News
Data Democratization with Lakehouse: An Open Banking Application Case
Bradesco implements an open banking and data democratization architecture using the Databricks lake house platform. The solution uses delta sharing, medallion layers, and Unity Catalog to ingest, transform, and securely share financial data across business units and partners.
 Community
Data Globalization at Conde Nast Using Delta Sharing
Condé Nast implemented Databricks Unity Catalog and Delta sharing to build a unified global data platform across multiple international regions. The project successfully eliminated data transfer and duplication costs, ensured regulatory compliance, and reduced workspace deployment time from two weeks to six hours.