Delta Lake
Recent items mentioning Delta Lake across the Databricks ecosystem — releases, news, videos, and community Q&A. Updated hourly.
What is Delta Lake?
Delta Lake is the storage layer that provides the foundation for tables on Databricks. It's open source software that extends ordinary Parquet data files with a file-based transaction log, which turns a directory of files in cloud storage into a real table with ACID transactions and dependable metadata handling. It works with Apache Spark APIs and Structured Streaming, so batch and streaming jobs read and write the same tables.
The transaction log is what makes a lakehouse workable. It gives you schema enforcement on write, time travel for querying earlier versions of a table, a change data feed for tracking row-level changes, and safe concurrent reads and writes, none of which plain Parquet directories can do. Features like liquid clustering and data skipping simplify data layout and speed up queries.
On Databricks it's simply the default: unless you specify otherwise, every table you create is a Delta table. It also plays well outside its own ecosystem. With Iceberg reads enabled, UniForm generates Iceberg metadata alongside the Delta log without rewriting data files, so a single copy of the data serves both Delta and Iceberg clients.
Do I need to do anything to use Delta Lake on Databricks?
No. Delta Lake is the default format for all operations on Databricks, and unless otherwise specified, all tables you create are Delta tables.
How is Delta Lake different from plain Parquet?
Delta tables store their data as Parquet files but add a file-based transaction log next to them. The log is what enables ACID transactions, schema enforcement, and time travel to previous table versions; a plain Parquet directory is just files with none of those guarantees.
Delta Lake vs Apache Iceberg: do I have to choose?
Not for reads. Both formats are Parquet data files plus a metadata layer, and enabling Iceberg reads makes UniForm generate Iceberg metadata alongside the Delta metadata, so one copy of the data serves both kinds of clients. Iceberg client support is read-only; writes aren't supported.
Does Delta Lake cost anything?
The format itself is open source software, so there's no license cost. On Databricks it's built in as the default table format rather than a separately priced product.
Sources: What is Delta Lake? (Databricks docs) · Read Delta tables with Iceberg clients, UniForm (Databricks docs)
Multi-statement transactions reached general availability for both Delta Lake and Apache Iceberg tables on Databricks, bringing atomic multi-table guarantees backed by row-level concurrency and Unity Catalog governance 5. Delta Lake 4.4.1 followed with safeguards for catalog-managed tables, blocking unsupported cleanups and skipping automatic maintenance so writes succeed, plus a fix for snapshot errors from unratified staged commits that lets S3A fast listing be safely re-enabled 6. Around the core, Databricks Free Edition now anchors a full data and AI curriculum on Delta Lake and Spark 4, while MiniLake offers a local Databricks API emulator with SQL, Delta Lake and Spark 3.
Generated daily from the 6 most recent items mentioning Delta Lake. Click any [N] to jump to the source.
Building an AI Search Visibility Tracker With Databricks, Delta Lake, and Python
Best practices and optimization tips for Delta Lake tables
MiniLake Is a Local Databricks API Emulator with SQL, Delta Lake and Spark
--- top comments --- [gavinray] If this actually works, this is such a huge boon. Let me share why: I work on connectors to various datasources, mostly SQL DB's The most useful tests are the integration tests, sending actual queries to the source For most DB's we have a giant Docker Compose which runs a local instance But things like Snowflake, Databricks, Redshift, Athena suck to test because we need an external hosted instance I would kill to be able to run test versions of all of these locally [akbarian] Getting tired of the standard AI design, all websites look the same now [ngruhn] You should call it "pond". [lysecret] Want to hijack this someone made experience recently with https://ducklake.select/ ? We need to setup a warehouse soon and this looks enticing. [asabla] Oh wow! This would've been so useful at my previous work place. I'll save this one for later. Looks pretty decent too for homelabs! I wonder if there is any plans on extending it further? (just a bit)
How to teach with Databricks Free Edition
Databricks Free Edition can anchor a full data and AI curriculum, from intro data science and statistics through data engineering, BI, machine learning, AI, and capstone projects. Students work with the same tools used in industry, including Apache Spark, Delta Lake, MLflow, Lakebase, Genie, and Databricks Apps, while instructors can hand out assignments through an existing LMS or GitHub and share datasets via cloud storage, Open Sharing, or Marketplace.
Transactions are Generally Available, advancing warehousing on the Lakehouse
Multi-statement transactions are now generally available for Delta Lake and Apache Iceberg tables on Databricks, bringing native atomic guarantees to multi-table workflows. Backed by row-level concurrency and Unity Catalog governance, this capability allows practitioners to run critical warehouse workloads directly on open lakehouse data without maintaining separate warehouse systems.
Optimize Delta Lake Write Performance With spark.databricks.delta.optimizeWrite.enabled
Hey, I work as a Databricks Engineer, so here's my take. Small file problems destroy read performance in Delta tables. If your streaming pipelines or frequent batch inserts generate thousands of tiny parquet files, enable spark.databricks.delta.optimizeWrite.enabled at the session or table level. When set to true, Databricks automatically coalesces data right before writing, targeting roughly 512MB per file. This happens dynamically within the shuffle stage, reducing the need for post-hoc OPTIMIZE commands. Pair this with spark.databricks.delta.autoCompact.enabled to automatically compact small files in partitions after writes complete. You will trade a fraction of driver memory and shuffle time for significantly cleaner storage layouts, faster merge operations, and much lower cloud storage list-request costs during downstream reads. For anything else on Databricks | Platform Engineering | AI , visit Abilytics — AI Systems, Data Engineering & Platform Engineering Services. submitted by /u/AbilyticsEng [link] [comments]
Delta Lake 4.4.1
Delta Lake 4.4.1 adds safeguards for catalog-managed tables by blocking unsupported cleanups and skipping automatic maintenance so writes can succeed reliably. It also fixes snapshot construction errors caused by unratified staged commits, allowing safe re-enablement of S3A fast listing.
Databricks Micro Apps, App Spaces and Genie App Generator
Databricks launched App Spaces and Serverless Micro Apps at the end of last week (in Beta). Over the weekend, I tested migrating two of my production Databricks Apps to App Spaces. App Migration 1: Blocked by Zero Egress My Data Portfolio Project Creator required internet access to pull data stacks from live job postings. Then, the LLM needs internet access to research for open data sources to use. In standard Databricks Apps, this runs cleanly. In App Spaces, there is zero external internet egress including for LLMs. The app can reach internal workspace resources, but it cannot touch the outside web. If your app relies on third-party APIs, external databases, or web scraping, App Spaces is a non-starter until Databricks opens network egress. Workload 2: Success on Internal FinOps My client-facing DBU cost observability app reads workspace usage data and writes directly to Lakebase. Because it requires zero external network calls, the migration worked. Both the micro app compute and Lakebase scale to zero when idle. Cold starts take roughly 30 seconds (though in beta, you occasionally need a quick browser refresh once it spins up). For internal, low-frequency administrative tools, this turns a continuous monthly compute bill into pennies. (+ App Spaces, Genie App Generator, and Micro Apps are free while in beta) The next part is less about App Spaces and more just general best practice for Databricks Apps that I see people miss. Stop Using Delta Lake as an OLTP Database Databricks Apps are software applications, not batch analytics notebooks. If your app writes application state, session data, or row-level CRUD directly into analytical Delta tables, you need to rethink that design. For app transactions, use Lakebase (serverless Postgres which also scales to 0). Both are governed under UC, but Lakebase gives your app the low-latency transactional engine that application engineering actually requires. My Verdict on the Beta App Spaces solves the idle compute problem that has plagued Databricks Apps since launch. But until Databricks allows us to deploy directly from existing Git repos and opens external network egress, it remains limited to internal-only use cases. Curious on other peoples experience... How has it been for others? submitted by /u/OkImprovement7010 [link] [comments]
Delta-rs 1.0.0 removes the deprecated S3 DynamoDB log store and adds support for column mapping creation, V2 checkpoints, and deletion vectors in Change Data Feed. The release also introduces custom token credentials for Unity Catalog and fixes Spark interoperability bugs affecting OPTIMIZE and MERGE operations.
Which Came First For You... Spark or Databricks?
Saw a post this morning claiming you shouldn't touch Databricks until you've already mastered Apache Spark. That advice is backwards. It treats learning like a 90s waterfall project and traps engineers in tutorial hell. The fundamentals are non-negotiable: - You need SQL and Python. - You need to understand distributed shuffles, partitions, and memory spills. - You need to understand Parquet structures, metadata footers, and row groups. - You need to understand Delta Lake transaction logs and ACID guarantees. If you don't know what happens under the hood, you will write brittle pipelines that burn cloud budgets. The false assumption is that you must learn these concepts in an abstract vacuum before touching a modern platform. You don't learn networking by memorizing RFC packet headers on a whiteboard for six months before opening Wireshark. You fire up the tool, capture packets, and inspect the traffic. Databricks, Fabric, or Snowflake is your network analyzer. It is the laboratory. Nobody in enterprise production is setting up bare-metal Spark clusters on a home lab just to learn how shuffles work. And running local[*] on a laptop masks real-world distributed realities: - Local filesystems use POSIX atomic renames. Cloud object stores (S3, ADLS) do not. You cannot truly grasp why Delta's _delta_log exists until you see it write commits against cloud storage. - A local JVM masks network serialization, executor skew, and cross-node shuffle overhead. The caveat: don't treat the platform as a black box. Don't just click "Run All" on serverless compute and assume you know Spark. Use the platform to inspect the engine: - Run .explain(True) and read the physical plan. - Open the Spark UI to watch tasks, stages, and memory spill. - Inspect the JSON commits inside _delta_log after a merge operation. - Compact small files and see how file pruning changes scan times. You don't master the theory first and then graduate to a platform. You master the fundamentals by using the platform as your workbench. Learn the platform. Learn the engine. Learn the storage layer. Do it concurrently, in the environment where production actually lives. submitted by /u/OkImprovement7010 [link] [comments]
Deletion Vectors Don’t Delete Data the Way You Think They Do: A Deep Dive into Delta Lake Maintenanc
Getting started with Delta Lake basics
Azure AI Foundry + Databricks Architecture | Deploy Genie Agent with DAB...
Azure AI Foundry Databricks architecture, Deploy Genie Agent with DABs, Databricks Genie Agent, Azure Databricks Genie Space, how to deploy genie agent with declarative automation bundles, azure ai foundry + databricks integration, fully operating genie architecture databricks, databricks unity catalog genie agent, azure databricks bronze silver gold architecture, agent to agent nlq databricks, databricks spark python sql delta lake unity catalog, production ready genie agent deployment, databricks vector search index genie, microsoft purview databricks governance submitted by /u/macxima [link] [comments]
What Data Engineers Need To Know About Delta Lake 4.3
replaceUsing and replaceOn give you a better overwrite primitive, and every catalog-managed table operation now runs through the catalog. submitted by /u/Lenkz [link] [comments]
 News
140. Databricks Lakebase Explained | Episode 1 | Fully Managed PostgreSQL for Lakehouse (2026)
Databricks Lakebase is a fully managed PostgreSQL database that combines the transactional capabilities and ACID compliance of traditional databases with the unlimited scalability of data lakes, enabling low-latency concurrent queries for online applications. The video demonstrates creating a Lakebase project in Databricks, building tables with SQL, and synchronizing data between Lakebase and Lakehouse tables for cross-system queries.
Automatic change data feed is now generally available!
With automatic CDF, Databricks computes row-level changes at read time using row tracking, rather than materializing those changes during every write. Use change data feed on Databricks | Databricks on AWS Why does that mattre? - Better write performance for MERGE INTO and UPDATE workloads - No need to enable CDF individually on every eligible table - Lower storage overhead compared with legacy CDF - The same familiar APIs still work: table_changes() and readChangeFeed - Works with batch processing, Structured Streaming, and Databricks-to-Databricks Delta Sharing For Delta Lake, the main requirements include: • Databricks Runtime 19 LTS+ • A managed table or external table in Delta Lake format with row tracking enabled And if you’re already using legacy CDF, migration is really simple.Once the table meets the requirements, disable legacy CDF: https://preview.redd.it/0dddizd442oh1.png?width=710&format=png&auto=webp&s=fddc536d6aeca423b2e418f4856ae06843393749 submitted by /u/szymon_dybczak [link] [comments]
What is a Data Skipping in Delta Lake?
Southern Company’s SCOUT: Completing the Storm Intelligence Story
Southern Company completed its end-to-end storm intelligence architecture by deploying SCOUT on the Databricks Data + AI Platform, unifying outage, customer, terrain, and crew-planning data into a real-time restoration application. Built on Unity Catalog, Delta Lake, and collaborative notebooks, the solution couples near-real-time data ingestion with governed analytics while leveraging Databricks Genie Code to accelerate pipeline development.
Open Table Formats Explained: Iceberg vs. Delta vs. Hudi
Delta Lake and Apache Iceberg now share governance through catalog-coordinated commits, while metadata trees and transaction logs enable data skipping and time travel that cut query costs without sacrificing access to prior table versions. Interoperability features like Delta Lake UniForm and Unity Catalog let teams query the same underlying data natively as either format across engines like Spark and Trino, reducing vendor lock-in.
Iceberg vs Deltalake (greenfield project with UC in 2026)
I saw the quarterly meeting and was quite shocked that Iceberg is prominently mentioned, (as much as Deltalake). Is it possible that both are getting the same amount of love from Databricks? Is anyone aware of the R&D effort on these formats, and can share conclusions from that? If I'm building a greenfield Unity Catalog, should I just flip a coin to decide what format to use? Here are the main concerns and priorities: Which one is better for OSS Apache Spark reads and writes Which one integrates with external software better (eg onelake shortcuts pointing from Fabric to Databricks UC). When Databricks is innovating within their own UC (eg. introducing new managed table functionality such as "MST Transactions"), which one of these formats are they likely to support first? Which are they likely to optimize better? Which format is more likely to remain 100% open source in the future (or as close to open source as required by customers who want portable blob data). Sorry if this appears to be a common question. I am a Databricks outsider. I am more familiar with Microsoft Fabric. Where that Fabric SaaS is concerned, you can be certain that Deltalake receives a LOT more promotion than Iceberg does. We rarely come across Iceberg, and it probably wouldn't appear in any marketing slide decks. We are likely to create a gold/presentation layer in UC soon. It will basically be created from scratch. It would be nice to know which of these parquet-based formats to pick, when presented with the choice. I understand there is lip-service given to both, and it claims that this choice "doesn't matter". But that doesn't necessarily take into account the potential integrations that are needed with external software (eg. for the benefit of exposing the same tables in onelake). Is one safer than the other? Is one of them a better choice for forward-looking purposes? submitted by /u/SmallAd3697 [link] [comments]
Databricks zerobus vs Fabric open mirroring (2026)
Has anyone seen any comparison between the generalized ingestion mechanism (zerobus) with Fabric's offering (open mirroring)? Seems like there should be a blog or youtube video comparing the two by now. But I haven't seen any. Unfortunately it sounds like they both rely on proprietary middleware. Ideally there would be a similar type of software which that we could just run on-premise to land data into cloud blobs (like a gateway of some kind). Not sure why that would be so hard for someone to do as a github library or something. Maybe it would need to be done in a performant language like rust or .net, but it doesn't seem like it would be rocket science. Both those technologies are relatively recent: Fabric open mirroring : May 2025 Zerobus : Feb 2026 Personally I wouldn't want to pick either one of these technologies until a comparison could be made. Microsoft's open mirroring claims that they can land data in their lakehouses for free. After that point, the raw deltalake tables would be accessible to both platforms. If open mirroring is truly free then it seems odd that any databricks customers would be using zerobus. They should just purchase the smallest possible capacity from Microsoft like an F2, and use that for moving all their data to raw/bronze in adls gen2 containers. Whatever happens after that can take place in either of these two saas'es, databricks or fabric. submitted by /u/SmallAd3697 [link] [comments]
UnityCatalog 0.6.0
This release adds Apache Spark 4.2 support and introduces metric views and SQL views as governed catalog objects for semantic layers and query management. UC access tokens now expire after 24 hours by default, requiring periodic re-exchange instead of the previous indefinite validity.
Delta Lake 4.4.0
Delta Lake 4.4.0 supports Apache Spark 4.2 and adds identity columns and generated-column support in SQL DDL. The release expands UC Delta API integration to Delta Kernel and the experimental Flink connector for catalog-managed tables, introduces Flink upsert mode with merge-on-read updates, and improves VOID-column and partition handling.
Minilake: a free, local Databricks API emulator — a single-developer tool for testing databricks-sdk/Terraform code against real SQL, real Delta Lake, and real Job execution
submitted by /u/agentdero [link] [comments]
🇪🇸 ☕ ¿Cómo organiza Databricks tus datos? | De Unity Catalog a Delta Lake ⚡
Delta Lake 3.3.3
Delta 3.3.3 fixes transaction log retention bugs that broke time travel and CDF reads, and a Delta Sharing deletion vector cache bug causing long-running queries to fail. It adds opt-in RANDOMIZE_FILE_PREFIXES to spread S3 object keys for high-throughput workloads and upgrades Delta Sharing client for improved OAuth and retry handling.
Introducing FILE type: a native column type for multimodal data
The new FILE column type, now in beta, lets you store unstructured data like documents, images, audio, and video natively in your tables. It enables unified governance using standard table access controls and security policies, with community support underway across Delta Lake, Parquet, Iceberg, and Spark for broad portability.
How Dow Built a Carbon Footprint Ledger on Databricks to Accelerate Sustainability at Scale
Dow built an enterprise Carbon Footprint Ledger on the Databricks Data Intelligence Platform, collapsing cradle-to-gate Product Carbon Footprint calculation times from weeks to a fraction of that across its entire portfolio. Powered by Apache Spark, Delta Lake, Unity Catalog, and MLflow, the solution delivers full data lineage and audit-grade governance designed for third-party assurance against ISO 14067 and GHG Protocol standards.
Delta Lake 4.3.1
Delta Lake 4.3.1 fixes OAuth authentication failures in the Delta REST Catalog caused by incorrect key lowercasing and enables S3A fast listing when using OSS UnityCatalog's CredScopedFileSystem wrapper. It also prevents the reserved is_managed_location property from persisting into managed table metadata.
python-v1.6.1: Column Mapping write support
This release adds column mapping write support and BlindDeltaTable for stats-free appends, alongside improvements to data skipping and partition pruning. S3DynamoDbLogStore has been removed in preparation for 1.0.0.
 Releases
Lakehouse//RT, the real-time Lakehouse powered by Reyden — Reynold Xin, Co–founder & Chief Architect
Databricks introduces Lakehouse//RT, a new SQL warehouse powered by the Raiden engine, designed to provide millisecond performance and massive concurrency for real-time analytics directly on data lake formats like Delta and Iceberg. This innovation aims to unify data warehousing and serving stacks, eliminating the need for separate systems and data copies.
 Events
No one needs to care about table formats with Databricks' Ryan Blue, creator of Apache Iceberg
Databricks announced the GA release of Iceberg v3, which unifies data layers so files can be shared across Delta and Iceberg tables without rewriting. The company is also working towards a unified metadata layer in Delta 5 and Iceberg v4, aiming for a full unification vision later this year.
Data Lake vs. Cloud Data Warehouse: A Practical Guide for Data Scientists
Data lakes offer schema-on-read flexibility for ML and advanced analytics, while cloud data warehouses prioritize schema-on-write for high-concurrency BI. Lakehouses, powered by open table formats like Delta Lake, combine the best of both by bringing ACID transactions and BI performance to data lakes.
Delta Lake 4.3.0
Delta 4.3.0 deepens Unity Catalog integration by making it the source of truth for managed table operations via the UC Delta REST API, introduces replaceOn/replaceUsing DataFrame APIs for selective row-level data replacement, and improves UniForm with atomic Iceberg conversion and incremental metadata updates. Delta Sharing gains streaming support, Change Data Feed capabilities, and Trigger.AvailableNow, plus performance improvements like better V2 checkpoint parallelization and variant column statistics for data skipping.
 Events
LTAP - Lake Transactional/Analytical Processing: a new data architecture that unifies OLAP and OLTP
LTAP (Lake Transactional Analytical Processing) is a new data architecture that unifies OLAP and OLTP storage, eliminating data copying and pipelines. It allows a single copy of data for both transactional and analytical systems, built on open formats like Postgres, Delta Lake, and Iceberg, without compromising performance.
What is data pipeline architecture?
Data pipeline architecture separates ingestion, transformation, storage, and serving into distinct layers, with ELT largely replacing ETL as the dominant approach. Databricks unifies batch and streaming pipelines on a single platform (Lakeflow + Delta Lake + Unity Catalog), eliminating duplicate infrastructure and governance gaps.
Introducing OpenSharing: the Next Evolution of Delta Sharing for the Agentic Era
Databricks has introduced OpenSharing, a Linux Foundation-hosted evolution of Delta Sharing that expands zero-copy sharing beyond tabular data to models, agents, and semantic context across Delta Lake, Apache Iceberg, and Parquet. The enterprise implementation on Databricks enables governed sharing of Genie Agents via Unity Catalog, automated private networking with SecureConnect, and low-latency multi-cloud access via Global Distribution.
Your Delta Lake Table Is Secretly Ballooning — Here's the 2-Command Fix
Scaling for MHHS: how Octopus Energy achieved a 50x cost reduction in margin data engineering
Octopus Energy achieved a 50x cost reduction in their margin data engineering pipelines by re-architecting on Databricks for UK MHHS regulation. They leveraged Delta Lake Change Data Feed and Databricks Serverless to process 48x more data at a fraction of the original cost, improving freshness from weekly to daily.
From 400GB to 35GB: Managing Delta Lake Storage Growth
rust-v0.32.3 adds support for the variant data type in Delta Lake schemas. The release is otherwise documentation maintenance with no other user-facing changes.
PyArrow 21.0.0 is now required and brings preliminary variant type support; this release also fixes regressions in MERGE operations, partition column changes, S3 GIL contention, and Unity Catalog operations. New features include typed custom metadata support in CommitProperties and Musl arm64 wheels.
 Community
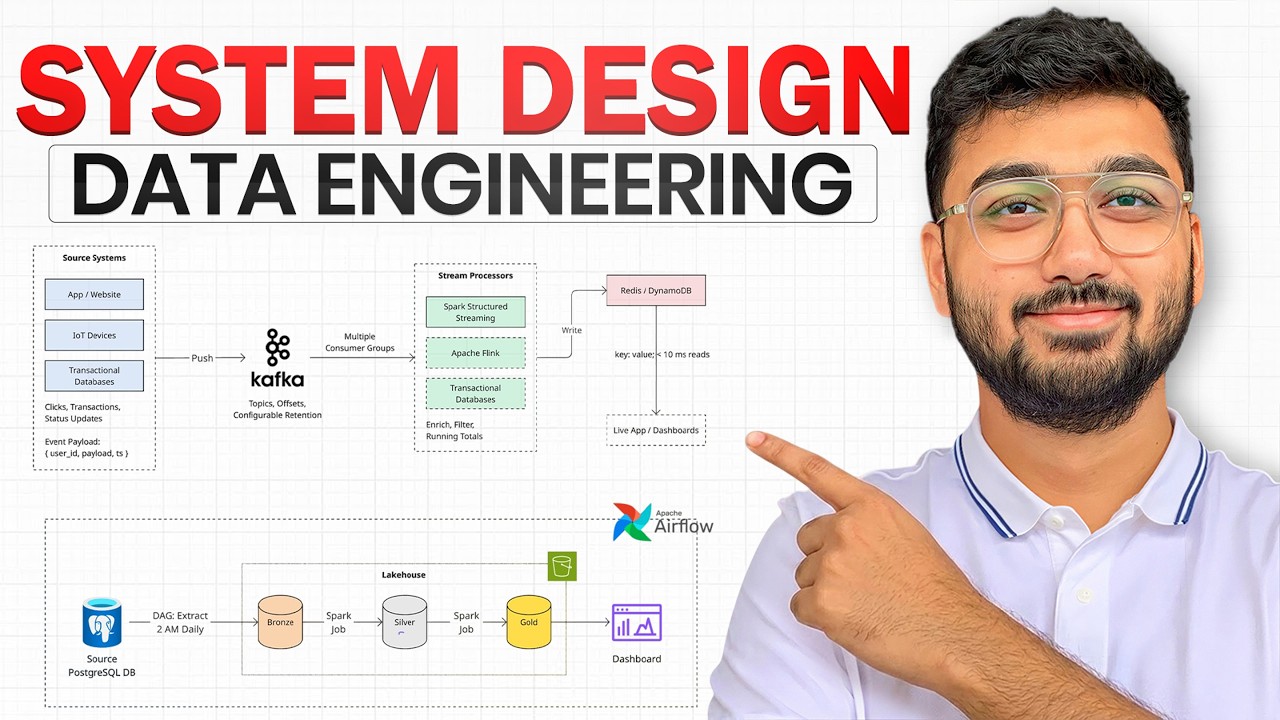
How I Mastered System Design Interviews
This video teaches a six-step framework for mastering data engineering system design interviews, covering requirements gathering, pipeline design, data modeling, storage and file formats, data quality and observability, and pipeline resilience. It demonstrates how to apply this framework with practical examples and back-of-the-envelope calculations to justify design choices.
Enzyme whitepaper - incremental view maintenance
I know this is pretty nerdy stuff, but I found this paper super interesting: "**Enzyme: Incremental View Maintenance for Data Engineering"**. [Enzyme: Incremental View Maintenance for Data Engineering](https://arxiv.org/html/2603.27775v2) IVM (incremental view maintenace) is not a brand-new problem. It has been studied in databases for decades. The basic idea is - when source data changes, Enzyme tries to avoid rerunning the entire query from scratch. Instead, it figures out which parts of the existing result are affected and updates just those parts, while still producing the same result you’d get from a full recompute. What I found especially interesting is how much “under the hood” machinery is needed to make this work reliably: * tracking source table changes with Delta Lake features like Change Data Feed, row tracking, deletion vectors, and time travel * decomposing queries into logical operators like filters, joins, aggregations, and windows * generating delta plans for each operator * deciding whether incremental refresh is actually cheaper than full recompute * handling non-deterministic functions, Python UDFs, query fingerprints, and pipeline dependencies * falling back safely when incrementalization is not worth it or not safe Also, I wasn't aware that a materialized view is not just “the final table.” Under the hood it consists of two parts: 1. backing table - which stores the user’s data plus internal metadata columns 2. top-level view - which describes how the result should be computed, The split architecture of MVs at Databricks, comprising a backing Delta table and a top-level view, provides flexibility for incremental computation. For example, if the top-level view contains AVG(x), Enzyme can internally store SUM(x) and COUNT(\*), because those are easier to update incrementally when new rows arrive. Databricks says Enzyme was validated across thousands of production pipelines and produced cumulative daily compute savings of billions of CPU seconds. On the TPC-DI benchmark, it incrementalized 100% of the workloads and beat full recomputation in 6 out of 8 datasets.
Fixes a MERGE operation memory regression and allows partition column changes during table schema overwrites. Adds nanosecond timestamp support and resolves Python import issues on Linux systems with 64KB pages.
PipelineIQ: Forward‑Looking Sales Intelligence That Drives Action
Your CRM data is a mess. Everyone knows it. Most AI tools pretend it isn't. Databricks took a different approach with PipelineIQ - instead of building yet another forecasting model that assumes clean data (spoiler: it never is), they built a prescriptive action engine that works with the chaos. The result? Every deal in the pipeline gets one of three verdicts: 🚶 Walk - disengage, this isn't worth your time 🔄 Pivot - viable deal, wrong approach 🚀 Accelerate - conditions are right, lean in now No vague "insights." No dashboards that require a PhD to interpret. Just: here's what to do today. Built on Databricks' own stack (Foundation Model APIs, Delta Lake, Unity Catalog) and used internally by their own sales org - this is a rare "we built it for ourselves first" story. Read the full blog here: [https://www.databricks.com/blog/pipelineiq-forward-looking-sales-intelligence-drives-action](https://www.databricks.com/blog/pipelineiq-forward-looking-sales-intelligence-drives-action)
Expanded interoperability with Unity Catalog Open APIs
Unity Catalog Open APIs now offer expanded interoperability, with external access to UC managed Delta tables in Beta and credential vending generally available with M2M OAuth support. External engines like Apache Spark, Flink, and DuckDB can now create, read, and write to UC managed Delta tables, leveraging Delta Lake's new catalog commits feature for safe concurrent writes and audibility.
The Rosetta stone of CPS: Claroty’s AI-powered library
Claroty's AI-powered CPS Library, built on Databricks Custom Agents and Delta Lake, automates entity resolution for 17M+ industrial and healthcare assets, solving the asset identity crisis where 88% of CPS devices lack exact product codes. This multi-agent AI system improves vulnerability attribution accuracy by over 25% and provides new security recommendations for over 56% of analyzed devices.
The Convergence of Open Table Formats and Open Catalogs: Catalog Commits is Generally Available
Catalog Commits for Unity Catalog managed tables is now generally available, aligning Delta Lake with a catalog-oriented model to coordinate table discovery, access, and state across engines. The architectural upgrade eliminates metadata drift between external engines, centralizes cross-engine governance without static storage paths, and unlocks multi-statement, multi-table transactions on the lakehouse.
v0.32.0 provides performance improvements to log parsing, enhancements to the Datafusion TableProvider, and fixes for critical bugs affecting MERGE operations, partitioning, and vacuuming. The release upgrades Datafusion to version 53 and Arrow to version 58.
UnityCatalog 0.4.1
Unity Catalog 0.4.1 adds atomic write guarantees for REPLACE TABLE AS SELECT and Dynamic Partition Overwrite operations on UC Managed Delta Tables, plus a credential-scoped file system to prevent out-of-memory errors in long-running Spark sessions. The release introduces VARIANT datatype support and fixes a critical JWT validation bypass that could allow user impersonation, requiring authorization-enabled deployments to add issuer and audience configuration before upgrading.
Delta Lake 4.2.0
Delta 4.2.0 enables atomic REPLACE TABLE, RTAS, and DPO for catalog-managed tables, enhances streaming capabilities, and adds a Kernel-based Flink connector. The release makes Variant generally available, adds geospatial and collation support, and includes comprehensive security hardening.
 News
Stop Guessing Table Health — Let These Dashboards Tell You
Databricks offers two dashboards for monitoring table health and access: the Table Access Advisor and the Table Health Advisor. These dashboards provide insights into table ownership, read/write patterns, staleness, optimization status, and underlying file structures, helping users identify ghost tables and ensure best practices.
 Tutorials
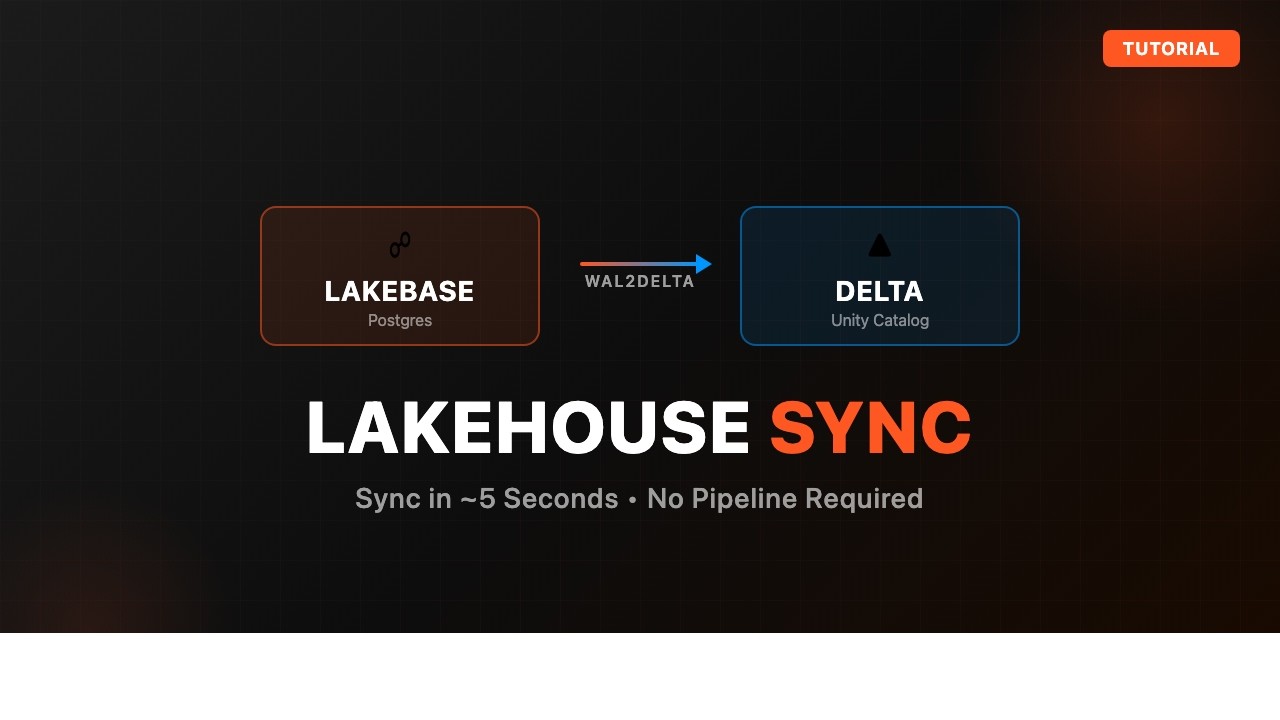
How to Sync Lakebase Tables to Delta with Lakehouse Sync
Databricks demonstrates how to sync Lakebase PostgreSQL tables to Delta tables within a Databricks Lakehouse using the Lakehouse Sync feature. This process enables analytical workloads on data originating from Lakebase applications by leveraging Delta and Spark.
What does Databricks Lakebase mean for analytics engineers?
Databricks Lakebase exposes a PostgreSQL wire protocol interface, allowing analytics engineers to connect standard Postgres tooling and the dbt-postgres adapter directly to their lakehouse. However, migrating existing native Databricks dbt workflows is rarely the right move, as the Postgres interface loses platform-specific Delta Lake materializations and performance optimizations.
Delta Lake 4.1.0
Delta Lake 4.1.0 supports Apache Spark 4.1.0 and introduces conflict-free enablement of Deletion Vectors and Column Mapping on existing tables without blocking concurrent writes. The release requires Java 17 and Spark 4.0.1 or higher (dropping Spark 3.5), adds full catalog-managed table support in Delta Kernel for Unity Catalog integration, and fixes MERGE/INSERT struct expansion bugs.
Delta Lake 4.0.1
Delta Lake 4.0.1 introduces a breaking change renaming catalogOwned-preview to catalogManaged, adds Unity Catalog OAuth with automatic token refresh, and enables UC-managed Delta table creation. It also fixes a Spark 4.0.1 compatibility issue causing NoSuchMethodError in REORG TABLE APPLY (PURGE).
python-v1.3.1: read support deletion vectors, column mapping
This release adds read support for Delta Lake tables utilizing deletion vectors and column mapping. It also includes performance improvements for table scans and predicate pushdown, alongside better error messages for Unity Catalog and LakeFS.
This release introduces several API changes and integrates delta_kernel for improved stats parsing performance. It also fixes issues with schema evolution during merge operations and null handling in scalar extraction.
 Community
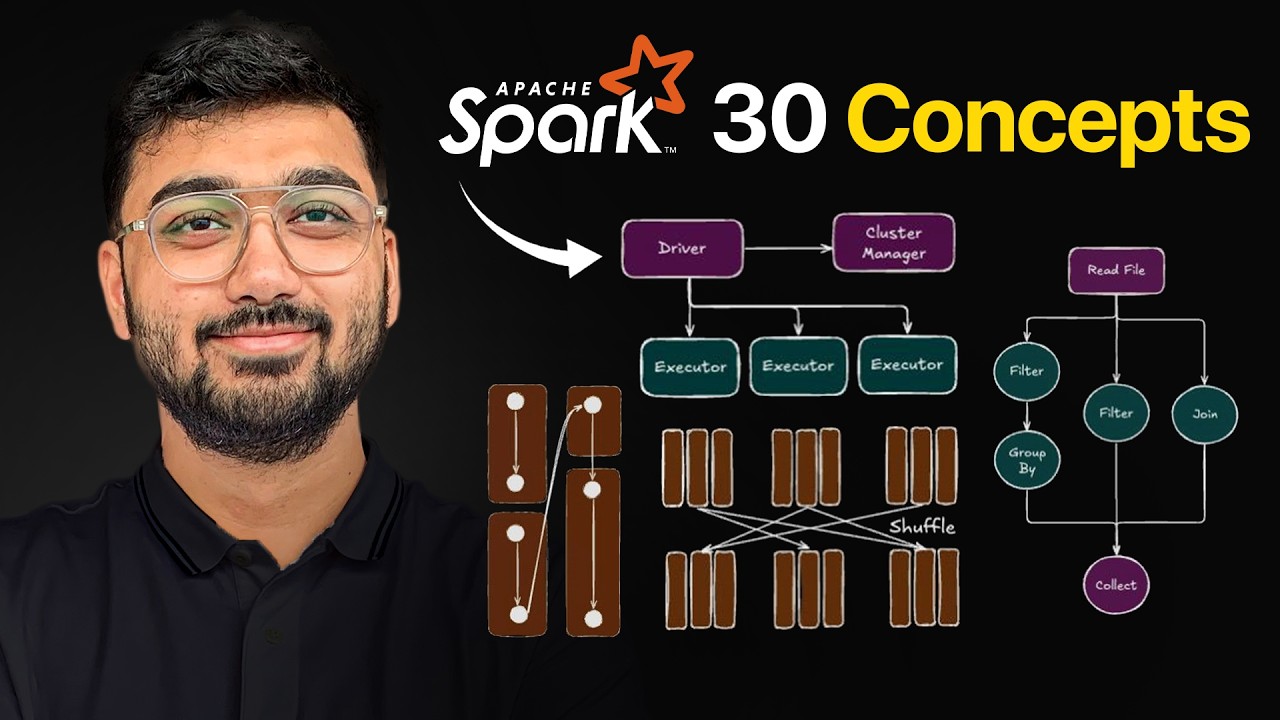
Apache Spark Was Hard Until I Learned These 30 Concepts!
The video explains 30 key Apache Spark concepts, starting with a comparison to MapReduce to highlight Spark's in-memory processing and DAG-based execution model. It then details Spark's cluster architecture, job execution flow (driver, executors, tasks), and memory management within executor containers.