Databricks CLI
Recent items mentioning Databricks CLI across the Databricks ecosystem — releases, news, videos, and community Q&A. Updated hourly.
Databricks CLI v1.20.0 removed the Terraform deployment engine for Asset Bundles, forcing a move to the direct engine or a pin to v1.19.x 10, and the VS Code extension followed by dropping its bundled Terraform binary in v2.21.0 9. CLI v1.23.0 adds workspace.sync_mode (overwrite, in-place, immutable), which replaces the deprecated presets.source_linked_deployment and experimental.immutable_folder settings, and makes databricks ssh connect provide claude and codex 2. The SDKs for Go and Java also fixed CLI authentication so small wrapper scripts and version-manager shims are no longer rejected as the legacy Python CLI 53.
Generated daily from the 10 most recent items mentioning Databricks CLI. Click any [N] to jump to the source.
Release: v2.23.0 (#2277)
The extension now has a databricks.notebooks.configureJupyterCellMarkers setting to stop it writing Jupyter cell-marker settings to workspace settings, and claude and codex are available in SSH tunnel connections with Unity Gateway preconfigured. The bundled Databricks CLI moves to v1.23.0, which restores legacy-import uploads for bundle deploys (so notebooks are no longer uploaded as plain files) and adds workspace.sync_mode, replacing the deprecated presets.source_linked_deployment and experimental.immutable_folder.
Databricks CLI v1.23.0 makes databricks ssh connect provide claude and codex on dedicated clusters and in serverless IDE sessions and non-interactive commands, and adds GPU_1xRTX6000 workload support plus workspace.sync_mode (overwrite, in-place, immutable), which replaces the deprecated presets.source_linked_deployment and experimental.immutable_folder settings. The release also reverts bundle file uploads to the legacy /workspace-files/import-file endpoint to fix notebooks being uploaded as plain files, adds lifecycle.depends_on and bundle deploy --select for deletions, and fixes bundle validate errors when a schedule, trigger, or continuous block is referenced as a whole.
Databricks SDK for Java v0.172.0 fixes CLI authentication so that small wrapper scripts, such as launcher scripts or version manager shims, are no longer mistaken for the legacy Python CLI, which now only applies to the pip entry point. The release also adds budget spend status methods to the account budgets service and an aiFunctionTask field across the jobs task types, with matching aiFunctionTaskOutput on run output.
Adds get_budget_spend_status() and list_budget_spend_statuses() to the account-level budgets service. Fixes files.download_to with use_parallel=True to download byte ranges from presigned URLs or the storage proxy instead of always using the Files API, and to request the correct path for names containing #, ? or %.
Databricks CLI authentication no longer rejects small wrapper scripts, such as launcher scripts or version manager shims, as the legacy Python CLI. Small files in PATH are now rejected only if they are the pip-installed entry point for the legacy Python CLI, and a path set in DATABRICKS_CLI_PATH or databricks_cli_path skips this check.
Lakeflow Connect | NetSuite Connector (GA)
Lakeflow Connect's NetSuite connector is now GA! It provides a managed, secure, and native ingestion solution that accesses NetSuite data through the SuiteAnalytics Connect JDBC driver and lands it in Databricks. The connector supports incremental ingestion, SCD Type 2, and automated schema evolution! Try it now: Set up NetSuite as a data source Create a NetSuite connection in Catalog Explorer Create the ingestion pipeline via the UI, a Databricks notebook, or the Databricks CLI submitted by /u/Brickster_S [link] [comments]
Lakeflow Connect | LinkedIn Ads Connector (Beta)
Lakeflow Connect's LinkedIn Ads connector is now available in Beta! It provides a managed, secure, and native ingestion solution for LinkedIn Ads resource tables (ad accounts, campaign groups, campaigns, and creatives), as well as seven pre-built reports covering daily campaign and creative performance plus monthly member demographics. Try it now: Enable the LinkedIn Ads Beta: Workspace admins can enable the Beta via: Settings → Previews → "Lakeflow Connect for LinkedIn Ads" Set up LinkedIn Ads as a data source Create a LinkedIn Ads connection in Catalog Explorer Create the ingestion pipeline via a Databricks notebook or the Databricks CLI submitted by /u/Brickster_S [link] [comments]
Release: v2.22.0 (#2272)
Release v2.22.0 stops bundle sub-project discovery from blocking the extension host and has VS Code handle proxies and certificates for Databricks SDK calls. It also fixes uv workspace member environment selection and constraint conflicts, and exposes the bundle Configuration view and Bundle Resource Explorer in Remote SSH mode.
Release: v2.21.0 (#2248)
Databricks Asset Bundles now exclusively deploy using the direct engine, removing the Terraform deployment engine and its bundled binary. This release also restores default TLS certificate verification for SDK calls and sorts folders alphabetically in the Workspace File System view.
Run jobs and pipelines as a group
You can now run pipelines as a group, avoiding dependency on a single principal (user or SPN). Databricks CLI 1.20.0 adds run_as.group_name at the bundle and target levels. The group needs its own workspace and data permissions; it does not inherit a member’s personal access. more news https://medium.com/databrickscommunity/databricks-news-serverless-genie-code-ltap-lakeflow-61853d8e422a submitted by /u/hubert-dudek [link] [comments]
Use Genie Code outside the workspace
Hey! I’m a Databricks product manager working on third-party development experiences. We just shipped Genie Code CLI , a new coding agent specialised for data and AI work. We’d love for you to try it out and share what you want to see next! Why we built this: Many of you prefer working locally with agents, but these agents might not always know the best way to work with Databricks. We wanted to provide an agent preconfigured to understand your Databricks data, pipelines, models, and apps. Use this when you want: Minimal setup and maintenance to use an agent that works effectively with Databricks. Governance provided through Unity Gateway. Access to agents outside of the Databricks workspace without model subscriptions or contracts. Getting started: (1) Install the latest version of the Databricks CLI . (2) Install Genie Code CLI : macOS, Linux, WSL: curl -fsSL https://github.com/databricks/genie-code-cli/releases/latest/download/install.sh | bash Windows powershell: powershell -ExecutionPolicy Bypass -c "irm https://github.com/databricks/genie-code-cli/releases/latest/download/install.ps1 | iex" (3) Start an interactive session by running genie in your project directory. Note that usage is billed through Unity Gateway’s model serving capabilities . For full details, check out the Genie Code CLI docs . Share your feedback: We’re releasing this fast to get your input asap. Please leave feedback and questions in the comments or reach out directly with a Reddit message! submitted by /u/BricksTrixTwix [link] [comments]
The Terraform deployment engine for Databricks Asset Bundles has been removed, requiring users to migrate to the direct engine or remain on CLI v1.19.x. Additional updates include a fix for large integer corruption in API commands, group-level run-as support in bundles, and expanded authentication options for Databricks Apps.
Release: v2.20.0 (#2232)
The extension now requires VS Code 1.104 or later and immediately refreshes the Bundle Variables view when overrides are saved or reset. Upgraded Databricks CLI integration migrates bundle deployment state to the direct engine and errors if a configured workspace ID does not match the connected workspace.
Release: v2.19.0 (#2215)
Users can now configure a custom Databricks CLI path and utilize HTTP proxies or corporate CA certificates with the SDK and bundled CLI. The update also resolves a potential ReDoS vulnerability during email redaction on large inputs.
Release: v2.18.0 (#2201)
The Python setup success panel now displays which preset configuration was selected. The bundled Databricks CLI is updated to v1.17.0, enabling SSH sessions to survive transient disconnects for more reliable connections.
Databricks needs an actual validation step in the CI
We use Databricks CLI in our CI-step to first validate and then print plan of the steps being applied - reflected in a comment on the PR. It successfully prints if something is being deleted, updated or created - but it never checks if actually can be applied. We've had green checks because validate and plan prints successfully, but there's no real step to catch a spelling error in a DAB-item if a service-principal exists. Any plans to add something like this to the CLI? submitted by /u/DeepFryEverything [link] [comments]
Direct deployment state version 3 is a breaking change requiring Databricks CLI v1.8.0 or later. New capabilities include Docker credential helpers for Databricks Artifact Registry, AI Gateway service support in bundles, file-change job run triggers, and bundle improvements for resource reference handling, deployment reporting, and state management.
Release: v2.17.2 (#2191)
The bundled Databricks CLI was updated to v1.16.1, fixing an SSH transfer regression for transfers larger than 1 MiB. No other user-facing changes are included in this release.
Release: v2.17.0 (#2187)
The Python environment setup now includes a preset picker for Full, DB Connect, or Python-only configurations with improved error recovery and actionable error messages for common issues. Script uploads now preserve stdout on failure, and the Databricks CLI was updated to v1.16.0.
How to automate downloading files from Databricks to a local machine without PATs or CLI?
Hey everyone, Looking for some advice on automating a workflow in a pretty locked-down corporate environment. Context: Large enterprise with strict IT security and governance. Databricks was recently rolled out as our cloud data hub. The entire pipeline (ingestion, processing, and generating the final CSV) is already automated inside Databricks. I need to automatically save a copy of this generated CSV to a local machine / internal network. Right now, the only way I can do this is manually opening the workspace UI and clicking "Download." Databricks CLI is blocked and Personal Access Tokens (PAT) are disabled How do you usually automate pulling files from the cloud down to on-prem / local machines under these restrictions? Thanks! submitted by /u/Firm_Yogurtcloset835 [link] [comments]
MLflow 3.16.0
MLflow 3.16.0 makes the redesigned trace explorer the default interface, introducing natural-language custom trace views via the MLflow Assistant, session grouping for multi-turn conversations, and span links. The update also adds Unity Catalog model service support for built-in evaluation judges, per-user AI Gateway budget policies, and fail-closed authorization by default.
 Tutorials
How to Connect Your Coding Agent and IDE to Databricks Compute | Databricks SSH Tunnel Demo
Databricks workspaces can be connected to local IDEs and coding agents via an SSH tunnel using the Databricks CLI or IDE extensions. This setup allows developers to write code, use AI coding agents, and run workloads on remote Databricks compute while keeping workspace files automatically synchronized.
Release: v2.16.0 (#2172)
Users can now manually opt out of automated Python environment setup or install uv through a single click. The update also prompts for re-login on local session expiration and fixes a failure when running notebooks containing JSON string cells as Databricks jobs.
Automatically create local Python environments compatible with Databricks Runtime
Hey! I’m a Databricks product manager focused on third-party development experiences. We just shipped a new feature that ensures code you run locally works with Databricks, and we’d love your feedback. The problem: Ensuring that your local development environment is compatible with Databricks Runtime (DBR) is a completely manual process. Code that works locally often breaks once you move to the workspace due to minor version mismatches and package incompatibilities. The solution: The CLI command databricks environments setup-local and a new feature in the IDE extension take your existing dependencies and automatically create a uv-managed virtual environment compatible with DBR. You can now run code locally or remotely using Databricks Connect and be certain that the same code will work with the DBR or serverless version you’ve selected. To get started, install the latest version of the IDE extension or Databricks CLI and check out these docs: Set up your Python environment and Databricks Connect using the IDE extension Databricks environments setup-local CLI command Where we need your feedback Are there other environment managers (e.g. pip, poetry, conda) that you would like to see support for beyond uv? We’ve also recently launched an SSH tunnel (see docs ), which allows you to remotely access your Databricks workspace and compute directly from the IDE and terminal. What are the reasons you might prefer to work locally vs. remotely? Do you face issues managing your environment and dependencies in the workspace? Most importantly, please try this out and leave feedback and questions in the comments! submitted by /u/BricksTrixTwix [link] [comments]
 News
136: Declarative Automation Bundles| Part 3 | Demo
This video demonstrates how to build, deploy, and manage a retail sales pipeline project using Databricks Asset Bundles. It covers installing the Databricks CLI, configuring authentication, validating projects, and using commands to deploy, run, and destroy bundles across different environments.
The SDK now supports group role assumption in OAuth M2M and workload identity federation authentication. New safeguards prevent other credential strategies, including Databricks CLI authentication, from silently accessing normal-access credentials.
Release: v2.15.0 (#2155)
AI tools installation now displays which agents cannot be installed in the picker and Agents tree. The extension warns users when a bundle configuration uses the deprecated Terraform engine.
Databricks Automation Bundles - automatic migration to direct engine post deployment is coming in CLI v1.14.0
Starting with Databricks CLI v1.14.0 , the default bundle.engine will change to direct . If you're not familiar with the advantages of the direct deployment engine over Terraform, you can read more here: Migrate to the direct deployment engine - Azure Databricks | Microsoft Learn What does this mean for us? Bundles will automatically migrate to the direct deployment engine during deployment. If the migration encounter an error, Databricks will keep the bundle on the Terraform engine instead. Important things: You can opt out temporarily by setting bundle.engine: terraform in databricks.yml - either globally or per target. Databricks recommends migrating early by explicitly setting the engine to direct now. Most importantly: support for the Terraform deployment engine in Databricks Automation Bundles is planned for deprection in September 2026 . A future CLI version is expected to stop supporting engine: terraform . submitted by /u/szymon_dybczak [link] [comments]
Lakeflow Connect | Marketo Connector (Beta)
Lakeflow Connect's Marketo connector is now available in Beta! It provides a managed, secure, and native ingestion solution for core Marketo objects: leads, static lists, activities (one table per activity type, like email opens and clicks), and custom objects. Try it now: Enable the Marketo Beta: Workspace admins can enable the Beta via: Settings → Previews → "Lakeflow Connect for Marketo" Set up Marketo as a data source Create a Marketo connection in Catalog Explorer Create the ingestion pipeline via a Databricks notebook or the Databricks CLI submitted by /u/Brickster_S [link] [comments]
Release: v2.14.0 (#2137)
The extension now offers one-click automated Python environment setup that configures a local .venv to exactly match your target cluster's Python version and dependencies, eliminating the classic "works locally, breaks on Databricks" mismatch. Copy actions have been added to the configuration view for easier row management.
Release: v2.13.0 (#2089)
V2.13.0 adds AI tools support and enables Unity Catalog in Databricks Remote SSH mode. The extension can now start SSH tunnels directly, with the Databricks CLI updated to v1.11.0.
Release: v2.12.4 (#2065)
Fixed job run status failing to update when the CLI returns modern job-run URLs. Updated bundled Databricks CLI from v1.7.0 to v1.9.0.
 News
AI Dev Kit 2.0: Databricks AI Tools
AI DevKit 2.0 moves Databricks' agentic coding tools from standalone installation to the official Databricks Agent Skills repository, now installed via the Databricks CLI with improved features and consolidated skills. Users must uninstall the old AI DevKit version and reinstall from the new location, with the MCP server available as a separate optional component.
 Tutorials
How to Go From an Agent Prompt to a Live Databricks App | Databricks Apps Demo
The Databricks Developer Hub provides copyable agent prompts that developers can paste into coding assistants like Cursor to automatically build, configure, and deploy Databricks applications. Developers can also use specialized template prompts from the hub to add advanced features to their apps, such as integrating a natural language chat interface for querying workspace data.
Release: v2.12.3 (#2012)
Fixed OAuth sign-in regression that was incorrectly redirecting users with custom workspace hosts to the public login page. Updated Databricks CLI to v1.7.0, which makes the direct deployment engine generally available and sets it as the default for new deployments.
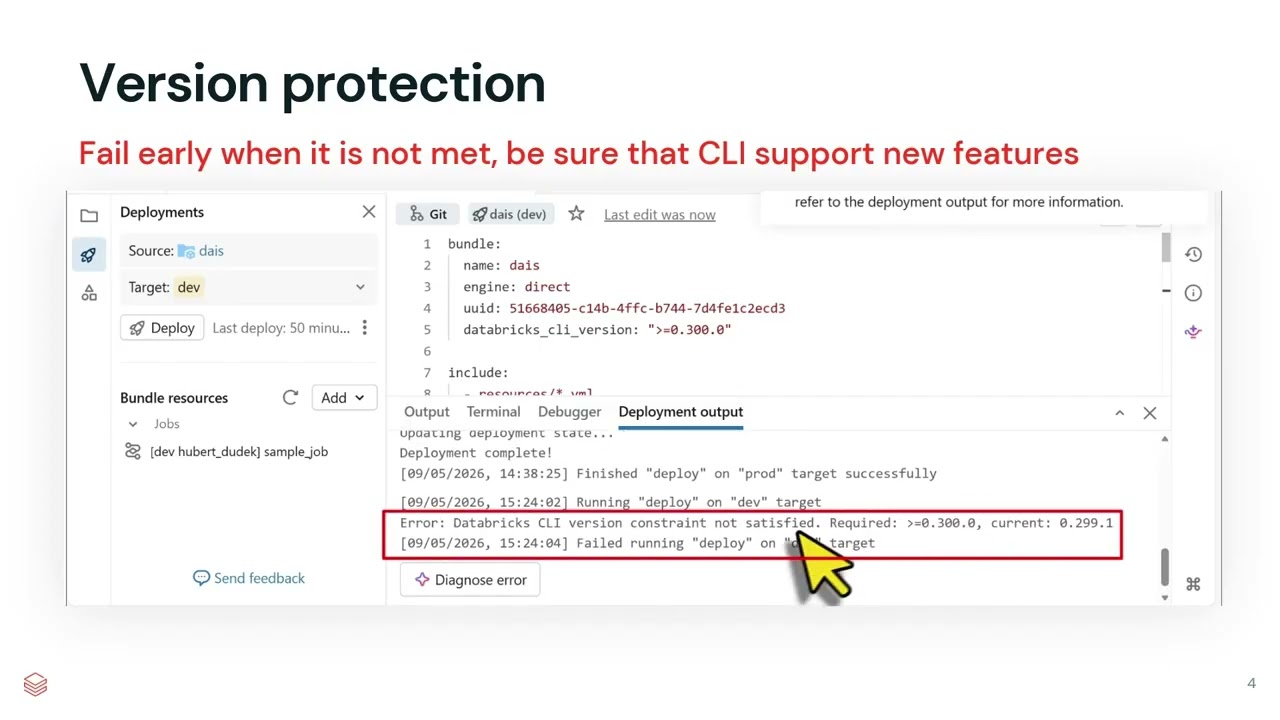
Release: v2.11.1 (#1916)
v2.11.1 fixes Workspace file system operations for folder creation and file uploads, and resolves platform-specific Databricks CLI binary path detection. The release also clarifies Python environment activation messaging and corrects initialization of the WSFS and docs panels on extension startup.
Release: v2.11.0 (#1902)
The release introduces a Unity catalog explorer and workspace filesystem explorer for enhanced navigation of catalog resources and workspace files. It adds support for SPOG host URLs and updates Databricks CLI to version 1.2.0.
 Tutorials
Safe AI-Driven Development with Lakebase Branches
Databricks Lakebase branches enable instant, cost-efficient database branching using copy-on-write, allowing developers to test features in isolated environments without affecting production data. The video demonstrates creating and managing these branches via the Lakebase console and Databricks CLI, and shows how to integrate them into an agentic development workflow for safe AI-driven development.
The config-file loader now correctly sets the profile name to "DEFAULT" when using the legacy fallback, ensuring consistent profile identification for consumers. This fixes issues where per-profile identifiers, like OAuth cache keys, might not match between login and read flows.
 News
Terraform AWS Databricks Deployment Guide!
The video demonstrates how to deploy an AWS Databricks workspace using a provided Terraform script. It covers prerequisites, AWS and Databricks authentication, variable configuration, and executing the Terraform commands to create the workspace.
CLI generally available
Databricks CLI and DABs are generally available, and the first version has been released! #databricks [https://databrickster.medium.com/databricks-news-cli-v-1-0-0-ai-tools-last-updated-25th-may-767ef39abe8a](https://databrickster.medium.com/databricks-news-cli-v-1-0-0-ai-tools-last-updated-25th-may-767ef39abe8a)
Databricks CLI is now 1.0!
Just saw that the Databricks CLI is now 1.0! Besides security improvements, the thing I was most excited about was that we no longer need the \`experimental\` namespace when installing agent skills! Previously it was: \`databricks experimental aitools install\` Now it's just: \`databricks aitools install\` This is purely a cosmetic change, but it definitely gives me more confidence using the command 😅 Also PSA: I learned recently that \`databricks aitools tools\` is the recommended way to install the Databricks agent skills and not via \`npx skills add ...\`. The reason is to ensure we use the proper skills versions recommended by Databricks engineering. I saw that the [official docs for skills](https://docs.databricks.com/aws/en/agent-skills/) still show \`npx skills add ...\`. So I'm working on getting that updated asap. Sorry abut that 🙏 \--- Full release changelog can be viewed here: https://github.com/databricks/cli/releases
Databricks CLI v1.0.0 is now generally available, moving interactive OAuth token storage to OS-native secure stores by default and requiring users to re-authenticate with databricks auth login. This release also introduces the databricks aitools command group for managing coding agent skills and adds new Lakebase Postgres resources for Databricks Asset Bundles.
Databricks Connect v2.10.7 wants admin permissions on local machine
Anyone experienced this already? When I (auto)updated databricks connect plugin in VSCode today I needed to create a new Auth profile. I was taken to a new login screen where I needed to give Databricks admin permissions (which I can't give on company resources). Anyone experienced this / has way around it? Somehow it mostly seems to affect the Databricks connect plugin as my CLI seems to work,but this doesn't bode well for the (near) future. (edited company info out) https://preview.redd.it/m27ignwc232h1.png?width=434&format=png&auto=webp&s=f05168a6c95cdba6b753628ad15256245d129ddc # packages/databricks-vscode # (2026-05-07) * Add remote mode for initial Remote Development compatibility (#1861) ([9e768db](https://github.com/databricks/databricks-vscode/commit/9e768db)) * Rename "Databricks Asset Bundles" → "Declarative Automation Bundles" (#1864) ([62a94e1](https://github.com/databricks/databricks-vscode/commit/62a94e1)) * Preserve profile name in Databricks CLI auth provider (#1877) ([3f54441](https://github.com/databricks/databricks-vscode/commit/3f54441)) * Fix new profile sign in using already existing host under different profile (#1893) ([c4c25fb](https://github.com/databricks/databricks-vscode/commit/c4c25fb)) * Include profiles with `account_id` in `listProfiles` results (#1894) ([d6e2e5d](https://github.com/databricks/databricks-vscode/commit/d6e2e5d)) * Update minimal python and dbconnect versions for serverless (#1884) ([5a1a1d5](https://github.com/databricks/databricks-vscode/commit/5a1a1d5)) * Update Databricks CLI to v0.297.2 (#1882) ([ea77424](https://github.com/databricks/databricks-vscode/commit/ea77424)) — see the [CLI release notes](https://github.com/databricks/cli/releases) for changes since v0.286.0
Lakeflow Connect | HubSpot (GA)
Hi all, Lakeflow Connect's HubSpot connector is now GA! It provides a managed, secure, and native ingestion solution for the HubSpot Marketing Hub — ingesting marketing campaigns, and email analytics into Databricks. Try it now: 1. [**Set up HubSpot as a data source**](https://docs.databricks.com/aws/en/ingestion/lakeflow-connect/hubspot-source-setup) 2. [**Create a HubSpot Connection in Catalog Explorer**](https://docs.databricks.com/aws/en/connect/managed-ingestion#hubspot) 3. [**Create the ingestion pipeline via the UI, a Databricks notebook, or the Databricks CLI**](https://docs.databricks.com/aws/en/ingestion/lakeflow-connect/hubspot-pipeline)
Mitigation for "error downloading Terraform" during bundle deployments
If your CI/CD pipelines suddenly started failing out of nowhere with this error: "𝐞𝐫𝐫𝐨𝐫 𝐝𝐨𝐰𝐧𝐥𝐨𝐚𝐝𝐢𝐧𝐠 𝐓𝐞𝐫𝐫𝐚𝐟𝐨𝐫𝐦: 𝐮𝐧𝐚𝐛𝐥𝐞 𝐭𝐨 𝐯𝐞𝐫𝐢𝐟𝐲 𝐜𝐡𝐞𝐜𝐤𝐬𝐮𝐦𝐬 𝐬𝐢𝐠𝐧𝐚𝐭𝐮𝐫𝐞: 𝐨𝐩𝐞𝐧𝐩𝐠𝐩: 𝐤𝐞𝐲 𝐞𝐱𝐩𝐢𝐫𝐞𝐝" and you’re using Databricks CLI - you’re probably hitting the same issue I did. The Databricks CLI needs to be upgraded. Databricks released patched CLI versions after an expired verification key started breaking bundle deploy commands in CI/CD environments. Hopefully this saves someone else some troubleshooting time. https://preview.redd.it/7ree9cuvo21h1.png?width=861&format=png&auto=webp&s=47c46407d20e4b552d1b5e79258e761cba8f48cb [Mitigation for "error downloading Terraform" during bundle deployments · Issue #5022 · databricks/cli](https://github.com/databricks/cli/issues/5022)
This release fixes an issue where the Databricks CLI --profile fallback was broken. It also introduces new API methods for workspaceClient.supervisorAgents() and workspaceClient.vectorSearchEndpoints(), along with several breaking changes related to Example and Tool fields, and minQps in Vector Search endpoints.
This release introduces new methods for managing supervisor agents and vector search endpoints, along with several new fields for connector options, ingestion sources, and customer-managed keys. Breaking changes include the removal of min_qps fields from vector search endpoint configurations and making guidelines and description fields optional in certain services.
Release: v2.10.7 (#1895)
Remote Development mode is now available in the extension for VS Code remote setups. Databricks Asset Bundles has been renamed to Declarative Automation Bundles and profile authentication issues have been fixed.
Fixed Databricks CLI --profile fallback by detecting the CLI version at init time. The previous error-based detection was broken because --profile is a global Cobra flag silently accepted by old CLIs.
Unified host detection is now automatic, removing the Experimental_IsUnifiedHost field and enabling a single configuration profile for both account and workspace operations. The file-based OAuth token cache has been removed, defaulting to an in-memory cache unless a persistent cache is explicitly provided.
This release adds Azure MSI authentication support and improves .databrickscfg default profile resolution. It also fixes issues with non-JSON error responses and Databricks CLI token scope mismatches, alongside several API additions and two breaking changes.
Databricks CLI v0.297.2 fixes a critical "key expired" error that prevented databricks bundle deploy from downloading Terraform. This was resolved by using a hardcoded ArmoredPublicKey for Terraform binary installations.
Databricks CLI authentication now correctly errors on token scope mismatches, prompting re-authentication instead of silently using incorrect permissions. New dataclassification and knowledgeassistants services and corresponding workspace-level APIs have been added.
Release: v2.10.5 (#1834)
Update Databricks CLI to v0.286.0
 News
Databricks Breaking News: Week 2026 02: 5 January 2026 to 11 January 2026 #databricks news
Databricks now allows changing catalog and schema during dashboard deployments, addressing a previous issue with environment-specific configurations. The Databricks CLI has a breaking change with plan version 2, altering the structure of deployment plans.
Release: v2.10.4 (#1821)
Update Databricks CLI to v0.280.0
Release: v2.10.3 (#1772)
This release updates the Databricks CLI to v0.266.0, which includes breaking changes. Databricks practitioners should review the CLI release notes for details on these changes.
 Tutorials
51 Setup Azure DevOps Pipeline with Databricks Asset Bundles (DABs) | Complete CICD Process
The video demonstrates how to set up an Azure DevOps pipeline to deploy Databricks Asset Bundles (DABs) to higher environments like QA. It covers configuring service principal permissions, setting up Azure pipeline variables for environment-specific details, and writing the YAML pipeline code to validate and deploy Databricks assets.