Data Quality
Recent items mentioning Data Quality across the Databricks ecosystem — releases, news, videos, and community Q&A. Updated hourly.
Databricks SDKs shipped data quality API updates across three languages in four days: Go v0.191.0 adds unhealthy-table notifications for data quality 3, while Java v0.171.0 and Python v0.157.0 add new data quality fields and notification support 57. Outside the platform, Figma's data science team uses ordinary dbt tests as consistency checkers that catch more than 100 billing bugs a month 4.
Generated daily from the 10 most recent items mentioning Data Quality. Click any [N] to jump to the source.
transformations API
Hi, how much SQL text do you allow in Python modules? We have a lot of SQL, but we dont want to move fully to dbt, because we run data quality checks before the write, and we like the Python modular approach with tests and everything around it. So where do you draw the line: - SQL as strings in Python, run with `spark.sql()` - SQL in `.sql` files in the package, loaded by Python and run with parameters - refactor to the PySpark DataFrame API - or just stick with pure SQL scripts And how did you standardize it in your team? submitted by /u/ptab0211 [link] [comments]
Why a semantic layer is the difference between a 96% and an 80% accurate AI analyst
In a dbt Summit 2026 session, dbt Labs' Alex Noonan argued that grounding is what's left to solve for AI analysts. A dbt Labs benchmark found a model answering through a semantic layer scored 96 to 100% accuracy, versus 80 to 91% when the same model wrote raw SQL against a database schema. He also covered the other grounding approaches (ontology-style models and agent context layers) and the unglamorous fundamentals that make them durable, including data quality checks, machine-readable documentation, and visible, public-channel feedback.
Release v0.191.0 adds SDK methods for AgentKit memory and session store permissions, budget spend status queries, feature engineering materialization sets, and starting or stopping vector search endpoints. It also adds external spend inclusion for budgets, unhealthy-table notifications for data quality, relative error options for approximate count-distinct and percentile functions, and table trigger conditions and timing controls.
How Figma turned dbt tests into consistency checkers that catch 100+ bugs a month
Figma's data science team uses ordinary dbt tests as consistency checkers that act as an early warning system for billing bugs, catching more than 100 a month. The post shows how you can get that kind of data quality coverage from standard dbt tooling, with no exotic infrastructure.
Databricks SDK for Java v0.171.0 adds AgentKit permission methods for memory and session stores, Feature Engineering materialization set methods, and new fields across data quality, jobs, ML, pipelines, and sandbox APIs. The release also adds refresh-by-path selection fields to pipeline updates and a fileOutput option on jobs SQL outputs.
Beyond the Dashboard: Why AI Data Assistants Fail Without Unity Catalog Governance
For years, the promise of self-service BI has been a moving target. We gave business users drag-and-drop tools, semantic layers, and natural language query bars. Yet, time and again, we hit the same wall: trust. When a business user asks an AI tool, "What was our fleet downtime last quarter?" , the AI is only as good as the underlying data fabric. If your data is trapped in fragmented silos, uncatalogued, and un-governed, conversational AI quickly becomes an expensive generator of confident misinformation. This is where the paradigm is shifting. With the introduction of tools like Databricks Genie , we are moving past rigid dashboards into the era of conversational analytics. But as Solution Architects, our job isn't just to look at the UI layer—we have to look at the spine of the architecture. Here are three architectural realities I’ve learned while implementing modern Lakehouse patterns: 1. AI Without Governance is Just Automated Chaos You cannot point an LLM at a raw storage bucket and expect accurate insights. Genie relies entirely on the metadata, table descriptions, and foreign key relationships defined in Unity Catalog . If your governance layer is messy, your AI's answers will be messy. Unity Catalog isn’t just a security tool anymore; it is the semantic foundation for enterprise AI. 2. The Shift from "Building Pipelines" to "Curating Context" Tools like Lakeflow Connect and automated ingestion frameworks are taking over the heavy lifting of ETL. As data engineers and architects, our value is no longer measured by how many custom Spark scripts we write to move data. Our value is measured by how well we curate the Gold layer —structuring tables, defining clear column descriptions, and setting up quality expectations so that tools like Genie can actually understand the domain context. 3. Real-Time Trust Beats Real-Time Speed In heavy industries—like managing IoT telemetry for gas turbines—getting data in 5 seconds doesn't matter if the data quality is flawed. Integrating Delta Live Tables (DLT) Expectations as a quality firewall before data hits the consumption layer ensures that both human analysts and AI assistants are querying verified, pristine data. The Takeaway Conversational AI and natural language agents like Genie are the future of data consumption. But they are built on a simple architectural truth: Garbage in, hallucination out. If we want business users to trust AI-driven insights, we have to start by modernizing our foundations with robust governance, automated pipelines, and strict data quality gates. Curious to hear from other architects out there: Have you started deploying conversational AI tools to business users yet? What are the biggest governance or data trust hurdles you've had to overcome? submitted by /u/SalamanderOpen859 [link] [comments]
v0.157.0 adds Agent Kit methods for granting, revoking, listing, and getting memory and session store permissions, plus create, get, update, and delete methods for Feature Engineering materialization sets, along with new fields for data quality notifications, SQL task file output, pipeline refresh-by-path selection, and sandbox metadata. It also requires certifi 2026.10.19 or newer to pick up an updated CA trust bundle.
 News
Building Reliable Data Pipelines with Lakeflow on Databricks | Lakeflow Demo
Databricks Lakeflow provides a data intelligence platform for building and managing reliable data pipelines. The demonstration covers creating delta tables, ingesting data from Salesforce using Lakeflow Connect, and using Lakeflow Designer for data transformation and orchestration.
Databricks Lakebridge Internals & Usecase
Databricks Lakebridge: Simplifying Data Migration to the Lakehouse Migrating legacy data platforms to Databricks is more than moving data. It also involves understanding existing workloads, converting SQL and ETL logic, and validating results. This is where Databricks Lakebridge can help! What is Lakebridge? Lakebridge is a migration toolkit designed to accelerate the modernization of legacy data platforms and workloads on Databricks. How does it help? 1. Assess Analyze existing SQL workloads and code to understand complexity, compatibility, dependencies, and migration effort. 2. Convert Help translate legacy SQL and supported ETL workloads into Databricks-compatible SQL, PySpark, or notebooks. 3. Reconcile Compare source and target datasets to identify discrepancies in schemas, rows, and column values after migration. A practical example Imagine migrating an Oracle-based data warehouse to Databricks. Instead of manually reviewing every SQL script and validating every migrated table from scratch, Lakebridge can help: ➡️ Analyze existing Oracle SQL workloads ➡️ Identify migration complexity ➡️ Accelerate SQL conversion ➡️ Validate migrated data against the source The result? A more structured, repeatable migration process with less manual effort. 🔹 Why should data engineers care? As organizations modernize their data platforms, migration is not just about changing technology. It is about preserving business logic, maintaining data quality, reducing risk, and making the most of the lakehouse architecture. Lakebridge can support this journey by automating key migration activities, while engineering review and testing remain essential. Remember: Automated code conversion does not guarantee business-equivalent results. Always validate converted logic and reconcile the data before production cutover. 🔗 Official documentation: https://databrickslabs.github.io/lakebridge/docs/overview/ Have you explored Lakebridge for your Databricks migration projects? What has your experience been with automated SQL conversion and data reconciliation? #Databricks #Lakebridge #DataEngineering #DataMigration #Lakehouse #ETL #DataModernization #BigData submitted by /u/Krishgarikipati [link] [comments]
Things I miss on Databricks
Here are a couple of things I miss on Databricks: Group jobs per category. We all know that jobs can become messy sometimes. Connect jobs in Git more easily Data Quality. Like for real, where users can establish rules, create scans, quarantine, break pipelines, and etc. I don’t want to take my data outside to do it. App Genie Builder that won’t force me going to bundle Scale to zero apps without needing to use App Genie Builder Similar to 1, grouping queries, we all know that it can get messy with time Auto TTL in Lakebase (don’t know if it’s possible, but that’s a very good functionality) What else do you miss in Databricks? submitted by /u/Select_Morning8221 [link] [comments]
Data Quality in Microsoft Fabric – Native features vs. external tools (like Databricks Expectations)?
Hey everyone! I’ve been working a lot with data quality frameworks in Databricks (leveraging things like Delta Live Tables expectations or custom validation notebooks), and I'm curious about how the community is handling Data Quality in Microsoft Fabric. Does Fabric have a native, built-in feature for data quality/expectations (similar to what Databricks offers), or are most of you relying on external tools, libraries (like Great Expectations/Soda), or custom PySpark/SQL validation notebooks inside Data Engineering pipelines? How are you currently enforcing quality checks before data hits your Gold/Semantic layers in Fabric? Would love to hear your approaches and best practices! I read this documentation here: https://learn.microsoft.com/en-us/purview/unified-catalog-data-quality-fabric-lakehouse?WT.mc_id=510336 , but it doesn't say much. submitted by /u/SuperbNews2050 [link] [comments]
Time to Swap the Cookies for Jetfuel - New Dataset & New Databricks Genie Tutorial
Most of you know samples.bakehouse . Great for a first query. Perfect for a quick demo. But after years of cookie sales, it's a little overbaked. Time to swap the cookies for jet fuel. ✈️ Together with the OpenSky Network , I brought a full day of global air traffic to Databricks Marketplace: 696 million real ADS-B position reports, messy just like real life. Myself, I used Genie for the whole journey: EDA, data exploration, a Apache Spark Declarative Pipeline, and a Lakeflow Job. Then I went a step further and read the same Marketplace data with open-source tools only, using OpenSharing and pandas. The result is this hands-on tutorial: Marketplace + Unity Catalog: get the data as a governed table Genie Agents: find anomalies in plain English Genie Agents: explore and visualize with maps and charts Genie Code: a Spark Declarative Pipeline, bronze to gold, with data quality rules Genie Code: a Lakeflow Job with schedule, retries, and email alerts Databricks Apps: your coding agent, governed by Unity Catalog OpenSharing: the open-source client in VS Code with pandas Everything runs on Databricks Free Edition (free, no credit card). 📖 Tutorial: Databricks Genie for Data Engineers and Data Scientists 💻 GitHub: databricks/tmm/DSDE-Genie-Tutorial 🛫 Dataset: OpenSky Network full-day dataset on Marketplace What's the first thing you'd query in a day of global air traffic? P.S. For the record, we still love bakehouse! 🍪❤️ [Disclaimer: I'm one of the two people who baked it.] submitted by /u/CompetitiveBet8978 [link] [comments]
DQ Management
Hi, we have a lot of data products, how do u design your data quality, and what tools do u use? Idea is that we use dqx, we define rules (ERROR, WARN), and enforce that in pre write of the data, which is to be honest a new thing. Then i would also like to have anomaly checks, where i could compare stats of current batch run to the previous one. How do u design your dq around dqx? And what else do u use? What "flow" do u use? submitted by /u/ptab0211 [link] [comments]
Databricks Data Quality - Agent Proposes, DQX Disposes
New features in Lakeflow Designer
New in Lakeflow Designer (screenshots below): 🚀 Genie can now create custom operators for you. For example run t-tests, create PDFs, send Slack messages etc. 🚀 Guardrails operator for Data quality checks 🚀 Multi join 🚀 Excel & CSV export controls 🚀 Output operator acts like a source for the destination it writes 🚀 Parameter suport in more operators (Combine, Limit) 🚀 Disable operators submitted by /u/zaboca_v [link] [comments]
Anyone running actual SLOs on Lakeflow Jobs, or is it still “it failed, rerun it”?
I own the platform side for a couple of data teams. Got asked why I could produce an availability number for every service we run except the pipelines, so I went to build one off system tables. More awkward than I expected. Two things cost me an afternoon. job_run_timeline records up to an hour of runtime per row, so anything running longer is spread across several rows, and result_state / termination_code are only populated on the row that ends the run. My first success-rate query counted every intermediate row as a non-success and the numbers came out apocalyptic. Second, records land within about an hour. Fine for an error budget, useless for paging. So it ended up split: job notifications and webhooks for "wake someone up", system.lakeflow for "are we actually hitting the number". 365 days of retention is plenty for the trend. What I have now is per-job success rate and p90 duration against a target, rolled up by owner, in the same dashboards as everything else. The useful part wasn't the dashboard, it was that "this pipeline is flaky" became "this pipeline burned most of its budget in a week", which lands very differently with the people who own it. What I can't tell is whether anyone does this seriously. Most of what I read treats a job failure as a data quality thing you retry, not a reliability number someone is accountable for. So: does your org have a real target for pipeline reliability, and who owns it — platform or the data team? submitted by /u/AbilyticsEng [link] [comments]
From Data Quality to Context Quality
Built a Databricks medallion pipeline for NYC Taxi data
Been working on this as a way to get hands-on with Databricks Asset Bundles and Unity Catalog governance. It's a migration of an old on-prem NYC Taxi analytics stack (ClickHouse + Spark + Docker + Terraform) into a proper Bronze/Silver/Gold lakehouse. A few things I focused on: Auto Loader for incremental ingestion, triggered by file arrival Data quality handling that doesn't just drop bad rows — duplicates, zero-distance trips, and reversed fares go into dedicated quarantine tables instead of being silently discarded Databricks Asset Bundles for deploy/orchestration (dev + prod targets) 3 published AI/BI dashboards on top of the Gold layer (fleet ops, finance, compliance) It's intentionally small in scope — meant to demonstrate the lakehouse pattern, not be a production-scale platform. Currently only Green Taxi data; FHV comparison is planned next. Repo: https://github.com/Hamza-Bouali/NYC-DATABRICKS Would love feedback, especially on the Silver-layer data quality rules or the bundle structure open to critique. https://preview.redd.it/ej6hvzrbokph1.png?width=1667&format=png&auto=webp&s=b090b2c5165efcc83fb3f2b5c38ff6ef34c8ef48 https://preview.redd.it/rih9a5sbokph1.png?width=1879&format=png&auto=webp&s=1b85b90608e1b1273da4f8cbb4fa65d9f2c397a7 https://preview.redd.it/kjdor4sbokph1.png?width=1687&format=png&auto=webp&s=677c6194ede0cd01a8630ee98f85d11a5146b410 submitted by /u/No-Pollution-2274 [link] [comments]
Building for Failure: Implementing Data Quality Firewalls in Petabyte-Scale Medallion Architectures
No more UNION ALL-ing all of your SDP pipeline event log tables for monitoring
https://preview.redd.it/3w0j4ss3inoh1.jpg?width=2048&format=pjpg&auto=webp&s=50bc79280a546544e8f795947e5af6b211e9596a Hi folks, Databricks PM here - I wanted to share an exciting update that you no longer have to manually publish and combine your pipeline event logs for monitoring across pipelines and workspaces. We just launched the beta for the pipeline events system table (system.lakeflow_pipeline_events_preview.pipeline_events). Key features: All pipeline events (regardless of cluster start) are automatically captured without any manual enablement or maintenance. Events are aggregated in a central system table without requiring any custom aggregation logic. This data is available at close to real time latency (based on our internal testing we achieve a P99 latency of less than 1 minute). An admin can grant a single user access and they can query events for every pipeline in the table. Fine-grained access controls support which scopes the visibility to only the pipelines the user has access to is coming soon. The data remains in the system table even after pipeline deletion and is retained for 13 months. If you want longer retention this is also possible with the configurable retention feature for System Tables. Query ergonomics are better now with the use of VARIANT. Here are some sample queries in case you want to try them out: -- The latest error for each pipeline that has errored in the last 7 days, with the outermost exception. -- The exception chain is ordered with the root cause last, so read element -1 for the root cause. -- On many errors only the first element carries error_class and sql_state. SELECT workspace_id, pipeline_id, event_time, event_type, message, error.exceptions[0].error_class AS exception_error_class, error.exceptions[0].sql_state AS exception_sql_state FROM system.lakeflow_pipeline_events_preview.pipeline_events WHERE level = 'ERROR' AND event_time >= current_timestamp() - INTERVAL 7 DAYS QUALIFY ROW_NUMBER() OVER (PARTITION BY workspace_id, pipeline_id ORDER BY event_time DESC) = 1 ORDER BY event_time DESC -- Flow throughput for a specific pipeline SELECT origin.flow_name, date_trunc('HOUR', event_time) AS hour, SUM(variant_get(details, '$.flow_progress.metrics.num_output_rows', 'BIGINT')) AS rows_written FROM system.lakeflow_pipeline_events_preview.pipeline_events WHERE pipeline_id = ' ' AND event_type = 'flow_progress' AND event_time >= current_timestamp() - INTERVAL 7 DAYS GROUP BY origin.flow_name, date_trunc('HOUR', event_time) ORDER BY hour DESC, rows_written DESC -- Data quality: failed expectations by dataset, per update, in the last 1 day SELECT pipeline_id, update_id, origin.dataset_name, expectation.name AS expectation_name, SUM(expectation.failed_records) AS failed_records FROM system.lakeflow_pipeline_events_preview.pipeline_events LATERAL VIEW explode(variant_get(details, '$.flow_progress.data_quality.expectations', 'ARRAY >')) AS expectation WHERE event_type = 'flow_progress' AND event_time >= current_timestamp() - INTERVAL 1 DAY GROUP BY pipeline_id, update_id, origin.dataset_name, expectation.name HAVING SUM(expectation.failed_records) > 0 ORDER BY failed_records DESC; Beyond single queries you can build alerting (using Databricks SQL alerts) and dashboards. We will share a new dashboard template soon - I will update this post once its available. Call outs: This is in beta right now, if you are not opted in we will not capture your event log data. Enablement: Toggle on the “ Lakeflow Pipeline Events System Table ” from the account level preview. Docs are linked here , would love to hear your thoughts on how you will use it or what else you want to see to improve observability! submitted by /u/brickster_123 [link] [comments]
Do UC table tags propagate to billing for Predictive Optimization and Data Quality Monitoring?
Databricks 5 Minute Features: Governance Hub
Check out the Databricks Governance Hub in my latest 5 Minute Features. A one-stop-shop for all your governance needs; Cost Control, Access, Data Quality, AI Usage all in one place! submitted by /u/Remarkable_Rock5474 [link] [comments]
Query works in Databricks SQL but fails through JDBC
I’ve noticed cases where a query runs successfully in the Databricks SQL editor but fails when the exact same query is executed through a JDBC-based application or data quality tool. Has anyone run into this? Was the issue related to query wrapping, session settings, SQL dialect differences, or JDBC driver behavior? How do you usually troubleshoot these cases? submitted by /u/No_Ambition8323 [link] [comments]
SDP-Meta Deep-Dive Demo: Building Data Pipelines at Scale on Databricks (w/ Databricks Sr. Staff FDE)
This s a helpful resource for those building pipelines at scale on Databricks. From the docs: SDP-META is a metadata-driven framework for Lakeflow Spark Declarative Pipelines . Define your Bronze and Silver pipelines in a JSON or YAML onboarding file — a single generic Declarative Pipeline reads the resulting DataflowSpec at runtime and builds the full processing graph automatically. No pipeline code to write. Who it's for: platform and data engineering teams standardizing repeatable Bronze/Silver pipelines across many datasets — onboarding new feeds through metadata instead of new pipeline code, with consistent data quality, quarantine, CDC, clustering, and sink patterns available through Bundles, CLI, UI, MCP, and agent workflows. When it's not the best fit: one or two simple pipelines, Gold-layer business modeling, tables that each need unique application logic, a managed connector and downstream logic that already satisfy the complete Bronze/Silver requirement, or a need for a formal support SLA (SDP-META is a Databricks Labs project). See the Introduction for the full positioning. You can find the project at https://github.com/databrickslabs/sdp-meta submitted by /u/JosueBogran [link] [comments]
Best practices for data quality in lakeflow
Choosing Data Governance Tools for Enterprise Data Governance
Governance tools enforce access control, quality checks, and lineage tracking at the platform layer, but their architecture ranges from standalone catalogs to platform-native suites, so matching the category to your underlying data stack is what prevents duplicate metadata layers and policy gaps. Evaluation criteria like policy enforcement granularity and AI/agent governance differ widely across tools, a gap that matters more as autonomous agents begin querying production data directly.
Data Mesh vs. Data Fabric: Key Differences and How the Lakehouse Resolves the Debate
Lakehouse architecture ends the mesh-versus-fabric tradeoff by pairing domain-owned data products with centralized governance enforcement, so teams ship analytics and ML products fast without fragmenting compliance. The result, per examples from financial services, healthcare, and retail, is better data quality and lower integration overhead alongside the accountability gains mesh ownership brings.
DQX Forge - Extension for DQX in Databricks
Hey guys, i'm just launched a VsCode extension for Data Quality proccess using DQX. The idea is simplify the process using AI (you can do it manually to). The extension construct data contracts, jobs and dashboards, all of that with few clicks and with less than 10 minutes. If you can, please, test and send me a feedback, so i can improve that. You can download directly in VsCode Extensions Marketplace, or https://marketplace.visualstudio.com/items?itemName=arthurfr23.dqx-forge https://preview.redd.it/peasj2p0ajkh1.png?width=3418&format=png&auto=webp&s=4b2b9c9dd3ca68c65a3c45fd08a6e793396d5dff submitted by /u/Significant-Side-578 [link] [comments]
 News
Databricks News: ZeroOps, DABs, Indexes, Genie, sandboxes, migration from PowerBI, secrets
Zero Ops automatically detects errors in jobs and data quality with lineage analysis and proposes code fixes, while DABs now default to direct mode instead of Terraform with automatic state migration. Full-text search indexes deliver 400x faster queries on billion-row tables, Genie automatically converts PowerBI dashboards to Databricks metric views, and Unity Catalog secrets support granular read and reference-only permissions.
Data quality Lineage Root cause analysis
 News
Ep 6: All About Genie App Builder | James Bentley
The video teaches how the Databricks Genie App Builder allows users to create governed, enterprise-ready applications using plain-language descriptions tied directly to Unity Catalog data. It demonstrates how features like app spaces and serverless micro apps enable scalable development while reducing infrastructure and governance challenges.
Data Quality Dashbaord - I have a requirement to build a custom designed quality dashboard in dbx
Top 10 AI Business Solutions Driving Company Growth
Discover the top 10 AI business solutions driving company growth, emphasizing the critical role of clean, governed data and strategic platform consolidation. Learn how successful organizations are achieving high returns by tying AI investments to specific business outcomes, avoiding common pitfalls like poor data quality and late governance.
Enterprise Data Strategy Roadmap for Business Outcomes
Connecting enterprise data assets to measurable business outcomes requires scalable architecture and analytics frameworks anchored in strong governance, data quality, and master data management. Delivering this through a phased pilot-to-scale roadmap, cross-functional teams, and data literacy initiatives ensures regulatory compliance and sustains a competitive data-driven culture.
Data Governance Architecture: A Complete Blueprint for Modern Organizations
This blueprint details a complete data governance architecture, outlining the policies, roles, and technologies needed to manage data assets. It emphasizes a modern strategy combining automated lineage, RBAC, and federated models to ensure data quality and regulatory compliance at scale.
Pipelines - how are you handling significant schema changes?
Hello - Right now with pipelines you can set things up so you can gracefully handle column additions and safe type conversions (more general type to more specific type). For things like column removals or downcasting, even the most liberal schema evolution setting will throw a failure and require the user manually triage by doing a full reload. I get why this is being done and I agree with the overall philosophy. We should lean on planning and communication because signifiant schema changes mean there is likely an impact downstream and/or to do data quality/meaning. But...... that means we have breaking changes that need to be triaged. In a scenario where we have separate Ops teams potentially operating in a different country, that means we would need to do "staged" failure and reprocessing of the various pipelines. EX: major change in pipeline A means it breaks and requires a full refresh. But A feeds B which feeds C which feeds D. In some situations, that means staged triaging of those expected failures (fix A, then fix B, then fix C, then fix D) - which means labor and perceived extended downtime. - How is everyone managing those kinds of situations? - Is there any possibility of ever setting the pipeline objects to allow for any form of schema change - falling back to a full load as a "last resort" so things auto-heal? (I get why this is not a great option, but at some point this feels like what we'd do manually anyway) Thank you!
When Spark Fails Silently: A JSON Parsing issue
One of the things I really appreciate about the **Databricks Community** is that it surfaces real-world edge cases you don’t usually find in documentation or tutorials. Some time ago, I came across an interesting discussion there involving a JSON parsing issue in **Apache Spark**. At first glance, everything looked straightforward - valid JSON, well-defined fields, no obvious data quality problems. And yet, Spark was returning a DataFrame with nulls. # The Case: When Valid JSON Still Breaks Spark The JSON structure in question looked roughly like this: * A **root array** * Containing **arrays of objects** * Each object representing a sensor state with attributes and timestamps In other words: **an array of arrays of structs**. [ [ { "entity_id": "sensor.solaredge_lifetime_energy", "state": "19848848.0", "attributes": { "state_class": "total", "unit_of_measurement": "Wh", "device_class": "energy", "friendly_name": "solaredge Lifetime energy" }, "last_changed": "2025-12-14T23:00:00+00:00", "last_updated": "2025-12-14T23:00:00+00:00" }, { ... } ], [ ... ] ] The user had defined an explicit schema and used Spark’s JSON reader in multiline mode -and Spark still produced an empty result set, without errors or warnings. Spark is tricky here because nothing actually breaks - it just fails quietly in the background. # Why This Happens The root cause here is a subtle detail in how Spark’s DataFrameReader handles JSON. Spark’s JSON reader is fundamentally designed around the idea that the input represents a **JSON object** at the root level. When that assumption holds, schema inference (or applying an explicit schema) works as expected. In this case, however, the JSON file does **not** start with a JSON object - it starts with a **JSON array**. More specifically, it’s an array whose elements are *themselves arrays* of objects. That difference matters. To illustrate: if the same content were wrapped inside a root-level object, Spark would have no trouble inferring the schema. For example, rewriting the file like this: { "data": [ [ { "entity_id": "sensor.solaredge_lifetime_energy", "state": "19848848.0", "attributes": { "state_class": "total", "unit_of_measurement": "Wh", "device_class": "energy", "friendly_name": "solaredge Lifetime energy" }, "last_changed": "2025-12-14T23:00:00+00:00", "last_updated": "2025-12-14T23:00:00+00:00" }, { "entity_id": "sensor.solaredge_lifetime_energy", "state": "19849120.0", "attributes": { "state_class": "total", "unit_of_measurement": "Wh", "device_class": "energy", "friendly_name": "solaredge Lifetime energy" }, "last_changed": "2025-12-14T23:15:00+00:00", "last_updated": "2025-12-14T23:15:00+00:00" }, { "entity_id": "sensor.solaredge_lifetime_energy", "state": "19849580.0", "attributes": { "state_class": "total", "unit_of_measurement": "Wh", "device_class": "energy", "friendly_name": "solaredge Lifetime energy" }, "last_changed": "2025-12-14T23:30:00+00:00", "last_updated": "2025-12-14T23:30:00+00:00" } […truncated]
Governing AI agents at scale with Unity Catalog
Unity Catalog now governs AI agents at scale, providing a unified layer for identity-aware access, runtime policies, and full auditability across all agent interactions. This extends data governance to AI systems, improving observability, compliance, and trust for models, servers, and data within the lakehouse.
Automate Data & KPI Monitoring with SQL Alerts
Databricks SQL Alerts is now Generally Available, enabling automated data quality and KPI monitoring that notifies owners whenever query results breach defined thresholds. Practitioners can author alerts using standard SQL or Genie Code, or run them inline as Lakeflow Jobs tasks to dynamically route downstream pipeline execution.
 Community
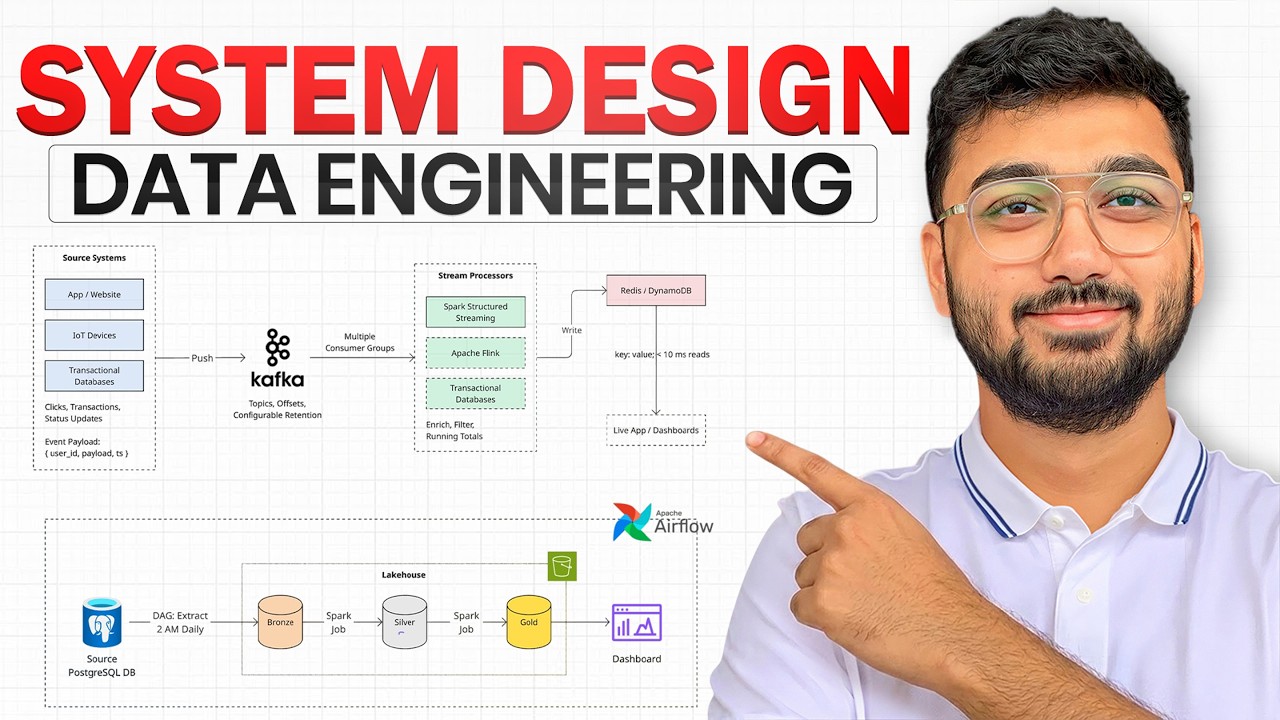
How I Mastered System Design Interviews
This video teaches a six-step framework for mastering data engineering system design interviews, covering requirements gathering, pipeline design, data modeling, storage and file formats, data quality and observability, and pipeline resilience. It demonstrates how to apply this framework with practical examples and back-of-the-envelope calculations to justify design choices.
 News
Data + AI Executive Series: Fast 5 — Scaling Real-Time Ops with Databricks at Aer Lingus
Aer Lingus uses Databricks to scale real-time operations, particularly for making critical decisions in their operation control center regarding flight delays and cancellations. They are also exploring using "Agentic" to automate business case creation and review, aiming for a single, governed platform for reusable agents.
Data quality is the AI strategy
Your AI strategy hinges on data quality, starting with fixes to transactional systems. Organizations prioritizing value creation with unified data will benefit most, as tools and models constantly evolve.
The next generation of Databricks Genie just launched. Here is what data engineers actually need to know.
I have been following Genie since it first launched with AI/BI last year. Back then, I honestly thought it was mostly for business users. A chatbot on top of your data that could answer basic questions in plain English. Useful, but not something I thought data engineers really needed to care much about. After seeing the new 2026 version, I completely changed my mind. Genie is no longer just a business chatbot. The biggest change is Genie Code, which is basically an AI agent designed for data professionals. It can generate pipelines, debug failures, create dashboards, monitor systems, and work directly with Lakeflow and Unity Catalog. That part caught my attention immediately because it moves beyond simple Q&A and starts touching actual engineering workflows. What surprised me most is how connected the whole system has become. It can pull context from dashboards, Genie Spaces, apps, metadata, documentation, and external systems like GitHub, Jira, and Confluence through MCP. Instead of only searching tables, it tries to understand relationships across the environment. That feels very different from the first version. The operational side is also interesting. Genie Code can monitor pipelines, investigate failures, help with DBR upgrades, and respond to issues before teams even notice them. The more I read about it, the more it felt less like a chatbot and more like an assistant sitting beside the engineering team. But honestly, the biggest takeaway for me is not the AI itself. It is what this means for data engineers. A lot of people immediately jump to “AI will replace data engineers,” but I think the opposite is happening. These systems are only as good as the data foundation underneath them. If metadata is incomplete, if tables are messy, if naming conventions are inconsistent, or if documentation is missing, the AI layer will give poor answers confidently. That means clean data modeling, governance, metadata, documentation, and data quality are becoming even more important than before. The engineers building those foundations become more valuable, not less. I think the role is slowly shifting away from spending hours writing repetitive boilerplate transformations and more toward building trustworthy, AI-ready data systems. One thing I keep noticing while learning Databricks through BricksNotes and the wider community is that the platform is moving very quickly toward AI-native data engineering. Features like Unity Catalog, Lakeflow, and now Genie all connect together. It feels like understanding metadata and governance is becoming just as important as understanding Spark itself. Also interesting that Genie now has a full mobile experience on iOS and Android. Business users can access dashboards, apps, and chat directly from their phones, which means the underlying data quality matters even more because people are going to depend on these systems everywhere, not only during work hours. Curious if anyone here is already using Genie or Genie Code in production. I would genuinely like to hear how the answer quality has been and whether your teams are changing how they approach metadata and documentation because of it.
Effective strategies to enhance data quality management
Effective data quality management requires evaluating pipelines against core dimensions like accuracy, freshness, and completeness while embedding automated testing from raw ingestion through production. Implementing pre-merge testing guardrails and tracking quantitative health metrics ensures engineering teams detect breaking transformation errors before they impact downstream consumers.
How data transformation improves data quality and analysis
Centralizing data transformation within modern ELT architectures improves analytical accuracy and data quality through systematic cleaning, normalization, and validation. Codifying this logic in authoritative, version-controlled models eliminates conflicting metrics across teams while providing reliable, reusable foundations for downstream machine learning and reporting.
Effective strategies to improve data quality across your organization
Databricks practitioners can improve data quality with proven strategies for testing, governance, and scalable analytics workflows. Learn how to implement these effective strategies across your organization.
 News
OpenClaw, Databricks Agentic Data Monitoring & more! | AI Newsround - February 2026 | Advancing AI
The video discusses OpenClaw, an open-source framework for AI agents, and Databricks' new agentic data quality monitoring solution. It also introduces Advancing Analytics' Lake Forge and Pantheon, a framework and AI layer for developing scalable Lake Flow pipelines, and highlights new model releases from Anthropic, Google, and OpenAI.
 News
Databricks Breaking News: 2026 Week 6: 2 February 2026 to 8 February 2026
Databricks introduces agentic data quality monitoring with anomaly detection, LLM judge UI builder for MLflow, and new SQL warehouse features including a default option and activity details. The platform also enhances its assistant to connect with MCP servers, improves Google Sheets integration with pivot table functionality, and adds direct Git deployment and tagging for Databricks apps.
 Events
Lakeflow Connect: The Game-Changer for Complex Event-Driven Architectures
ESA replaced their event-driven architecture with Lakeflow Connect to ingest Salesforce data more reliably, addressing issues like missed edge cases and schema inconsistencies. Lakeflow Connect offers incremental loading, automatic SCD2 history tracking, and serverless operation integrated with Databricks and Unity Catalog for robust data pipelines.
 News
Real-Time Analytics Pipeline for IoT Device Monitoring and Reporting
SEKA Delta built a real-time smart meter monitoring system using Databricks, Azure Logic Apps, and a medallion lakehouse architecture to track connectivity issues across 2 million+ meters in Ireland. The pipeline ingests streaming data from a push API, detects offline devices within minutes, and delivers live insights through AI BI dashboards for utility operators to respond quickly to outages and billing anomalies.
 News
Innovating Retail Data: Unilever’s Transformation with Databricks DLT
Unilever replaced its legacy data pipelines with Databricks Delta Live Tables using a medallion architecture, enabling serverless streaming, automated data quality checks, and unified governance through Unity Catalog. The migration delivered 25% infrastructure cost reduction, 200-500% faster data processing, and real-time analytics at scale.
 News
The Upcoming Apache Spark™ 4.1: The Next Chapter in Unified Analytics
Spark 4.1 introduces declarative pipelines for defining SQL and Python data workflows with automatic optimization and parallelization, plus real-time streaming mode achieving 100ms latency with 20-30x better performance than micro-batching. New features include SQL scripting, stored procedures, recursive CTEs, native geospatial data types, and a Variant type that is 8x faster than JSON.
 News
Lakeflow in Production: CI/CD, Testing and Monitoring at Scale
Lakeflow declarative pipelines simplify pipeline development by automatically handling dependencies and providing a new editor with testing, data previews, and code organization. Data asset bundles enable CI/CD automation through configuration files, allowing central data teams to deploy development and production pipelines with built-in safeguards like code reviews and data quality testing.
 Tutorials
Lakeflow Observability: From UI Monitoring to Deep Analytics
Lakeflow Observability provides a unified toolbox spanning discoverability, alerting, data quality monitoring, and root cause analysis across Databricks pipelines and jobs through query profiles, event logs, and custom SQL alerts. System tables enable monitoring at scale across workspaces with historical dashboards and near real-time latency for analyzing cost, performance, and systematic failures.
 News
Automating Engineering with AI - LLMs in Metadata Driven Frameworks
Data engineers must adapt to the AI revolution by using artificial intelligence to automate time consuming tasks like pipeline generation and data cleansing. Professionals should integrate AI coding assistants and metadata driven frameworks into their workflows to increase efficiency and remain competitive.
 News
Lakeflow Connect: Smarter, Simpler File Ingestion With the Next Generation of Auto Loader
Databricks introduced file events, a simplified file discovery mechanism for Auto Loader that eliminates complex permission configurations while supporting unlimited files per directory. The release also adds native SFTP and Excel support, improves schema evolution with type widening, and previews a managed file ingestion connector that automates Auto Loader configuration and operations.
 Tutorials
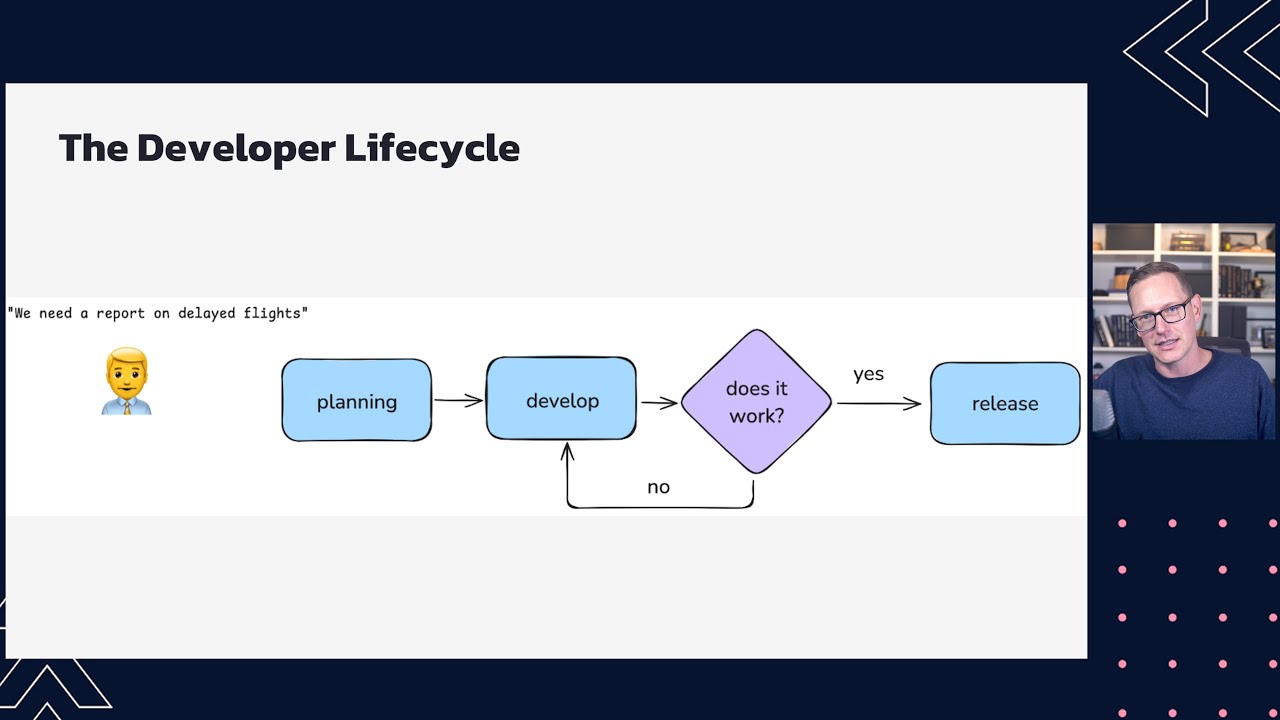
7 Best Practices for Development and CICD on Databricks
Seven best practices for development and CI/CD on Databricks are presented: version control, automated code testing, deployment to isolated environments, system health monitoring, data quality checks, automated schema deployments, and automated rollback on failures. These practices enable teams to deploy high-quality data pipelines with confidence and maintain strong governance throughout the development lifecycle.
 News
125. Databricks | Pyspark| Delta Live Table: Data Quality Check - Expect
Delta Live Tables in Databricks use expectations to perform data quality and validation checks on datasets using Python decorators or SQL constraints. Expectations consist of a constraint name, a validation logic definition, and a violation action of either warning, dropping invalid records, or failing the entire process.
 Tutorials
122. Databricks | Pyspark| Delta Live Table: Introduction
This video introduces Databricks Delta Live Tables as a declarative development framework designed to simplify and accelerate ETL pipeline creation. It details traditional pipeline challenges like complex medallion architectures, manual data quality checks, and difficult monitoring, while demonstrating how Delta Live Tables automate infrastructure management and error handling.
 News
Cross-Platform Data Lineage with OpenLineage
The presentation introduces OpenLineage as an open standard for collecting cross-platform data lineage metadata in real time to improve data observability and reduce troubleshooting friction. The speakers demonstrate how to configure and use OpenLineage with tools like Airflow, Spark, Flink, and dbt to track pipeline runs and visualize dependencies in Marquez.